About Christian Timmerer

Christian Timmerer is a researcher, entrepreneur, and teacher on immersive multimedia communication, streaming, adaptation, and Quality of Experience. He is an Assistant Professor at Alpen-Adria-Universität Klagenfurt, Austria. Follow him on Twitter at http://twitter.com/timse7 and subscribe to his blog at http://blog.timmerer.com.

Quality of Multimedia Experience in the Age of Generative AI

Generative AI Opens New Possibilities for QoE

Quality of Experience (QoE) has long been a central topic in multimedia research, providing a human-centered perspective on content quality, system performance, and user perception [Möller 2014]. Through subjective assessment, predictive modeling, and QoE-aware optimization, researchers have developed approaches to improving multimedia services under diverse network and resource constraints.

The rapid advancement of generative AI is changing how multimedia content is created, delivered, and experienced. Unlike conventional multimedia services, where content is typically prepared for users, generative AI enables content to be created, edited, and adapted in response to user needs. Through natural language instructions and iterative feedback, users can continuously refine their requests, bringing content creation, interaction, and consumption closer together. Meanwhile, content generation, model inference, user interaction, and delivery are becoming increasingly interconnected, expanding the opportunities for QoE assessment and optimization.

These developments raise new questions about how multimedia experiences are formed, how they can be assessed and modeled, and how QoE can guide generative AI systems toward better user experiences. This column explores these directions, as illustrated in Fig. 1, and discusses their implications for the future of multimedia services.
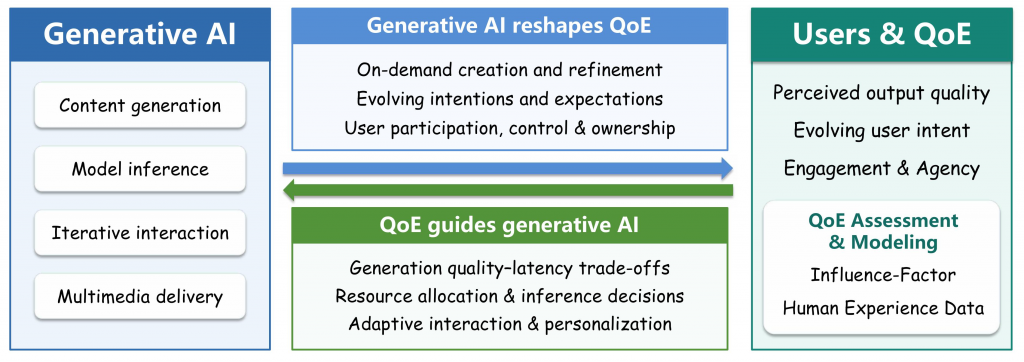
Figure 1: A conceptual framework illustrating how generative AI reshapes QoE through dynamic user interaction, while QoE assessment and modeling guide the optimization of generative AI systems toward more human-centered experiences.

How Generative AI is Transforming QoE

In traditional multimedia services, QoE primarily reflects users’ perceptions of delivered content and service quality [Möller 2014]. Advances in generative AI have enabled users to actively participate in content creation and refinement. Through natural language instructions and iterative feedback, users can shape generated content and build upon previous results, increasingly intertwining content quality with interaction experience. This shift gives users a greater role in shaping their own multimedia experiences.

Evolving User Intent and Expectations

Interactions with generative AI may lead to changes in users’ intentions and expectations. Initial generated results may inspire new ideas, encourage further exploration, or prompt users to reconsider their original goals. Subsequent interactions may further reshape both the generated content and users’ perceptions of the experience, creating a dynamic relationship among user intentions, system behavior, and perceived quality. Understanding this evolving relationship presents an important direction for QoE research in the age of generative AI.

Beyond Output Quality: User Engagement and Agency

In interactive generative AI applications, users’ experiences may depend on factors beyond output quality, such as their ability to express intentions, maintain control, explore alternatives, and develop a sense of ownership over the resulting content [Amershi 2019, Shneiderman 2020]. For example, a recent study found that model-led collaboration improved creative output quality but reduced idea diversity and users’ perceived ownership, while human-led approaches achieved a better balance among these aspects [Maier 2026]. Together, these developments suggest an evolving perspective on multimedia QoE, in which generated content, user participation, and interactive processes jointly contribute to the overall experience.

Rethinking QoE Assessment and Modeling

Perceptual quality assessment of AI-generated content has attracted growing research attention [Wang 2025]. The dynamic and interactive nature of generative AI experiences introduces new challenges, calling for new approaches to understanding and modeling QoE [Zhou 2026].

QoE Modeling based on Influence Factors

One promising approach is to identify key influence factors and investigate their relationships with QoE, building on established methodologies in traditional QoE research. These factors may include perceptual quality, semantic consistency, generation speed, response latency, and interaction characteristics. Controlled subjective experiments can help examine their effects and develop interpretable QoE models. Existing studies have explored QoE modeling for interactive LLM services using such approaches [Hupont 2026, Schlechte 2025]. However, the relevant factors and their relationships may vary considerably across different generative AI tasks and contexts, making such models difficult to generalize.

QoE Modeling from Human Experience Data

Advances in foundation models offer another approach to QoE modeling by learning directly from human experience data. Such data may include multimodal content, interaction histories, user feedback, and contextual information, which could be used to train AI-based QoE predictors that approximate human QoE judgments. However, since QoE fundamentally concerns human experience, continuous validation against real human feedback is essential to prevent the evaluation objective from shifting toward model preferences.

How QoE can Guide Generative AI Systems

QoE has long guided multimedia service optimization, including adaptive streaming and resource allocation, to balance perceived quality and system constraints [Seufert 2014]. Generative AI further expands this optimization space by allowing QoE to influence content generation itself, alongside inference, interaction, and delivery. With reliable QoE models, generative AI systems could make decisions based on anticipated user experience, such as balancing generation quality against response time, allocating resources according to user needs, or adapting interaction strategies to different tasks. Recent studies have explored using human-aligned quality assessments as reward signals to improve generative video models [Wang 2025 (LOVE)], suggesting the potential for extending such approaches toward broader QoE-driven optimization. Looking ahead, QoE could become an integral part of generative AI systems, guiding how content is created, refined, and delivered in response to user expectations. This would open opportunities for connecting human experience with generative model development and intelligent service optimization.

Outlook and Takeaways

The rapid development of generative AI is opening new directions for QoE research. Generative AI is reshaping how users create and experience multimedia content, calling for new approaches to understanding and modeling dynamic user experiences. Meanwhile, QoE offers a human-centered perspective to guide content generation, interaction, and system optimization. Looking ahead, QoE-in-the-loop generative multimedia represents a promising direction for enabling more adaptive, personalized, and experience-driven services.

This vision aligns closely with the discussions envisioned for QoMEX’27, which will explore the evolving landscape of quality of multimedia experience in the age of generative AI. As generative technologies reshape how multimedia is created, delivered, and experienced, the conference invites the research community to explore emerging challenges and opportunities in QoE assessment, modeling, and optimization, and to advance more human-centered multimedia systems.

These directions reflect the expanding scope of QoE research and reaffirm QoMEX as an important forum for exchanging ideas and advancing multimedia experience research. The 19th International Conference on Quality of Multimedia Experience (QoMEX’27) will take place in Shanghai, China, from July 6 to 9, 2027. More information is available at https://qomex2027.itec.aau.at/.

References

  • [Möller 2014] Sebastian Möller and Alexander Raake. 2014. Quality of experience. Springer.
  • [Amershi 2019] Saleema Amershi, Dan Weld, Mihaela Vorvoreanu, Adam Fourney, Besmira Nushi, Penny Collisson, Jina Suh, Shamsi Iqbal, Paul N. Bennett, Kori Inkpen, Jaime Teevan, Ruth Kikin-Gil, and Eric Horvitz. 2019. Guidelines for Human-AI Interaction. In Proceedings of the 2019 CHI Conference on Human Factors in Computing Systems (CHI ’19). Association for Computing Machinery, New York, NY, USA, Paper 3, 1–13. https://doi.org/10.1145/3290605.3300233
  • [Shneiderman 2020] Shneiderman, B. 2020. Human-Centered Artificial Intelligence: Reliable, Safe & Trustworthy. International Journal of Human–Computer Interaction, 36(6), 495–504. https://doi.org/10.1080/10447318.2020.1741118
  • [Maier 2026] Sebastian Maier, Manuel Schneider, and Stefan Feuerriegel. 2026. Partnering with Generative AI: Experimental Evaluation of Model-Led and Human-Led Interaction in Human-AI Co-Creation. In Proceedings of the 2026 CHI Conference on Human Factors in Computing Systems (CHI ’26). Association for Computing Machinery, New York, NY, USA, Article 1260, 1–28. https://doi.org/10.1145/3772318.3791185
  • [Wang 2025] Jiarui Wang, Huiyu Duan, Guangtao Zhai, Juntong Wang, and Xiongkuo Min. 2025. AIGV-ASSESSOR: Benchmarking and Evaluating the Perceptual Quality of Text-to-Video Generation with LMM. In 2025 IEEE/CVF conference on computer vision and pattern recognition (CVPR). IEEE, 18869–18880. https://doi.org/10.1109/CVPR52734.2025.01758
  • [Zhou 2026] Wei Zhou, Hadi Amirpour, Tobias Hoßfeld, and Christian Timmerer. 2026. Quality of Multimedia Experience Meets Machine Intelligence. SIGMultimedia Rec. 18, 1, Article 3 (January 2026), 1 pages. https://doi.org/10.1145/3811013.3811016
  • [Hupont 2026] Isabelle Hupont, Katrien De Moor, Lea Skorin-Kapov, Martin Varela, Tobias Hoßfeld, and Christian Timmerer. 2026. Rethinking QoE in the Age of AI: From Algorithms to Experience-Based Evaluation. SIGMultimedia Rec. 17, 4, Article 3 (October 2025), 1 pages. https://doi.org/10.1145/3811005.3811008
  • [Schlechte 2025] Florian Schlechte, Yusra Tasnim Farooqi, and Matthias Hirth. 2025. Assessing the Influence of End-to-End Request Latency and Response Length on Waiting Time Satisfaction of LLM Users. In 2025 17th International Conference on Quality of Multimedia Experience (QoMEX). IEEE, 1–4. https://doi.org/10.1109/QoMEX65720.2025.11219949
  • [Seufert 2014] Michael Seufert, Sebastian Egger, Martin Slanina, Thomas Zinner, Tobias Hoßfeld, and Phuoc Tran-Gia. 2014. A Survey on Quality of Experience of HTTP Adaptive Streaming. IEEE Communications Surveys & Tutorials 17, 1 (2014), 469–492. https://doi.org/10.1109/COMST.2014.2360940
  • [Wang 2025 (LOVE)] Jiarui Wang, Huiyu Duan, Ziheng Jia, Yu Zhao, Woo Yi Yang, Zicheng Zhang, Zijian Chen, Juntong Wang, Yuke Xing, Guangtao Zhai, et al. 2025. LOVE: Benchmarking and Evaluating Text-to-Video Generation and Video-to-Text Interpretation. arXiv preprint arXiv:2505.12098 (2025). https://doi.org/10.48550/arXiv.2505.12098
MPEG Column: 156th MPEG Meeting

At the 156th MPEG meeting in Hangzhou, China, MPEG Video Coding (WG 4) advanced Video Coding for Machines (VCM, ISO/IEC 23888-2) to Final Draft International Standard (FDIS) and Feature Coding for Machines (FCM, ISO/IEC 23888-4) to Draft International Standard (DIS). VCM compresses video for analysis after decoding, while FCM compresses the intermediate features exchanged between parts of a model. In parallel, MPEG Systems (WG 3) is exploring how to package both types of bitstream for storage and delivery. The full press release is available here.

Video Coding for Machines

VCM combines a conventional video codec with tools that adapt the video before encoding and process the decoded signal before analysis. An encoder can reduce spatial resolution, transmit fewer frames, or allocate more bits to regions that matter for the downstream task. The receiver can then apply operations such as upsampling or frame synthesis before passing the reconstructed video to the vision model [Eimon 2026].

In resolving comments on the VCM draft, WG 4 addressed the delivery of neural network weights and set an upper limit on the number of regions of interest. The group also updated the reference software so that the VCM multiplexer and demultiplexer can operate independently of the Versatile Video Coding (VVC) Test Model. This allows the reference pipeline to use an alternative inner codec such as High Efficiency Video Coding (HEVC). Other updates configure bit-depth restoration automatically based on day or night conditions and add supplemental signaling related to decoder timing and buffering. WG 4 also established a study on verification testing.

Feature Coding for Machines

The input to an FCM encoder is a feature tensor, an array of activations produced by the first part of a model. The encoder can transform the tensor into a more compact representation and quantize its values for transmission. The receiver reconstructs the tensor and passes it to the remaining layers. The split point affects how much computation each device performs, how much data the sender transmits, and which features are available to downstream tasks [Eimon 2026, Yang 2024].

The FCM DIS specifies the bilinear interpolation used in reconstruction and the bit widths of floating-point syntax elements. Its levels account for the neural network used to invert the feature transform and the size of the transformed tensor. WG 4 also simplified parts of the reconstruction network, introduced lower-complexity integer convolution, and adapted feature refinement to the distribution of the reconstructed values. The draft supports temporal scalability and aligns the ordering of picture-level metadata with that of the inner coded data to support random access.

Separately, WG 4 updated channel rearrangement and nonlinear quantization in the FCM Test Model and introduced a method based on singular value decomposition to estimate channel importance. The group updated the Common Test and Training Conditions with a single-layer feature-transform configuration, 4:2:0 input for the HEVC Main 10 inner codec, and a revised configuration for the Neural Network Coding (NNC) inner codec. Further studies will examine FCM levels and deterministic operation for conformance testing.

Systems Carriage for VCM and FCM

Through the Exploration on Systems technology for AI-based media standards (SyfAI), MPEG Systems (WG 3) is studying how to carry VCM and FCM bitstreams. The Hangzhou outputs include separate preliminary carriage drafts for VCM and FCM [MPEG156]. The VCM proposal describes how to package single-layer VCM streams in the ISO Base Media File Format (ISOBMFF, ISO/IEC 14496-12), either as a file for storage or as an initialization segment followed by media segments for streaming.

The VCM proposal also describes how the container conveys timing and decoder configuration. An inner-coded picture and its restoration data share the same timed sample. A picture synthesized at the decoder has its own timed sample carrying the synthesis instructions. The proposed configuration box carries initialization information for both VCM and its inner codec.

Offshore Wind Turbine Inspection

When several inspection drones share a limited wireless link, the choice of what to send depends on how much analysis each drone can perform onboard and what the ground station needs to combine observations from different cameras.

DORBINE [DORBINE], a collaboration between the University of Klagenfurt and AIR6 Systems funded by the Austrian Research Promotion Agency (FFG), aims to inspect wind turbine blades while the turbines continue generating power. In their IEEE Access paper, Leopold et al. describe how several drones divide the work of observing the turbine, capturing close-up blade imagery, and measuring blade deflection. A ground station coordinates the drones and combines data from their cameras. Experiments on a scaled turbine model demonstrated persistent blade identification and deflection estimation during rotation [Leopold 2026].

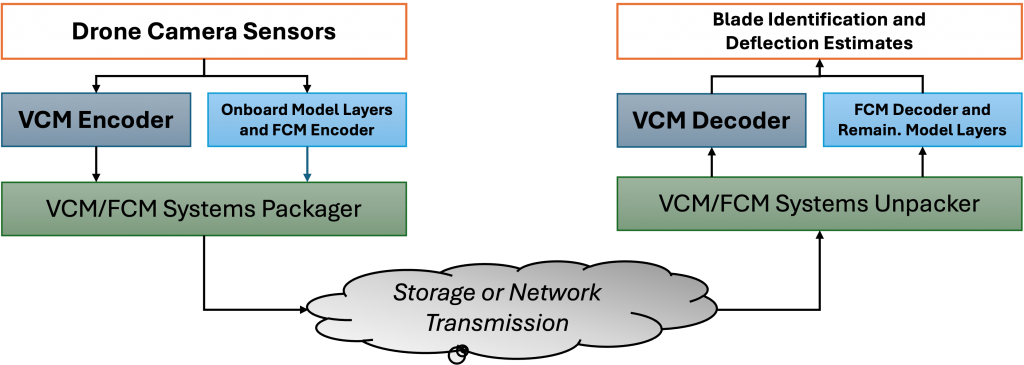
Figure 1 shows how VCM and FCM could fit into a DORBINE-style inspection. In the VCM path, the drone encodes video, and the ground station reconstructs the frames and runs the full inspection model. In the FCM path, the drone runs the first layers of the model and encodes their output. The ground station reconstructs those features and runs the remaining layers. In both paths, the sender packages the bitstream for storage or transmission, and the receiver extracts it and passes it to the appropriate decoder.

Figure 1: Proposed VCM and FCM workflow for drone-based wind turbine inspection. Both paths support blade identification and deflection estimation at the ground station.

Research Directions for the ACM SIGMM Community

Compression for machine accuracy and human review. How much can VCM reduce bitrate while preserving small-defect recall and keeping deflection estimates within a target error? Compare how encoders allocate bits across blade regions and frames, and assess whether engineers can verify suspected defects from selected clips [Eimon 2026].

Adaptive split inference. When should a drone send VCM video, transmit FCM features, or run the full model onboard? Replay the same inspection under different network conditions and onboard compute budgets. Compare bitrate, time to result, and onboard energy per inference at comparable task performance [Eimon 2026].

Feature reuse across tasks and model versions. Can one compressed feature stream support blade identification, surface defect detection, and deflection estimation? Test which tasks can share a representation and whether a ground-station model can be upgraded while remaining compatible with feature extractors already deployed on drones [Yang 2024].

Coordinated coding across drones. When several drones observe the same rotating blade over a shared uplink, which views should receive more of the available bitrate? Compare independent encoding with a scheduler that prioritizes complementary views. Measure how synchronization errors, missing views, and compression affect the combined estimate [Leopold 2026].

Carriage and recovery under variable network conditions. What information does a receiver need to join a live stream, recover after segment loss, or resume inference after a configuration change? Measure the time to the first usable result and the effect of stale or missing inputs on the inspection outcome [MPEG156].

Reproducible end-to-end benchmarks. Pair synchronized footage and task annotations with recorded network traces. Compare conventional video coding with remote inference, VCM, FCM, and fully onboard inference on the same source material. Hold out entire turbines or flights to test whether the results generalize beyond the sequences used for tuning.

Concluding Remarks

The Hangzhou milestones give the multimedia research community a basis for evaluating coding, inference, and delivery together. Offshore wind turbine inspection offers a concrete test of whether these technologies can deliver reliable blade measurements within the bandwidth and energy available during a flight.

The 157th MPEG meeting will be held in Brisbane, Australia, from January 18 to 22, 2027. Click here for more information about MPEG meetings and ongoing developments.

References

MPEG Column: 155th MPEG Meeting

The 155th MPEG meeting took place in Geneva, Switzerland, from July 13 to 17, 2026. The official MPEG press release can be found here. This report highlights key outcomes from the meeting, with a focus on research directions relevant to the ACM SIGMM community:

  • Gaussian Splat Coding Use Cases and Current Status
  • Call for Proposals on Media Authenticity and Provenance Indication
  • Joint Call for Proposals on video compression with capability beyond VVC
  • Joint ITU-T SG 21 and ISO/IEC JTC 1/SC 29 Workshop on Media Streaming Services
  • Exploration on Systems technologies for AI-based media standards (SyfAI)

Gaussian Splat Coding Use Cases and Current Status

The previous MPEG column [MPEG154] introduced MPEG’s Gaussian Splat Coding (GSC) exploration, its two tracks (I-3DGS and A-3DGS), and a first set of 27 draft use cases. At the 155th meeting, WG 2 (Technical Requirements) approved an updated document (WG 2 N531) that drops the draft qualifier and adds two use cases.

The additions matter less for their number than their nature: both concern storage and delivery rather than compression. Use case 28 stores a static splat asset in a single file together with a cover image, thumbnail, and audio annotation, so that a capable receiver renders it interactively while a legacy receiver displays the cover image, with no modification of the file. Use case 29 is the temporal counterpart, delivering a dynamic splat track by HTTP adaptive streaming alongside synchronized audio, a pre-rendered video track serving as preview and fallback, and timed text, with representations offered per bitrate, level of detail, spherical harmonics subset, or attribute subset. The application-oriented use cases are unchanged, although the derived requirements are being refactored, notably by separating attribute subset scalability from random access.

GSC remains an exploration activity, but a busy one: 83 input contributions and nine Joint Exploration Experiments re-conducted across WG 2, WG 4 (Video Coding), WG 5 (Joint Video Experts Team, JVET), and WG 7 (3D Graphics and Haptics), with WG 1 (JPEG) now engaged on quality metrics and WG 4 examining Neural Network Coding (NNC) as a compression tool. On the fast track, GS4 (Video-based Point Cloud Compression, V-PCC, Amd. 1) and GS5 (Geometry-based Point Cloud Compression, G-PCC, Amd. 1) progress on reference software and conformance, while the JVET codec track carries five competing proposals. The Call for Proposals (CfP) still has no date, and I-3DGS planning is more mature than A-3DGS. The clearest message from the meeting is that single-frame compression is essentially solved and that the difficulty and the expected gain now lie in dynamic content.

Research aspects: Temporal coding is no longer one open question among many, but the central one, covering inter-prediction for anisotropic primitives, deformation models, and primitive correspondence across frames. Quality assessment remains unresolved: current test conditions score rendered views with peak signal-to-noise ratio (PSNR), structural similarity (SSIM), and learned perceptual image patch similarity (LPIPS) along a pose trace, a fragile proxy for artifacts such as floaters and popping; the involvement of JPEG makes this a good moment to contribute. Use case 29 gives the streaming question a concrete form: when quality varies along several orthogonal axes at once, what is the right abstraction for a representation, and what should an adaptation algorithm optimize?

Call for Proposals on Media Authenticity and Provenance Indication

At the 155th meeting, WG 2 approved a CfP on media authenticity and provenance indication with the MPEG Systems technologies (WG 2 N535), following an exploration phase in WG 3 (Systems) that produced requirements, a gap analysis, and several technical proposals (WG 3 N1842, attached to the call). The scope is the system layer: carriage and signaling of metadata that allows a receiver to verify that a media asset comes from a trusted producer and to convey provenance information, rather than the definition of a provenance language itself.

Three interfaces are addressed, namely (i) elementary streams and non-timed items, (ii) the file format level (ISO Base Media File Format (ISOBMFF) and Common Media Application Format (CMAF)), and (iii) packaged delivery (Dynamic Adaptive Streaming over HTTP (DASH), CMAF, MPEG Media Transport (MMT), and MPEG-2 Transport Stream (MPEG-2 TS)). The use cases span deepfakes and manipulated news media, forgery in insurance claims, surveillance and investigations, labeling of AI-generated content, and legitimate modifications such as editing, transcoding, ad insertion, and archival preservation. Detecting whether an asset is fake without embedded data is explicitly out of scope.

A response may be a complete solution or a single tool addressing one or more requirements, and is evaluated on requirement coverage, computational complexity, the bandwidth needed to convey the authenticity information, compatibility and backward compatibility with existing MPEG standards, and extensibility, with self-evaluation tables provided in the annexes. Proposals are submitted as input contributions to the 157th meeting in Brisbane, Australia, by January 13, 2027. Review at that meeting will produce one or more working drafts or new work item proposals, and the preliminary development plan targets Committee Draft (CD) or Committee Draft Amendment (CDAM) at the 158th meeting, Draft International Standard (DIS) or Draft Amendment (DAM) at the 159th, and Final Draft International Standard (FDIS) or Final Draft Amendment (FDAM) in early 2028.

Research aspects: The requirements make this more interesting than a signing exercise. A conventional signature breaks on any bit change, yet the call demands that verification survive transcoding, dropped scalability layers, representation switching, splicing, late binding, and loss of frames or audio, and that the unmodified remainder of a presentation stay verifiable after an authorized edit. Designing verification structures with that granularity and quantifying their overhead per segment against the added latency in live scenarios is an open problem at the intersection of cryptography and streaming systems. A second question is joint verification: establishing that a given audio track was the one the producer intended to accompany a given video, including their synchronization, cannot be achieved by signing each file separately. Finally, interoperability with provenance schemes defined elsewhere, and the question of what a receiver should do with a verification result, leave room for work on usable trust signaling.

Joint Call for Proposals on Video Compression with Capability Beyond VVC

The draft of this call was described in the previous MPEG column [MPEG154], and JVET has now issued the final version (JVET-AQ2021 [JVET-AQ2021]), approved at its 43rd meeting in Geneva in July 2026. The target is video coding technology that significantly exceeds Versatile Video Coding (VVC) in compression, implementability, applicability across content types, and features such as latency, robustness, and scalability, benchmarked against the VVC Main 10 profile. Four test cases are defined: one for improved compression without runtime limits, and three in which the aggregate encoder run time is constrained to 5x, 1x, and 0.2x that of the VVC Test Model (VTM) anchor. All are evaluated over seven categories covering (i) standard dynamic range (SDR) random access at ultra-high definition (UHD) and (ii) at high definition (HD), (iii) SDR low delay HD, (iv) high dynamic range (HDR) with perceptual quantizer (PQ) and (v) with hybrid log-gamma (HLG) transfer functions, (vi) gaming, and (vii) user-generated content. A separate track invites technology offering additional functionality, together with proposals on how its benefit should be assessed.

Formal subjective testing uses degradation category rating, with objective results reported as PSNR, multiscale SSIM (MS-SSIM), and, for PQ content, weighted PSNR. The schedule is tight: anchors have been available since May 2026, registration runs from August 1 to September 1, 2026, and the main package of bitstreams, reconstructed sequences, and binaries must reach the test coordinator on physical media by October 26, 2026. Subjective assessment then runs until late December, blind cross-checking by other proponents is mandatory, and proposals are evaluated at the 45th JVET meeting in January 2027, with an initial test model selected during 2027 and the standard targeted for October 2029. Participation is not free: up to EUR 20k per test case is charged to cover the hiring of test subjects.

Research aspects: Two design choices in the call are worth attention. First, a supplemental set of sequences is disclosed to proponents only after the decoder binaries have been submitted, and results on it are due six weeks later, which turns the call into a held-out generalization test. Read together with the ban on training on test sequences and the obligation to disclose training material, this makes out-of-domain behavior of learned coding tools measurable at scale, and reporting it well is a contribution in itself. Second, run time is aggregated as the sum over threads, which measures total compute rather than latency and therefore reads very differently for a massively parallel or GPU-resident design than for a sequential one. How to characterize the rate, distortion, and complexity trade-off fairly across such architectures, and how to value functionality such as scalability or error resilience against a plain bitrate gain, are open questions the call poses rather than answers.

Joint ITU-T SG 21 and ISO/IEC JTC 1/SC 29 Workshop on Media Streaming Services

On July 14, 2026, ITU-T SG 21 and MPEG Systems held a joint half-day workshop in Geneva, collocated with their meetings, on “Media Streaming Service, What’s next” (call for presentations, program). The premise was that after the transitions from analog to digital, enabled by MPEG-2 Systems, and from broadcast to over the top (OTT), enabled by MPEG-DASH, integrated networks, edge computing, and AI are driving another shift, and that both bodies wanted industry views before committing to new work. On challenges, Netflix spoke on the shortcomings and evolution of ISOBMFF, Bitmovin on where streaming trends meet the container, ETRI on future streaming services, and Huawei on ultra-low latency communication and streaming. On opportunities, 5G-MAG addressed standards and open source, DVB heterogeneous networks, and 3GPP SA4 delivery beyond OTT. The closing session was an open mic with questions and answers from both speakers and the audience.

The wrap-up set the existing systems standards, namely MPEG-2 TS, ISOBMFF, DASH, and CMAF as well as the volumetric, scene, and augmented reality (AR) formats, plus ongoing work on authenticity, SyfAI (see below), common metadata, and Gaussian splats, against what industry actually asked for: low latency, low overhead, AI-driven media, and open source software. The resulting agenda is an exploration of a better or new container format, an analysis of overhead, processing-friendly metadata, including JSON and ontology issues, WebCodecs integration, and ingest. Just as notable are the conclusions about process: more open access and industry involvement, faster turnaround, possibly a new home or outlet for this work, and software with interoperability testing from day one rather than reference software at the end. Three ad hoc groups were set up: (i) on MP4, DASH, and file formats, reviewing ISOBMFF against emerging transports and the delivery of AI input and output data; (ii) on vision, analyzing bottlenecks and requirements beyond ISOBMFF; and (iii) on working methods.

Research aspects: Two of these items are directly researchable. Container overhead is asserted more often than measured, and as segments shrink toward frame level for low latency, the ratio of container to media bytes grows; a careful comparison across ISOBMFF, CMAF, and object-based transports at equal latency would inform the exploration rather than follow it. Media over QUIC (MOQ) is the bigger change, since it replaces the segment with the object as the unit of delivery and pulls streaming and real-time communication into a single design space, which reopens rate adaptation, interaction with congestion control, caching, and relay behavior, and the question of what a container still contributes when the transport itself frames media. Carrying AI input and output data alongside media, finally, links this work to coding for machines and to semantic streaming.

Exploration on Systems Technologies for AI-based Media Standards (SyfAI)

Several MPEG coding standards now put a neural network inside the decoder, among them video and feature coding for machines, AI-based point cloud coding, and neural network coding. The previous MPEG column [MPEG154] described that coding side through the MPEG-AI vision document. SyfAI, an MPEG Systems exploration started at the 153rd MPEG meeting, asks the complementary and much less glamorous question: what does the surrounding infrastructure have to do so that such content can actually be stored, delivered, and played back interoperably? The underlying shift is that a media file has traditionally been self-contained, meaning that a conforming decoder and the bitstream are sufficient. Once the decoder depends on a trained model that may be selected, delivered, or updated separately, that assumption no longer holds, and the system layer has to say how a player learns which model it needs, how that model reaches it, and how both sides can be sure they are using the same one. Work so far has advanced on the most concrete piece, namely storing video coding for machines content in the MPEG file format, while proposals for carrying compressed neural networks were sent back for clearer use cases. The more interesting development is a new thread on an AI update framework, opened jointly with WG 7, which collects five topics: (i) a format for AI parameter data, (ii) a manifest for updating parameters, (iii) a repository to serve them, (iv) integrity checking, and (v) bit exactness together with conformance.

Research aspects: Each of those topics is a research problem in its own right. Distributing and updating models alongside media turns into a delivery question that looks familiar but has not been studied: when to fetch an update, how to cache and version models, what a manifest must express about capability and compatibility, and how to treat weights as a second class of asset next to the media. Conformance is harder, because a standard normally guarantees that every decoder produces identical output, whereas neural inference varies with library and hardware, so deciding what conformance means and how to test it remains open and extends the reproducibility concerns already visible in MPEG-AI. A repository of updatable weights is also an attack surface, which is why this work sits naturally beside the media authenticity call discussed above: signing and verifying a model raises the same questions one level down from signing content. And because the choice of where a model lives affects how quickly playback can start and how smoothly a player can switch, the apparently dry container questions have measurable consequences for the quality of experience (QoE).

Concluding Remarks

Taken together, the five items show MPEG engaging early with technologies whose momentum comes from outside the committee. With Gaussian splatting, it is compressing a representation that already has a renderer and a user base, which is a better starting point than earlier attempts at three-dimensional video had, even if wider adoption will depend on capture and display ecosystems as much as on coding efficiency. The authenticity call is scoped pragmatically at establishing origin, which is achievable in the near term and provides the system-level plumbing that regulation and industry are asking for. The call for video coding beyond VVC visibly reflects deployment experience, with runtime-constrained test cases treating practicality as a first-class criterion, while questions of licensing and market uptake sit largely outside MPEG itself. In systems, the joint workshop and the new ad hoc groups show a willingness to re-examine long-standing assumptions as transports such as MOQ emerge, and SyfAI stakes out the system-level questions of the AI era before they become urgent. For our community, the result is an unusually rich set of open problems in evaluation and methodology.

The 156th MPEG meeting will be held in Hangzhou, China, from October 19 to 23, 2026. Click here for more information about MPEG meetings and ongoing developments.

References

  • [MPEG154] C. Timmerer. 2026. MPEG Column: 154th MPEG Meeting. SIGMultimedia Rec. 18, 2, Article 8 (April 2026).
  • [JVET-AQ2021] J.-R. Ohm, M. Wien, F. Bossen. 2026. Joint Call for Proposals on video compression with capability beyond VVC, JVET-AQ2021 (July 2026).

MPEG Column: 154th MPEG Meeting

The 154th MPEG meeting took place in Santa Eulària, Spain, from April 27 to May 1, 2026. The official MPEG press release can be found here. This report highlights key outcomes from the meeting, with a focus on research directions relevant to the ACM SIGMM community:

  • Exploration on MPEG Gaussian Splat Coding (GSC)
  • Draft Joint Call for Proposals: Video Compression Beyond VVC
  • Energy-aware Streaming in MPEG-DASH
  • MPEG-AI: Vision and Scenarios for Artificial Intelligence in Multimedia
  • MPEG Roadmap

Exploration on MPEG Gaussian Splat Coding (GSC)

The MPEG WG 2 Technical Requirements group — jointly with WG 4 (Video Coding), WG 5 (JVET: Joint Video Coding Team(s) with ITU-T SG 16), and WG 7 (Coding of 3D Graphics and Haptics) — made progress toward standardizing Gaussian Splat Coding (GSC) regarding draft requirements and use cases subject to change. Gaussian splatting, first introduced in a landmark 2023 ACM SIGGRAPH paper by Kerbl et al. [Kerbl2023], represents 3D scenes as collections of anisotropic Gaussian primitives carrying geometry (x, y, z positions) and appearance attributes (opacity, scale, rotation, and spherical harmonics coefficients for view-dependent color), enabling photorealistic novel-view synthesis with real-time rendering. Because raw Gaussian splat data can be extremely large and the ecosystem of proprietary formats (.ply, .splat, .spz, etc.) is fragmented, MPEG has identified a clear need for interoperable, efficient compression standards. Two exploration tracks are currently being pursued: I-3DGS, which operates on Gaussian splats in the well-established “INRIA” format as a symmetric encode/decode pipeline, and A-3DGS, which allows alternative learned representations and training-integrated approaches.

The draft requirements, still evolving, currently cover representation, coding, and system aspects across both tracks, with an additional lightweight profile targeting resource-constrained devices such as mobile phones (Snapdragon 8 Gen 3/Elite) and HMDs (Snapdragon XR Gen2, e.g., Meta Quest 3). Among the coding requirements under consideration are lossy and lossless compression with variable bitrate, spatial and temporal random access, progressive and scalable decoding (quality, Level of Detail (LoD), attribute subsets), and error resilience. Notably, a lightweight profile currently proposes hard complexity constraints (i.e., real-time encode/decode on 2024/2025 mobile hardware, a 2GB runtime memory cap, and at most four concurrent video decoder sessions) reflecting MPEG’s intent to enable a fast-deployment path for interoperable interchange and storage of static Gaussian splat assets. Alongside the requirements, a draft set of 27 use cases has been identified, spanning consumer XR (telepresence, gaming, social media, retail), professional media (movie production, sports broadcasting, immersive journalism), industrial applications (digital twins, Building Information Modeling (BIM), structure inspection, disaster assessment), and emerging hybrid representations such as Gaussian splats attached to deformable meshes for avatar animation and rigging. Several of these use cases are motivating draft requirements around primitive ordering preservation and stable identifier signaling for external metadata associations, though the details of these provisions may still change.

Research aspects: Even at this early draft stage, the direction of MPEG’s GSC work opens a rich set of research opportunities. On the compression side, the dual-track structure raises open questions around rate-distortion-complexity optimization for both geometry-based and video-codec-based pipelines, including temporally coherent coding of dynamic (tracked and non-tracked) Gaussian sequences and attribute-group-aware progressive coding. The QoE angle is equally pressing: no widely accepted perceptual quality metric yet exists for 6DoF Gaussian splat rendering, and the community can contribute splat-artifact-aware metrics, view-consistency measures, and subjective evaluation methodologies. The envisioned lightweight profile points to a need for co-design of decoders and real-time renderers targeting mobile GPU architectures, offering opportunities in GPU-friendly bitstream layouts and LOD-driven streaming. From a systems and networking perspective, the spatial and temporal random-access provisions, combined with the breadth of use cases demanding adaptive streaming to diverse devices (HMDs, phones, TVs, browsers), map naturally onto adaptive bitrate research, ROI- and view-dependent segment delivery, and loss-resilient transmission of splat parameters. Finally, the emerging use cases around hybrid mesh-Gaussian avatars, scene editing, and semantic metadata associations introduce new multimedia content management and interactive media challenges that go well beyond traditional video streaming and are squarely within the scope of ACM SIGMM’s research community.

Draft Joint Call for Proposals: Video Compression Beyond VVC

MPEG’s Joint Video Experts Team (JVET) — operating jointly under ITU-T SG21 and ISO/IEC JTC 1/SC 29 — advanced a draft Joint Call for Proposals (CfP) for a new generation of video compression technology with capabilities that would substantially exceed those of the current Versatile Video Coding (VVC) standard (Rec. ITU-T H.266 | ISO/IEC 23090-3). The final CfP is planned for July 2026, with proposal submissions evaluated at a JVET meeting in January 2027 and a tentative target of a completed standard by October 2029. The overarching goal is to solicit compression technology that significantly improves upon VVC’s Main 10 Profile in terms of rate-distortion performance, encoder/decoder implementability, applicability to diverse content types, and additional features such as low latency, error robustness, and scalability, while explicitly recognizing that practical fast encoding is increasingly important across a growing range of applications.

The draft CfP defines four test cases. The primary test case targets improved compression without runtime constraints, spanning several content categories: SDR random-access at UHD/4K and HD resolutions, SDR low-delay HD (targeting conversational and gaming applications), HDR content under both PQ and HLG transfer functions at UHD, gaming low-delay HD, and user-generated content. Three additional test cases impose encoder runtime constraints relative to the VVC Test Model (VTM) reference encoder, enabling JVET to characterize the compression-versus-speed trade-off across submissions. Formal subjective evaluation will follow the degradation category rating (DCR) methodology per ITU-R BT.500. Importantly, the CfP explicitly addresses neural and learned components: proponents must disclose what training data was used and are prohibited from using any test sequence as training material, and source code (incl. training scripts or parameter derivation procedures) must be made available for accepted technologies entering the core experiments process. The draft notes that specific test sequences and target bitrates may still change before the final CfP is issued.

Research aspects: The runtime-constrained test cases create a natural framework for studying the compression-complexity Pareto frontier for both classical and learned codecs. The inclusion of user-generated content and gaming video as distinct categories invites research into content-adaptive coding tools and perceptual quality metrics tailored to these sources, as does the HDR coverage with its use of weighted PSNR alongside MS-SSIM. The explicit allowance for neural and learned components, with mandatory training data disclosure and source code requirements, signals that JVET anticipates hybrid and end-to-end learned codecs as serious contenders, making codec-agnostic adaptive streaming, QoE modeling for learned video codecs, and large-scale perceptual quality benchmarking timely topics for the ACM SIGMM community.

Energy-aware Streaming in MPEG-DASH

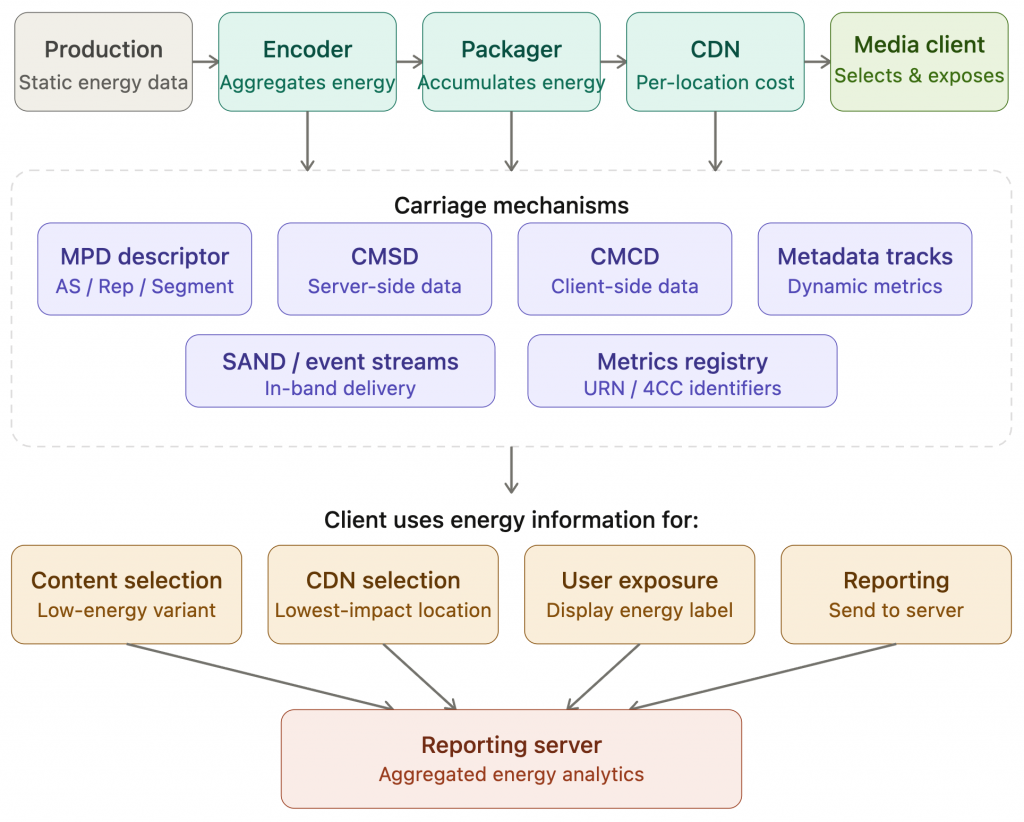
MPEG’s WG 3 (Systems/DASH) is developing a framework for integrating energy-related information into adaptive streaming workflows, currently documented as a Technology under Consideration (TuC) in the DASH specification. The proposed framework treats energy as a first-class design metric alongside QoE, latency, and throughput, and defines an end-to-end approach for assigning, aggregating, and propagating energy consumption data across the entire media delivery chain — from production and encoding through CDN distribution to the client. A key design principle is extensibility: rather than hardcoding specific metrics, the framework proposes a common registry of energy-related metrics (such as energy indices or carbon indices) identified via URNs or 4CC codes, inspired by existing registries like MP4RA and DASH-IF. Energy information may be carried through a variety of existing DASH mechanisms, including MPD descriptors at multiple granularity levels (Adaptation Set, Representation, Segment, Service Location), CMCD/CMSD extensions, metadata tracks, SAND messages, and event streams. A dedicated Energy descriptor in the MPD is proposed, analogous to existing Accessibility descriptors, to expose energy information to clients and applications for representation selection, user exposure, and reporting to back-end servers.

Concept of Energy-aware Streaming in MPEG-DASH.

The April 2026 update reported significant progress on two related fronts. A 5G-MAG workshop co-organized with 3GPP SA4 and Greening of Streaming (March 2026) highlighted growing industry consensus around practical energy measurement, surfacing findings such as the dominant role of device eco-mode settings and content brightness over codec or resolution choices in determining end-device energy consumption, and the challenge of reproducible cloud-based energy measurement. In parallel, 3GPP’s Rel-20 study on media energy consumption exposure (FS_Energy_Ph2_MED) reached 80% completion and is expected to conclude in June 2026, with normative work to follow. Notably, 3GPP’s current draft conclusions focus on generic architectural enablers, specifically a new Energy Information Application Function, while explicitly deferring media-layer and client-driven energy optimization to external bodies such as MPEG, SVTA, and DVB. This positions MPEG-DASH’s manifest-based energy signaling work as the natural venue for maturing the streaming-level mechanisms that 3GPP may later reference.

Research aspects: This work opens several timely directions. Energy-aware ABR algorithm design, i.e., jointly optimizing QoE and energy across representation selection, CDN choice, and client device settings, is a natural extension of the existing adaptive streaming research agenda. The proposed metrics registry and MPD-level signaling create opportunities for dataset construction and benchmarking, building on emerging open datasets such as COCONUT [Tashtarian2024] and VEED [Linder2024]. The finding that device-side factors (eco-mode, display brightness) dominate energy consumption over codec and bitrate choices challenges some common assumptions and calls for more holistic QoE-energy modeling. Finally, the cross-SDO coordination between MPEG, 3GPP, IETF (GREEN working group), and Greening of Streaming presents opportunities for the ACM SIGMM community to contribute to the design of interoperable, standardized energy reporting APIs for streaming services.

MPEG-AI: Vision and Scenarios for Artificial Intelligence in Multimedia

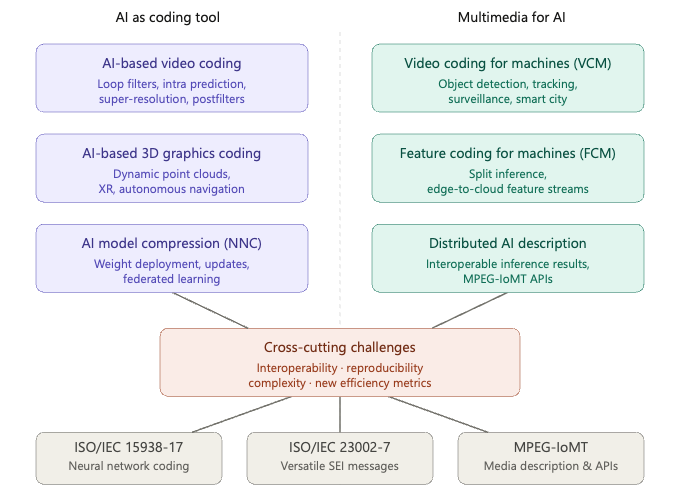
The first edition of ISO/IEC TR 23888-1 serves as the foundational vision document for the MPEG-AI series (ISO/IEC 23888). The document maps out how AI and neural network technologies interact with multimedia standardization along two complementary axes: (i) AI as a multimedia coding tool (e.g., AI-based video compression, 3D point cloud coding) and (ii) multimedia as input for AI consumption (e.g., video coding optimized for machine vision tasks). Under this umbrella, the document surveys six technical areas. In AI-based video coding, neural network components are explored as hybrid additions to VVC-style codecs, covering in-loop filters, intra prediction, super-resolution via reference picture resampling, and content-adaptive postfilters transmitted via SEI messages using the Neural Network Coding standard (NNC, ISO/IEC 15938-17). In AI-based 3D graphics coding, the focus is on dynamic point clouds for immersive (XR, gaming) and machine-oriented (autonomous navigation, BIM) applications, where sparsity and geometric irregularity pose unique challenges beyond those faced by image/video AI codecs. AI model compression (NNC) addresses the bandwidth-efficient deployment and incremental updating of neural network weights to devices, with use cases ranging from adaptive streaming ABR models to federated learning and postfilter delivery. Video coding for machines (VCM) targets compression optimized for downstream AI tasks such as object detection, tracking, and content moderation, with applications in surveillance, intelligent transportation, smart cities, and industrial inspection. Feature coding for machines (FCM) extends this to split-inference architectures where intermediate feature maps — rather than reconstructed video — are compressed and transmitted between edge devices and servers. Finally, distributed AI media description addresses the interoperable representation and API-level exchange of AI inference results (e.g., bounding boxes, segmentation masks) between networked media analyzers, as specified in the MPEG-IoMT suite.

ISO/IEC TR 23888-1: AI as a multimedia coding tool and multimedia as input for AI consumption.

Research aspects: The hybrid codec paradigm raises open questions around joint optimization of traditional and learned tools and complexity-aware training for mobile targets. The VCM and FCM tracks call for new task-oriented quality metrics capturing machine-task performance as a function of bitrate, an area where the multimedia and computer vision communities can collaborate. The split-inference and feature coding scenarios introduce latency-constrained compression problems for edge-to-cloud pipelines, which naturally connect to adaptive streaming and IoT research. Finally, the reproducibility and bit-exactness challenges highlighted in the document — hardware-dependent inference, non-deterministic training, and the absence of standardized evaluation environments — present an opportunity for the community to develop shared benchmarking infrastructure for learned multimedia codecs.

MPEG Roadmap

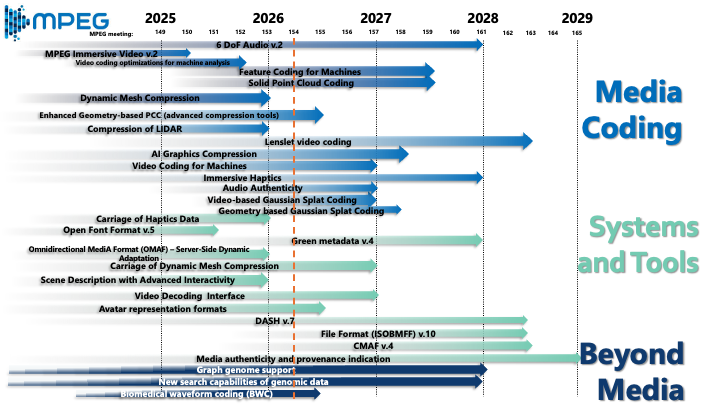
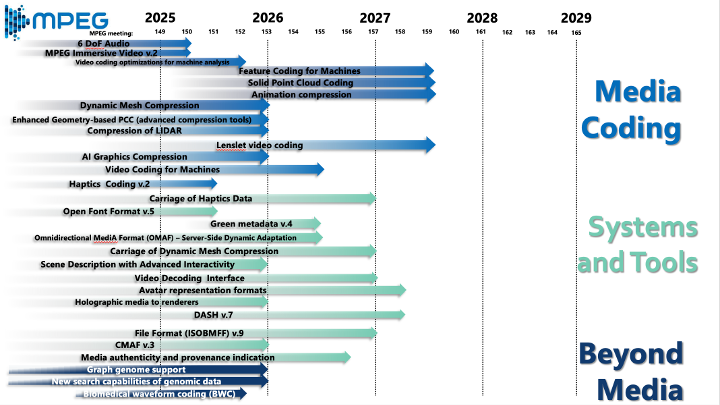
MPEG released an updated roadmap at its 154th meeting, reflecting the current status and near-term trajectory of its standardization activities across three broad pillars. Under Media Coding, work nearing completion includes MPEG Immersive Video v.2, Feature Coding for Machines, Solid Point Cloud Coding, and Dynamic Mesh Compression, while longer-horizon efforts cover AI Graphics Compression, Video Coding for Machines, Lenslet video coding, and — directly relevant to this report — both Video-based and Geometry-based Gaussian Splat Coding tracks. Under Systems and Tools, near-term deliverables include DASH v.7, Green metadata v.4, and Carriage of Haptics Data, with CMAF v.4 and File Format (ISOBMFF) v.10 on a slightly longer timeline. The Beyond Media pillar continues to advance genomic data search and biomedical waveform coding (BWC), alongside media authenticity and provenance indication — underscoring MPEG’s expanding scope well beyond traditional audiovisual applications.

MPEG Roadmap as of April 2026.

Research aspects: The roadmap highlights several intersecting research opportunities. The convergence of volumetric and neural representations (i.e., point clouds, dynamic meshes, Gaussian splats, and lenslet video; all progressing in parallel) raises open questions around unified rate-distortion frameworks and cross-format QoE evaluation for 6DoF experiences. The simultaneous progression of Video Coding for Machines and Feature Coding for Machines alongside traditional human-centric codecs calls for research into adaptive pipelines that can serve both human and machine consumers from a shared bitstream. The Green metadata track connects directly to the energy-aware streaming work discussed above, underscoring the need for end-to-end energy modeling that spans codec choice, packaging, delivery, and consumption. Finally, the Beyond Media thread (e.g., particularly genomic data and biomedical waveforms) signals an expanding definition of “multimedia” that the ACM SIGMM community may wish to engage with as compression, retrieval, and QoE methods developed for audiovisual content find applicability in life sciences.

Concluding Remarks

The 154th MPEG meeting in Santa Eularia reflects a standards body in active transition, broadening its scope from traditional audiovisual compression toward a richer landscape that encompasses neural scene representations, AI-native codecs, energy-aware delivery, and even biomedical data. The Gaussian Splat Coding exploration, the next-generation video compression Call for Proposals, the MPEG-AI vision document, and the energy-aware streaming framework each address distinct but interconnected challenges: how to represent, compress, deliver, and consume increasingly complex and diverse media efficiently and sustainably. For the ACM SIGMM community, this meeting offers both a map of where industry standardization is heading and a set of open research problems (i.e., spanning perceptual quality assessment, learned compression, edge inference, green streaming, and immersive media delivery) where academic contributions can meaningfully shape the next generation of multimedia standards.

The 155th MPEG meeting will be held in Geneva, Switzerland, from July 13 to 17, 2026. Click here for more information about MPEG meetings and ongoing developments.

References

  • [Kerbl, 2023] Bernhard Kerbl, Georgios Kopanas, Thomas Leimkuehler, and George Drettakis. 2023. 3D Gaussian Splatting for Real-Time Radiance Field Rendering. ACM Trans. Graph. 42, 4, Article 139 (August 2023), 14 pages. https://doi.org/10.1145/3592433
  • [Tashtarian, 2024] Farzad Tashtarian, Daniele Lorenzi, Hadi Amirpour, Samira Afzal, and Christian Timmerer. 2024. COCONUT: Content Consumption Energy Measurement Dataset for Adaptive Video Streaming. In Proceedings of the 15th ACM Multimedia Systems Conference (MMSys ’24). Association for Computing Machinery, New York, NY, USA, 346–352. https://doi.org/10.1145/3625468.3652179
  • [Linder, 2024] Sandro Linder, Samira Afzal, Christian Bauer, Hadi Amirpour, Radu Prodan, and Christian Timmerer. 2024. VEED: Video Encoding Energy and CO2 Emissions Dataset for AWS EC2 instances. In Proceedings of the 15th ACM Multimedia Systems Conference (MMSys ’24). Association for Computing Machinery, New York, NY, USA, 332–338. https://doi.org/10.1145/3625468.3652178

MPEG Column: 153rd MPEG Meeting

The 153rd MPEG meeting took place online from January 19-23, 2026. The official MPEG press release can be found here. This report highlights key outcomes from the meeting, with a focus on research directions relevant to the ACM SIGMM community:

  • MPEG Roadmap
  • Exploration on MPEG Gaussian Splat Coding (GSC)
  • MPEG Immersive Video 2nd edition (new white paper)

MPEG Roadmap

MPEG released an updated roadmap showing continued convergence of immersive and “beyond video” media with deployment-ready systems work. Near-term priorities include 6DoF experiences (MPEG Immersive Video v2 and 6DoF audio), volumetric representations (dynamic meshes, solid point clouds, LiDAR, and emerging Gaussian splat coding), and “coding for machines,” which treats visual and audio signals as inputs to downstream analytics rather than only for human consumption.

Research aspects: The most promising research opportunities sit at the intersections: renderer and device-aware rate-distortion-complexity optimization for volumetric content; adaptive streaming and packaging evolution (e.g., MPEG-DASH / CMAF) for interactive 6DoF services under tight latency constraints; and cross-cutting themes such as media authenticity and provenance, green and energy metadata, and exploration threads on neural-network-based compression and compression of neural networks that foreshadow AI-native multimedia pipelines.

MPEG Gaussian Splat Coding (GSC)

Gaussian Splat Coding (GSC) is MPEG’s effort to standardize how 3D Gaussian Splatting content, scenes represented as sparse “Gaussian splats” with geometry plus rich attributes (scale and rotation, opacity, and spherical-harmonics appearance for view-dependent rendering), is encoded, decoded, and evaluated so it can be exchanged and rendered consistently across platforms. The main motivation is interoperability for immersive media pipelines: enabling reproducible results, shared benchmarks, and comparable rate-distortion-complexity trade-offs for use cases spanning telepresence and immersive replay to mobile XR and digital twins, while retaining the visual strengths that made 3DGS attractive compared to heavier neural scene representations.

The work remains in an exploration phase, coordinated across ISO/IEC JTC 1/SC 29 groups WG 4 (MPEG Video Coding) and WG 7 (MPEG Coding for 3D Graphics and Haptics) through Joint Exploration Experiments covering datasets and anchors, new coding tools, software (renderer and metrics), and Common Test Conditions (CTC). A notable systems thread is “lightweight GSC” for resource-constrained devices (single-frame, low-latency tracks using geometry-based and video-based pipelines with explicit time and memory targets), alongside an “early deployment” path via amendments to existing MPEG point-cloud codecs to more natively carry Gaussian-splat parameters. In parallel, MPEG is testing whether splat-specific tools can outperform straightforward mappings in quality, bitrate, and compute for real-time and streaming-centric scenarios.

Research aspects: Relevant SIGMM directions include splat-aware compression tools and rate-distortion-complexity optimization (including tracked vs. non-tracked temporal prediction); QoE evaluation for 6DoF navigation (metrics for view and temporal consistency and splat-specific artifacts); decoder and renderer co-design for real-time and mobile lightweight profiles (progressive and LOD-friendly layouts, GPU-friendly decode); and networked delivery problems such as adaptive streaming, ROI and view-dependent transmission, and loss resilience for splat parameters. Additional opportunities include interoperability work on reproducible benchmarking, conformance testing, and practical packaging and signaling for deployment.

MPEG Immersive Video 2nd edition (white paper)

The second edition of MPEG Immersive Video defines an interoperable bitstream and decoding process for efficient 6DoF immersive scene playback, supporting translational and rotational movement with motion parallax to reduce discomfort often associated with pure 3DoF viewing. The second edition primarily extends functionality (without changing the high-level bitstream structure), adding capabilities such as capture-device information, additional projection types, and support for Simple Multi-Plane Image (MPI), alongside tools that better support geometry and attribute handling and depth-related processing.

Architecturally, MIV ingests multiple (unordered) camera views with geometry (depth and occupancy) and attributes (e.g., texture), then reduces inter-view redundancy by extracting patches and packing them into 2D “atlases” that are compressed using conventional video codecs. MIV-specific metadata signals how to reconstruct views from the atlases. The standard is built as an extension of the common Visual Volumetric Video-based Coding (V3C) bitstream framework shared with V-PCC, with profiles that preserve backward compatibility while introducing a new profile for added second-edition functionality and a tailored profile for full-plane MPI delivery.

Research aspects: Key SIGMM topics include systems-efficient 6DoF delivery (better view and patch selection and atlas packing under latency and bandwidth constraints); rate-distortion-complexity-QoE optimization that accounts for decode and render cost (especially on HMD and mobile) and motion-parallax comfort; adaptive delivery strategies (representation ladders, viewport and pose-driven bit allocation, robust packetization and error resilience for atlas video plus metadata); renderer-aware metrics and subjective protocols for multi-view temporal consistency; and deployment-oriented work such as profile and level tuning, codec-group choices (HEVC / VVC), conformance testing, and exploiting second-edition features (capture device info, depth tools, Simple MPI) for more reliable reconstruction and improved user experience.

Concluding Remarks

The meeting outcomes highlight a clear shift toward immersive and AI-enabled media systems where compression, rendering, delivery, and evaluation must be co-designed. These developments offer timely opportunities for the ACM SIGMM community to contribute reproducible benchmarks, perceptual metrics, and end-to-end streaming and systems research that can directly influence emerging standards and deployments.

The 154th MPEG meeting will be held in Santa Eulària, Spain, from April 27 to May 1, 2026. Click here for more information about MPEG meetings and ongoing developments.

MPEG Column: 152nd MPEG Meeting

The 152nd MPEG meeting took place in Geneva, Switzerland, from October 7 to October 11, 2025. The official MPEG press release can be found here. This column highlights key points from the meeting, amended with research aspects relevant to the ACM SIGMM community:

  • MPEG Systems received an Emmy® Award for the Common Media Application Format (CMAF). A separate press release regarding this achievement is available here.
  • JVET ratified new editions of VSEI, VVC, and HEVC
  • The fourth edition of Visual Volumetric Video-based Coding (V3C and V-PCC) has been finalized
  • Responses to the call for evidence on video compression with capability beyond VVC successfully evaluated

MPEG Systems received an Emmy® Award for the Common Media Application Format (CMAF)

On September 18, 2025, the National Academy of Television Arts & Sciences (NATAS) announced that the MPEG Systems Working Group (ISO/IEC JTC 1/SC 29/WG 3) had been selected as a recipient of a Technology & Engineering Emmy® Award for standardizing the Common Media Application Format (CMAF). But what is CMAF? CMAF (ISO/IEC 23000-19) is a media format standard designed to simplify and unify video streaming workflows across different delivery protocols and devices. Here’s a structured overview. Before CMAF, streaming services often had to produce multiple container formats, i.e., (i) ISO Base Media File Format (ISOBMFF) for MPEG-DASH and MPEG-2 Transport Stream (TS) for Apple HLS. This duplication resulted in additional encoding, packaging, and storage costs. I wrote a blog post about this some time ago here. CMAF’s main goal is to define a single, standardized segmented media format usable by both HLS and DASH, enabling “encode once, package once, deliver everywhere.”

The core concept of CMAF is that it is based on ISOBMFF, the foundation for MP4. Each CMAF stream consists of a CMAF header, CMAF media segments, and CMAF track files (a logical sequence of segments for one stream, e.g., video or audio). CMAF enables low-latency streaming by allowing progressive segment transfer, adopting chunked transfer encoding via CMAF chunks. CMAF defines interoperable profiles for codecs and presentation types for video, audio, and subtitles. Thanks to its compatibility with and adoption within existing streaming standards, CMAF bridges the gaps between DASH and HLS, creating a unified ecosystem.

Research aspects include – but are not limited to – low-latency tuning (segment/chunk size trade-offs, HTTP/3, QUIC), Quality of Experience (QoE) impact of chunk-based adaptation, synchronization of live and interactive CMAF streams, edge-assisted CMAF caching and prediction, and interoperability testing and compliance tools.

JVET ratified new editions of VSEI, VVC, and HEVC

At its 40th meeting, the Joint Video Experts Team (JVET, ISO/IEC JTC 1/SC 29/WG 5) concluded the standardization work on the next editions of three key video coding standards, advancing them to the Final Draft International Standard (FDIS) stage. Corresponding twin-text versions have also been submitted to ITU-T for consent procedures. The finalized standards include:

  • Versatile Supplemental Enhancement Information (VSEI) — ISO/IEC 23002-7 | ITU-T Rec. H.274
  • Versatile Video Coding (VVC) — ISO/IEC 23090-3 | ITU-T Rec. H.266
  • High Efficiency Video Coding (HEVC) — ISO/IEC 23008-2 | ITU-T Rec. H.265

The primary focus of these new editions is the extension and refinement of Supplemental Enhancement Information (SEI) messages, which provide metadata and auxiliary data to support advanced processing, interpretation, and quality management of coded video streams.

The updated VSEI specification introduces both new and refined SEI message types supporting advanced use cases:

  • AI-driven processing: Extensions for neural-network-based post-filtering and film grain synthesis offer standardized signalling for machine learning components in decoding and rendering pipelines.
  • Semantic and multimodal content: New SEI messages describe infrared, X-ray, and other modality indicators, region packing, and object mask encoding; creating interoperability points for multimodal fusion and object-aware compression research.
  • Pipeline optimization: Messages defining processing order and post-processing nesting support research on joint encoder-decoder optimization and edge-cloud coordination in streaming architectures.
  • Authenticity and generative media: A new set of messages supports digital signature embedding and generative-AI-based face encoding, raising questions for the SIGMM community about trust, authenticity, and ethical AI in media pipelines.
  • Metadata and interpretability: New SEIs for text description, image format metadata, and AI usage restriction requests could facilitate research into explainable media, human-AI interaction, and regulatory compliance in multimedia systems.

All VSEI features are fully compatible with the new VVC edition, and most are also supported in HEVC. The new HEVC edition further refines its multi-view profiles, enabling more robust 3D and immersive video use cases.

Research aspects of these new standard’s editions can be summarized as follows: (i) Define new standardized interfaces between neural post-processing and conventional video coding, fostering reproducible and interoperable research on learned enhancement models. (ii) Encourage exploration of metadata-driven adaptation and QoE optimization using SEI-based signals in streaming systems. (iii) Open possibilities for cross-layer system research, connecting compression, transport, and AI-based decision layers. (iv) Introduce a formal foundation for authenticity verification, content provenance, and AI-generated media signalling, relevant to current debates on trustworthy multimedia.

These updates highlight how ongoing MPEG/ITU standardization is evolving toward a more AI-aware, multimodal, and semantically rich media ecosystem, providing fertile ground for experimental and applied research in multimedia systems, coding, and intelligent media delivery.

The fourth edition of Visual Volumetric Video-based Coding (V3C and V-PCC) has been finalized

MPEG Coding of 3D Graphics and Haptics (ISO/IEC JTC 1/SC 29/WG7) has advanced MPEG-I Part 5 – Visual Volumetric Video-based Coding (V3C and V-PCC) to the Final Draft International Standard (FDIS) stage, marking its fourth edition. This revision introduces major updates to the Video-based Coding of Volumetric Content (V3C) framework, particularly enabling support for an additional bitstream instance: V-DMC (Video-based Dynamic Mesh Compression).

Previously, V3C served as the structural foundation for V-PCC (Video-based Point Cloud Compression) and MIV (MPEG Immersive Video). The new edition extends this flexibility by allowing V-DMC integration, reinforcing V3C as a generic, extensible framework for volumetric and 3D video coding. All instances follow a shared principle, i.e., using conventional 2D video codecs (e.g., HEVC, VVC) for projection-based compression, complemented by specialized tools for mapping, geometry, and metadata handling.

While V-PCC remains co-specified within Part 5, MIV (Part 12) and V-DMC (Part 29) are standardized separately. The progression to FDIS confirms the technical maturity and architectural stability of the framework.

This evolution opens new research directions as follows: (i) Unified 3D content representation, enabling comparative evaluation of point cloud, mesh, and view-based methods under one coding architecture. (ii) Efficient use of 2D codecs for 3D media, raising questions on mapping optimization, distortion modeling, and geometry-texture compression. (iii) Dynamic and interactive volumetric streaming, relevant to AR/VR, telepresence, and immersive communication research.

The fourth edition of MPEG-I Part 5 thus positions V3C as a cornerstone for future volumetric, AI-assisted, and immersive video systems, bridging standardization and cutting-edge multimedia research.

Responses to the call for evidence on video compression with capability beyond VVC successfully evaluated

The Joint Video Experts Team (JVET, ISO/IEC JTC 1/SC 29/WG 5) has completed the evaluation of submissions to its Call for Evidence (CfE) on video compression with capability beyond VVC. The CfE investigated coding technologies that may surpass the performance of the current Versatile Video Coding (VVC) standard in compression efficiency, computational complexity, and extended functionality.

A total of five submissions were assessed, complemented by ECM16 reference encodings and VTM anchor sequences with multiple runtime variants. The evaluation addressed both compression capability and encoding runtime, as well as low-latency and error-resilience features. All technologies were derived from VTM, ECM, or NNVC frameworks, featuring modified encoder configurations and coding tools rather than entirely new architectures.

Key Findings

  • In the compression capability test, 76 out of 120 test cases showed at least one submission with a non-overlapping confidence interval compared to the VTM anchor. Several methods outperformed ECM16 in visual quality and achieved notable compression gains at lower complexity. Neural-network-based approaches demonstrated clear perceptual improvements, particularly for 8K HDR content, while gains were smaller for gaming scenarios.
  • In the encoding runtime test, significant improvements were observed even under strict complexity constraints: 37 of 60 test points (at both 1× and 0.2× runtime) showed statistically significant benefits over VTM. Some submissions achieved faster encoding than VTM, with only a 35% increase in decoder runtime.

Research Relevance and Outlook

The CfE results illustrate a maturing convergence between model-based and data-driven video coding, raising research questions highly relevant for the ACM SIGMM community:

  • How can learned prediction and filtering networks be integrated into standard codecs while preserving interoperability and runtime control?
  • What methodologies can best evaluate perceptual quality beyond PSNR, especially for HDR and immersive content?
  • How can complexity-quality trade-offs be optimized for diverse hardware and latency requirements?

Building on these outcomes, JVET is preparing a Call for Proposals (CfP) for the next-generation video coding standard, with a draft planned for early 2026 and evaluation through 2027. Upcoming activities include refining test material, adding Reference Picture Resampling (RPR), and forming a new ad hoc group on hardware implementation complexity.

For multimedia researchers, this CfE marks a pivotal step toward AI-assisted, complexity-adaptive, and perceptually optimized compression systems, which are considered a key frontier where codec standardization meets intelligent multimedia research.

The 153rd MPEG meeting will be held online from January 19 to January 23, 2026. Click here for more information about MPEG meetings and their developments.

MPEG Column: 150th MPEG Meeting (Virtual/Online)

The 150th MPEG meeting was held online from 31 March to 04 April 2025. The official press release can be found here. This column provides the following highlights:

  • Requirements: MPEG-AI strategy and white paper on MPEG technologies for metaverse
  • JVET: Draft Joint Call for Evidence on video compression with capability beyond Versatile Video Coding (VVC)
  • Video: Gaussian splat coding and video coding for machines
  • Audio: Audio coding for machines
  • 3DGH: 3D Gaussian splat coding

MPEG-AI Strategy

The MPEG-AI strategy envisions a future where AI and neural networks are deeply integrated into multimedia coding and processing, enabling transformative improvements in how digital content is created, compressed, analyzed, and delivered. By positioning AI at the core of multimedia systems, MPEG-AI seeks to enhance both content representation and intelligent analysis. This approach supports applications ranging from adaptive streaming and immersive media to machine-centric use cases like autonomous vehicles and smart cities. AI is employed to optimize coding efficiency, generate intelligent descriptors, and facilitate seamless interaction between content and AI systems. The strategy builds on foundational standards such as ISO/IEC 15938-13 (CDVS), 15938-15 (CDVA), and 15938-17 (Neural Network Coding), which collectively laid the groundwork for integrating AI into multimedia frameworks.

Currently, MPEG is developing a family of standards under the ISO/IEC 23888 series that includes a vision document, machine-oriented video coding, and encoder optimization for AI analysis. Future work focuses on feature coding for machines and AI-based point cloud compression to support high-efficiency 3D and visual data handling. These efforts reflect a paradigm shift from human-centric media consumption to systems that also serve intelligent machine agents. MPEG-AI maintains compatibility with traditional media processing while enabling scalable, secure, and privacy-conscious AI deployments. Through this initiative, MPEG aims to define the future of multimedia as an intelligent, adaptable ecosystem capable of supporting complex, real-time, and immersive digital experiences.

MPEG White Paper on Metaverse Technologies

The MPEG white paper on metaverse technologies (cf. MPEG white papers) outlines the pivotal role of MPEG standards in enabling immersive, interoperable, and high-quality virtual experiences that define the emerging metaverse. It identifies core metaverse parameters – real-time operation, 3D experience, interactivity, persistence, and social engagement – and maps them to MPEG’s longstanding and evolving technical contributions. From early efforts like MPEG-4’s Binary Format for Scenes (BIFS) and Animation Framework eXtension (AFX) to MPEG-V’s sensory integration, and the advanced MPEG-I suite, these standards underpin critical features such as scene representation, dynamic 3D asset compression, immersive audio, avatar animation, and real-time streaming. Key technologies like point cloud compression (V-PCC, G-PCC), immersive video (MIV), and dynamic mesh coding (V-DMC) demonstrate MPEG’s capacity to support realistic, responsive, and adaptive virtual environments. Recent efforts include neural network compression for learned scene representations (e.g., NeRFs), haptic coding formats, and scene description enhancements, all geared toward richer user engagement and broader device interoperability.

The document highlights five major metaverse use cases – virtual environments, immersive entertainment, virtual commerce, remote collaboration, and digital twins – all supported by MPEG innovations. It emphasizes the foundational role of MPEG-I standards (e.g., Parts 12, 14, 29, 39) for synchronizing immersive content, representing avatars, and orchestrating complex 3D scenes across platforms. Future challenges identified include ensuring interoperability across systems, advancing compression methods for AI-assisted scenarios, and embedding security and privacy protections. With decades of multimedia expertise and a future-focused standards roadmap, MPEG positions itself as a key enabler of the metaverse – ensuring that emerging virtual ecosystems are scalable, immersive, and universally accessible​.

The MPEG white paper on metaverse technologies highlights several research opportunities, including efficient compression of dynamic 3D content (e.g., point clouds, meshes, neural representations), synchronization of immersive audio and haptics, real-time adaptive streaming, and scene orchestration. It also points to challenges in standardizing interoperable avatar formats, AI-enhanced media representation, and ensuring seamless user experiences across devices. Additional research directions include neural network compression, cross-platform media rendering, and developing perceptual metrics for immersive Quality of Experience (QoE).

Draft Joint Call for Evidence (CfE) on Video Compression beyond Versatile Video Coding (VVC)

The latest JVET AHG report on ECM software development (AHG6), documented as JVET-AL0006, shows promising results. Specifically, in the “Overall” row and “Y” column, there is a 27.06% improvement in coding efficiency compared to VVC, as shown in the figure below.

The Draft Joint Call for Evidence (CfE) on video compression beyond VVC (Versatile Video Coding), identified as document JVET-AL2026 | N 355, is being developed to explore new advancements in video compression. The CfE seeks evidence in three main areas: (a) improved compression efficiency and associated trade-offs, (b) encoding under runtime constraints, and (c) enhanced performance in additional functionalities. This initiative aims to evaluate whether new techniques can significantly outperform the current state-of-the-art VVC standard in both compression and practical deployment aspects.

The visual testing will be carried out across seven categories, including various combinations of resolution, dynamic range, and use cases: SDR Random Access UHD/4K, SDR Random Access HD, SDR Low Bitrate HD, HDR Random Access 4K, HDR Random Access Cropped 8K, Gaming Low Bitrate HD, and UGC (User-Generated Content) Random Access HD. Sequences and rate points for testing have already been defined and agreed upon. For a fair comparison, rate-matched anchors using VTM (VVC Test Model) and ECM (Enhanced Compression Model) will be generated, with new configurations to enable reduced run-time evaluations. A dry-run of the visual tests is planned during the upcoming Daejeon meeting, with ECM and VTM as reference anchors, and the CfE welcomes additional submissions. Following this dry-run, the final Call for Evidence is expected to be issued in July, with responses due in October.

The Draft Joint Call for Evidence (CfE) on video compression beyond VVC invites research into next-generation video coding techniques that offer improved compression efficiency, reduced encoding complexity under runtime constraints, and enhanced functionalities such as scalability or perceptual quality. Key research aspects include optimizing the trade-off between bitrate and visual fidelity, developing fast encoding methods suitable for constrained devices, and advancing performance in emerging use cases like HDR, 8K, gaming, and user-generated content.

3D Gaussian Splat Coding

Gaussian splatting is a real-time radiance field rendering method that represents a scene using 3D Gaussians. Each Gaussian has parameters like position, scale, color, opacity, and orientation, and together they approximate how light interacts with surfaces in a scene. Instead of ray marching (as in NeRF), it renders images by splatting the Gaussians onto a 2D image plane and blending them using a rasterization pipeline, which is GPU-friendly and much faster. Developed by Kerbl et al. (2023) it is capable of real-time rendering (60+ fps) and outperforms previous NeRF-based methods in speed and visual quality. Gaussian splat coding refers to the compression and streaming of 3D Gaussian representations for efficient storage and transmission. It’s an active research area and under standardization consideration in MPEG.

MPEG technical requirements working group together with MPEG video working group started an exploration on Gaussian splat coding and the MPEG coding of 3D graphics and haptics (3DGH) working group addresses 3D Gaussian splat coding, respectively. Draft Gaussian splat coding use cases and requirements are available and various joint exploration experiments (JEEs) are conducted between meetings.

(3D) Gaussian splat coding is actively researched in academia, also in the context of streaming, e.g., like in “LapisGS: Layered Progressive 3D Gaussian Splatting for Adaptive Streaming” or “LTS: A DASH Streaming System for Dynamic Multi-Layer 3D Gaussian Splatting Scenes”. The research aspects of 3D Gaussian splat coding and streaming span a wide range of areas across computer graphics, compression, machine learning, and systems for real-time immersive media. In particular, on efficiently representing and transmitting Gaussian-based neural scene representations for real-time rendering. Key areas include compression of Gaussian parameters (position, scale, color, opacity), perceptual and geometry-aware optimizations, and neural compression techniques such as learned latent coding. Streaming challenges involve adaptive, view-dependent delivery, level-of-detail management, and low-latency rendering on edge or mobile devices. Additional research directions include standardizing file formats, integrating with scene graphs, and ensuring interoperability with existing 3D and immersive media frameworks.

MPEG Audio and Video Coding for Machines

The Call for Proposals on Audio Coding for Machines (ACoM), issued by the MPEG audio coding working group, aims to develop a standard for efficiently compressing audio, multi-dimensional signals (e.g., medical data), or extracted features for use in machine-driven applications. The standard targets use cases such as connected vehicles, audio surveillance, diagnostics, health monitoring, and smart cities, where vast data streams must be transmitted, stored, and processed with low latency and high fidelity. The ACoM system is designed in two phases: the first focusing on near-lossless compression of audio and metadata to facilitate training of machine learning models, and the second expanding to lossy compression of features optimized for specific applications. The goal is to support hybrid consumption – by machines and, where needed, humans – while ensuring interoperability, low delay, and efficient use of storage and bandwidth.

The CfP outlines technical requirements, submission guidelines, and evaluation metrics. Participants must provide decoders compatible with Linux/x86 systems, demonstrate performance through objective metrics like compression ratio, encoder/decoder runtime, and memory usage, and undergo a mandatory cross-checking process. Selected proposals will contribute to a reference model and working draft of the standard. Proponents must register by August 1, 2025, with submissions due in September, and evaluation taking place in October. The selection process emphasizes lossless reproduction, metadata fidelity, and significant improvements over a baseline codec, with a path to merge top-performing technologies into a unified solution for standardization.

Research aspects of Audio Coding for Machines (ACoM) include developing efficient compression techniques for audio and multi-dimensional data that preserve key features for machine learning tasks, optimizing encoding for low-latency and resource-constrained environments, and designing hybrid formats suitable for both machine and human consumption. Additional research areas involve creating interoperable feature representations, enhancing metadata handling for context-aware processing, evaluating trade-offs between lossless and lossy compression, and integrating machine-optimized codecs into real-world applications like surveillance, diagnostics, and smart systems.

The MPEG video coding working group approved the committee draft (CD) for ISO/IEC 23888-2 video coding for machines (VCM). VCM aims to encode visual content in a way that maximizes machine task performance, such as computer vision, scene understanding, autonomous driving, smart surveillance, robotics and IoT. Instead of preserving photorealistic quality, VCM seeks to retain features and structures important for machines, possibly at much lower bitrates than traditional video codecs. The CD introduces several new tools and enhancements aimed at improving machine-centric video processing efficiency. These include updates to spatial resampling, such as the signaling of the inner decoded picture size to better support scalable inference. For temporal resampling, the CD enables adaptive resampling ratios and introduces pre- and post-filters within the temporal resampler to maintain task-relevant temporal features. In the filtering domain, it adopts bit depth truncation techniques – integrating bit depth shifting, luma enhancement, and chroma reconstruction – to optimize both signaling efficiency and cross-platform interoperability. Luma enhancement is further refined through an integer-based implementation for luma distribution parameters, while chroma reconstruction is stabilized across different hardware platforms. Additionally, the CD proposes removing the neural network-based in-loop filter (NNLF) to simplify the pipeline. Finally, in terms of bitstream structure, it adopts a flattened structure with new signaling methods to support efficient random access and better coordination with system layers, aligning with the low-latency, high-accuracy needs of machine-driven applications.

Research in VCM focuses on optimizing video representation for downstream machine tasks, exploring task-driven compression techniques that prioritize inference accuracy over perceptual quality. Key areas include joint video and feature coding, adaptive resampling methods tailored to machine perception, learning-based filter design, and bitstream structuring for efficient decoding and random access. Other important directions involve balancing bitrate and task accuracy, enhancing robustness across platforms, and integrating machine-in-the-loop optimization to co-design codecs with AI inference pipelines.

Concluding Remarks

The 150th MPEG meeting marks significant progress across AI-enhanced media, immersive technologies, and machine-oriented coding. With ongoing work on MPEG-AI, metaverse standards, next-gen video compression, Gaussian splat representation, and machine-friendly audio and video coding, MPEG continues to shape the future of interoperable, intelligent, and adaptive multimedia systems. The research opportunities and standardization efforts outlined in this meeting provide a strong foundation for innovations that support real-time, efficient, and cross-platform media experiences for both human and machine consumption.

The 151st MPEG meeting will be held in Daejeon, Korea, from 30 June to 04 July 2025. Click here for more information about MPEG meetings and their developments.

MPEG Column: 149th MPEG Meeting in Geneva, Switzerland

The 149th MPEG meeting took place in Geneva, Switzerland, from January 20 to 24, 2025. The official press release can be found here. MPEG promoted three standards (among others) to Final Draft International Standard (FDIS), driving innovation in next-generation, immersive audio and video coding, and adaptive streaming:

  • MPEG-I Immersive Audio enables realistic 3D audio with six degrees of freedom (6DoF).
  • MPEG Immersive Video (Second Edition) introduces advanced coding tools for volumetric video.
  • MPEG-DASH (Sixth Edition) enhances low-latency streaming, content steering, and interactive media.

This column focuses on these new standards/editions based on the press release and amended with research aspect relevant for the ACM SIGMM community.

MPEG-I Immersive Audio

At the 149th MPEG meeting, MPEG Audio Coding (WG 6) promoted ISO/IEC 23090-4 MPEG-I immersive audio to Final Draft International Standard (FDIS), marking a major milestone in the development of next-generation audio technology.

MPEG-I immersive audio is a groundbreaking standard designed for the compact and highly realistic representation of spatial sound. Tailored for Metaverse applications, including Virtual, Augmented, and Mixed Reality (VR/AR/MR), it enables seamless real-time rendering of interactive 3D audio with six degrees of freedom (6DoF). Users can not only turn their heads in any direction (pitch/yaw/roll) but also move freely through virtual environments (x/y/z), creating an unparalleled sense of immersion.

True to MPEG’s legacy, this standard is optimized for efficient distribution – even over networks with severe bitrate constraints. Unlike proprietary VR/AR audio solutions, MPEG-I Immersive Audio ensures broad interoperability, long-term stability, and suitability for both streaming and downloadable content. It also natively integrates MPEG-H 3D Audio for high-quality compression.

The standard models a wide range of real-world acoustic effects to enhance realism. It captures detailed sound source properties (e.g., level, point sources, extended sources, directivity characteristics, and Doppler effects) as well as complex environmental interactions (e.g., reflections, reverberation, diffraction, and both total and partial occlusion). Additionally, it supports diverse acoustic environments, including outdoor spaces, multiroom scenes with connecting portals, and areas with dynamic openings such as doors and windows. Its rendering engine balances computational efficiency with high-quality output, making it suitable for a variety of applications.

Further reinforcing its impact, the upcoming ISO/IEC 23090-34 Immersive audio reference software will fully implement MPEG-I immersive audio in a real-time framework. This interactive 6DoF experience will facilitate industry adoption and accelerate innovation in immersive audio. The reference software is expected to reach FDIS status by April 2025.

With MPEG-I immersive audio, MPEG continues to set the standard for the future of interactive and spatial audio, paving the way for more immersive digital experiences.

Research aspects: Research can focus on optimizing the streaming and compression of MPEG-I immersive audio for constrained networks, ensuring efficient delivery without compromising spatial accuracy. Another key area is improving real-time 6DoF audio rendering by balancing computational efficiency and perceptual realism, particularly in modeling complex acoustic effects like occlusions, reflections, and Doppler shifts for interactive VR/AR/MR applications.

MPEG Immersive Video (Second Edition)

At the 149th MPEG meeting, MPEG Video Coding (WG 4) advanced the second edition of ISO/IEC 23090-12 MPEG immersive video (MIV) to Final Draft International Standard (FDIS), marking a significant step forward in immersive video technology.

MIV enables the efficient compression, storage, and distribution of immersive video content, where multiple real or virtual cameras capture a 3D scene. Designed for next-generation applications, the standard supports playback with six degrees of freedom (6DoF), allowing users to not only change their viewing orientation (pitch/yaw/roll) but also move freely within the scene (x/y/z). By leveraging strong hardware support for widely used video formats, MPEG immersive video provides a highly flexible framework for multi-view video plus depth (MVD) and multi-plane image (MPI) video coding, making volumetric video more accessible and efficient.

With the second edition, MPEG continues to expand the capabilities of MPEG immersive video, introducing a range of new technologies to enhance coding efficiency and support more advanced immersive experiences. Key additions include:

  • Geometry coding using luma and chroma planes, improving depth representation
  • Capture device information, enabling better reconstruction of the original scene
  • Patch margins and background views, optimizing scene composition
  • Static background atlases, reducing redundant data for stationary elements
  • Support for decoder-side depth estimation, enhancing depth accuracy
  • Chroma dynamic range modification, improving color fidelity
  • Piecewise linear normalized disparity quantization and linear depth quantization, refining depth precision

The second edition also introduces two new profiles: (1) MIV Simple MPI profile, allowing MPI content playback with a single 2D video decoder, and (2) MIV 2 profile, a superset of existing profiles that incorporates all newly added tools.

With these advancements, MPEG immersive video continues to push the boundaries of immersive media, providing a robust and efficient solution for next-generation video applications.

Research aspects: Possible research may explore advancements in MPEG immersive video to improve compression efficiency and real-time streaming while preserving depth accuracy and spatial quality. Another key area is enhancing 6DoF video rendering by leveraging new coding tools like decoder-side depth estimation and geometry coding, enabling more precise scene reconstruction and seamless user interaction in volumetric video applications.

MPEG-DASH (Sixth Edition)

At the 149th MPEG meeting, MPEG Systems (WG 3) advanced the sixth edition of MPEG-DASH (ISO/IEC 23009-1 Media presentation description and segment formats) by promoting it to the Final Draft International Standard (FDIS), the final stage of standards development. This milestone underscores MPEG’s ongoing commitment to innovation and responsiveness to evolving market needs.

The sixth edition introduces several key enhancements to improve the flexibility and efficiency of MPEG-DASH:

  • Alternative media presentation support, enabling seamless switching between main and alternative streams
  • Content steering signaling across multiple CDNs, optimizing content delivery
  • Enhanced segment sequence addressing, improving low-latency streaming and faster tune-in
  • Compact duration signaling using patterns, reducing MPD overhead
  • Support for Common Media Client Data (CMCD), enabling better client-side analytics
  • Nonlinear playback for interactive storylines, expanding support for next-generation media experiences

With these advancements, MPEG-DASH continues to evolve as a robust and scalable solution for adaptive streaming, ensuring greater efficiency, flexibility, and enhanced user experiences across a wide range of applications.

Research aspects: While advancing MPEG-DASH for more efficient and flexible adaptive streaming has been subject to research for a while, optimizing content delivery across multiple CDNs while minimizing latency and optimizing QoE remains an open issue. Another key area is enhancing interactivity and user experiences by leveraging new features like nonlinear playback for interactive storylines and improved client-side analytics through Common Media Client Data (CMCD).

The 150th MPEG meeting will be held online from March 31 to April 04, 2025. Click here for more information about MPEG meetings and their developments.

MPEG Column: 148th MPEG Meeting in Kemer, Türkiye

The 148th MPEG meeting took place in Kemer, Türkiye, from November 4 to 8, 2024. The official press release can be found here and includes the following highlights:

  • Point Cloud Coding: AI-based point cloud coding & enhanced G-PCC
  • MPEG Systems: New Part of MPEG DASH for redundant encoding and packaging, reference software and conformance of ISOBMFF, and a new structural CMAF brand profile
  • Video Coding: New part of MPEG-AI and 2nd edition of conformance and reference software for MPEG Immersive Video (MIV)
  • MPEG completes subjective quality testing for film grain synthesis using the Film Grain Characteristics SEI message
148th MPEG Meeting, Kemer, Türkiye, November 4-8, 2024.

Point Cloud Coding

At the 148th MPEG meeting, MPEG Coding of 3D Graphics and Haptics (WG 7) launched a new AI-based Point Cloud Coding standardization project. MPEG WG 7 reviewed six responses to a Call for Proposals (CfP) issued in April 2024 targeting the full range of point cloud formats, from dense point clouds used in immersive applications to sparse point clouds generated by Light Detection and Ranging (LiDAR) sensors in autonomous driving. With bit depths ranging from 10 to 18 bits, the CfP called for solutions that could meet the precision requirements of these varied use cases.

Among the six reviewed proposals, the leading proposal distinguished itself with a hybrid coding strategy that integrates end-to-end learning-based geometry coding and traditional attribute coding. This proposal demonstrated exceptional adaptability, capable of efficiently encoding both dense point clouds for immersive experiences and sparse point clouds from LiDAR sensors. With its unified design, the system supports inter-prediction coding using a shared model with intra-coding, applicable across various bitrate requirements without retraining. Furthermore, the proposal offers flexible configurations for both lossy and lossless geometry coding.

Performance assessments highlighted the leading proposal’s effectiveness, with significant bitrate reductions compared to traditional codecs: a 47% reduction for dense, dynamic sequences in immersive applications and a 35% reduction for sparse dynamic sequences in LiDAR data. For combined geometry and attribute coding, it achieved a 40% bitrate reduction across both dense and sparse dynamic sequences, while subjective evaluations confirmed its superior visual quality over baseline codecs.

The leading proposal has been selected as the initial test model, which can be seen as a baseline implementation for future improvements and developments. Additionally, MPEG issued a working draft and common test conditions.

Research aspects: The initial test model, like those for other codec test models, is typically available as open source. This enables both academia and industry to contribute to refining various elements of the upcoming AI-based Point Cloud Coding standard. Of particular interest is how training data and processes are incorporated into the standardization project and their impact on the final standard.

Another point cloud-related project is called Enhanced G-PCC, which introduces several advanced features to improve the compression and transmission of 3D point clouds. Notable enhancements include inter-frame coding, refined octree coding techniques, Trisoup surface coding for smoother geometry representation, and dynamic Optimal Binarization with Update On-the-fly (OBUF) modules. These updates provide higher compression efficiency while managing computational complexity and memory usage, making them particularly advantageous for real-time processing and high visual fidelity applications, such as LiDAR data for autonomous driving and dense point clouds for immersive media.

By adding this new part to MPEG-I, MPEG addresses the industry’s growing demand for scalable, versatile 3D compression technology capable of handling both dense and sparse point clouds. Enhanced G-PCC provides a robust framework that meets the diverse needs of both current and emerging applications in 3D graphics and multimedia, solidifying its role as a vital component of modern multimedia systems.

MPEG Systems Updates

At its 148th meeting, MPEG Systems (WG 3) worked on the following aspects, among others:

  • New Part of MPEG DASH for redundant encoding and packaging
  • Reference software and conformance of ISOBMFF
  • A new structural CMAF brand profile

The second edition of ISO/IEC 14496-32 (ISOBMFF) introduces updated reference software and conformance guidelines, and the new CMAF brand profile supports Multi-View High Efficiency Video Coding (MV-HEVC), which is compatible with devices like Apple Vision Pro and Meta Quest 3.

The new part of MPEG DASH, ISO/IEC 23009-9, addresses redundant encoding and packaging for segmented live media (REAP). The standard is designed for scenarios where redundant encoding and packaging are essential, such as 24/7 live media production and distribution in cloud-based workflows. It specifies formats for interchangeable live media ingest and stream announcements, as well as formats for generating interchangeable media presentation descriptions. Additionally, it provides failover support and mechanisms for reintegrating distributed components in the workflow, whether they involve file-based content, live inputs, or a combination of both.

Research aspects: With the FDIS of MPEG DASH REAP available, the following topics offer potential for both academic and industry-driven research aligned with the standard’s objectives (in no particular order or priority):

  • Optimization of redundant encoding and packaging: Investigate methods to minimize resource usage (e.g., computational power, storage, and bandwidth) in redundant encoding and packaging workflows. Explore trade-offs between redundancy levels and quality of service (QoS) in segmented live media scenarios.
  • Interoperability of live media Ingest formats: Evaluate the interoperability of the standard’s formats with existing live media workflows and tools. Develop techniques for seamless integration with legacy systems and emerging cloud-based media workflows.
  • Failover mechanisms for cloud-based workflows: Study the reliability and latency of failover mechanisms in distributed live media workflows. Propose enhancements to the reintegration of failed components to maintain uninterrupted service.
  • Standardized stream announcements and descriptions: Analyze the efficiency and scalability of stream announcement formats in large-scale live streaming scenarios. Research methods for dynamically updating media presentation descriptions during live events.
  • Hybrid workflow support: Investigate the challenges and opportunities in combining file-based and live input workflows within the standard. Explore strategies for adaptive workflow transitions between live and on-demand content.
  • Cloud-based workflow scalability: Examine the scalability of the REAP standard in high-demand scenarios, such as global live event streaming. Study the impact of cloud-based distributed workflows on latency and synchronization.
  • Security and resilience: Research security challenges related to redundant encoding and packaging in cloud environments. Develop techniques to enhance the resilience of workflows against cyberattacks or system failures.
  • Performance metrics and quality assessment: Define performance metrics for evaluating the effectiveness of REAP in live media workflows. Explore objective and subjective quality assessment methods for media streams delivered using this standard.

The current/updated status of MPEG-DASH is shown in the figure below.

MPEG-DASH status, November 2024.

Video Coding Updates

In terms of video coding, two noteworthy updates are described here:

  • Part 3 of MPEG-AI, ISO/IEC 23888-3 – Optimization of encoders and receiving systems for machine analysis of coded video content, reached Committee Draft Technical Report (CDTR) status
  • Second edition of conformance and reference software for MPEG Immersive Video (MIV). This draft includes verified and validated conformance bitstreams and encoding and decoding reference software based on version 22 of the Test model for MPEG immersive video (TMIV). The test model, objective metrics, and some other tools are publicly available at https://gitlab.com/mpeg-i-visual.

Part 3 of MPEG-AI, ISO/IEC 23888-3: This new technical report on “optimization of encoders and receiving systems for machine analysis of coded video content” is based on software experiments conducted by JVET, focusing on optimizing non-normative elements such as preprocessing, encoder settings, and postprocessing. The research explored scenarios where video signals, decoded from bitstreams compliant with the latest video compression standard, ISO/IEC 23090-3 – Versatile Video Coding (VVC), are intended for input into machine vision systems rather than for human viewing. Compared to the JVET VVC reference software encoder, which was originally optimized for human consumption, significant bit rate reductions were achieved when machine vision task precision was used as the performance criterion.

The report will include an annex with example software implementations of these non-normative algorithmic elements, applicable to VVC or other video compression standards. Additionally, it will explore the potential use of existing supplemental enhancement information messages from ISO/IEC 23002-7 – Versatile supplemental enhancement information messages for coded video bitstreams – for embedding metadata useful in these contexts.

Research aspects: (1) Focus on optimizing video encoding for machine vision tasks by refining preprocessing, encoder settings, and postprocessing to improve bit rate efficiency and task precision, compared to traditional approaches for human viewing. (2) Examine the use of metadata, specifically SEI messages from ISO/IEC 23002-7, to enhance machine analysis of compressed video, improving adaptability, performance, and interoperability.

Subjective Quality Testing for Film Grain Synthesis

At the 148th MPEG meeting , the MPEG Joint Video Experts Team (JVET) with ITU-T SG 16 (WG 5 / JVET) and MPEG Visual Quality Assessment (AG 5) conducted a formal expert viewing experiment to assess the impact of film grain synthesis on the subjective quality of video content. This evaluation specifically focused on film grain synthesis controlled by the Film Grain Characteristics (FGC) supplemental enhancement information (SEI) message. The study aimed to demonstrate the capability of film grain synthesis to mask compression artifacts introduced by the underlying video coding schemes.

For the evaluation, FGC SEI messages were adapted to a diverse set of video sequences, including scans of original film material, digital camera noise, and synthetic film grain artificially applied to digitally captured video. The subjective performance of video reconstructed from VVC and HEVC bitstreams was compared with and without film grain synthesis. The results highlighted the effectiveness of film grain synthesis, showing a significant improvement in subjective quality and enabling bitrate savings of up to a factor of 10 for certain test points.

This study opens several avenues for further research:

  • Optimization of film grain synthesis techniques: Investigating how different grain synthesis methods affect the perceptual quality of video across a broader range of content and compression levels.
  • Compression artifact mitigation: Exploring the interaction between film grain synthesis and specific types of compression artifacts, with a focus on improving masking efficiency.
  • Adaptation of FGC SEI messages: Developing advanced algorithms for tailoring FGC SEI messages to dynamically adapt to diverse video characteristics, including real-time encoding scenarios.
  • Bitrate savings analysis: Examining the trade-offs between bitrate savings and subjective quality across various coding standards and network conditions.

The 149th MPEG meeting will be held in Geneva, Switzerland from January 20-24, 2025. Click here for more information about MPEG meetings and their developments.

MPEG Column: 147th MPEG Meeting in Sapporo, Japan


The 147th MPEG meeting was held in Sapporo, Japan from 15-19 July 2024, and the official press release can be found here. It comprises the following highlights:

  • ISO Base Media File Format*: The 8th edition was promoted to Final Draft International Standard, supporting seamless media presentation for DASH and CMAF.
  • Syntactic Description Language: Finalized as an independent standard for MPEG-4 syntax.
  • Low-Overhead Image File Format*: First milestone achieved for small image handling improvements.
  • Neural Network Compression*: Second edition for conformance and reference software promoted.
  • Internet of Media Things (IoMT): Progress made on reference software for distributed media tasks.

* … covered in this column and expanded with possible research aspects.

8th edition of ISO Base Media File Format

The ever-growing expansion of the ISO/IEC 14496-12 ISO base media file format (ISOBMFF) application area has continuously brought new technologies to the standards. During the last couple of years, MPEG Systems (WG 3) has received new technologies on ISOBMFF for more seamless support of ISO/IEC 23009 Dynamic Adaptive Streaming over HTTP (DASH) and ISO/IEC 23000-19 Common Media Application Format (CMAF) leading to the development of the 8th edition of ISO/IEC14496-12.

The new edition of the standard includes new technologies to explicitly indicate the set of tracks representing various versions of the media presentation of a single media for seamless switching and continuous presentation. Such technologies will enable more efficient processing of the ISOBMFF formatted files for DASH manifest or CMAF Fragments.

Research aspects: The central research aspect of the 8th edition of ISOBMFF, which “will enable more efficient processing,” will undoubtedly be its evaluation compared to the state-of-the-art. Standards typically define a format, but how to use it is left open to implementers. Therefore, the implementation is a crucial aspect and will allow for a comparison of performance. One such implementation of ISOBMFF is GPAC, which most likely will be among the first to implement these new features.

Low-Overhead Image File Format

ISO/IEC 23008-12 image format specification defines generic structures for storing image items and sequences based on ISO/IEC 14496-12 ISO base media file format (ISOBMFF). As it allows the use of various high-performance video compression standards for a single image or a series of images, it has been adopted by the market quickly. However, it was challenging to use it for very small-sized images such as icons or emojis. While the initial design of the standard was versatile and useful for a wide range of applications, the size of headers becomes an overhead for applications with tiny images. Thus, Amendment 3 of ISO/IEC 23008-12 low-overhead image file format aims to address this use case by adding a new compact box for storing metadata instead of the ‘Meta’ box to lower the size of the overhead.

Research aspects: The issue regarding header sizes of ISOBMFF for small files or low bitrate (in the case of video streaming) was known for some time. Therefore, amendments in these directions are appreciated while further performance evaluations are needed to confirm design choices made at this initial step of standardization.

Neural Network Compression

An increasing number of artificial intelligence applications based on artificial neural networks, such as edge-based multimedia content processing, content-adaptive video post-processing filters, or federated training, need to exchange updates of neural networks (e.g., after training on additional data or fine-tuning to specific content). For this purpose, MPEG developed a second edition of the standard for coding of neural networks for multimedia content description and analysis (NNC, ISO/IEC 15938-17, published in 2024), adding syntax for differential coding of neural network parameters as well as new coding tools. Trained models can be compressed to at least 10-20% for several architectures, even below 3%, of their original size without performance loss. Higher compression rates are possible at moderate performance degradation. In a distributed training scenario, a model update after a training iteration can be represented at 1% or less of the base model size on average without sacrificing the classification performance of the neural network.

In order to facilitate the implementation of the standard, the accompanying standard ISO/IEC 15938-18 has been updated to cover the second edition of ISO/IEC 15938-17. This standard provides a reference software for encoding and decoding NNC bitstreams, as well as a set of conformance guidelines and reference bitstreams for testing of decoder implementations. The software covers the functionalities of both editions of the standard, and can be configured to test different combinations of coding tools specified by the standard.

Research aspects: The reference software for NNC, together with the reference software for audio/video codecs, are vital tools for building complex multimedia systems and its (baseline) evaluation with respect to compression efficiency only (not speed). This is because reference software is usually designed for functionality (i.e., compression in this case) and not performance.

The 148th MPEG meeting will be held in Kemer, Türkiye, from November 04-08, 2024. Click here for more information about MPEG meetings and their developments.