Quality of Multimedia Experience in the Age of Generative AI

Generative AI Opens New Possibilities for QoE

Quality of Experience (QoE) has long been a central topic in multimedia research, providing a human-centered perspective on content quality, system performance, and user perception [Möller 2014]. Through subjective assessment, predictive modeling, and QoE-aware optimization, researchers have developed approaches to improving multimedia services under diverse network and resource constraints.

The rapid advancement of generative AI is changing how multimedia content is created, delivered, and experienced. Unlike conventional multimedia services, where content is typically prepared for users, generative AI enables content to be created, edited, and adapted in response to user needs. Through natural language instructions and iterative feedback, users can continuously refine their requests, bringing content creation, interaction, and consumption closer together. Meanwhile, content generation, model inference, user interaction, and delivery are becoming increasingly interconnected, expanding the opportunities for QoE assessment and optimization.

These developments raise new questions about how multimedia experiences are formed, how they can be assessed and modeled, and how QoE can guide generative AI systems toward better user experiences. This column explores these directions, as illustrated in Fig. 1, and discusses their implications for the future of multimedia services.
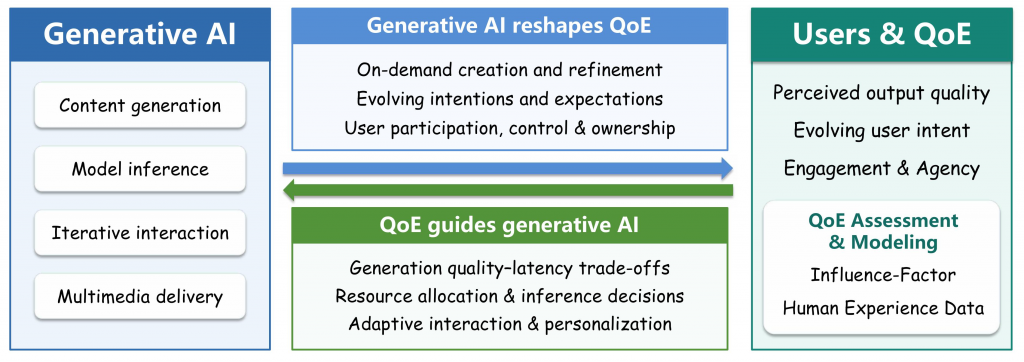
Figure 1: A conceptual framework illustrating how generative AI reshapes QoE through dynamic user interaction, while QoE assessment and modeling guide the optimization of generative AI systems toward more human-centered experiences.

How Generative AI is Transforming QoE

In traditional multimedia services, QoE primarily reflects users’ perceptions of delivered content and service quality [Möller 2014]. Advances in generative AI have enabled users to actively participate in content creation and refinement. Through natural language instructions and iterative feedback, users can shape generated content and build upon previous results, increasingly intertwining content quality with interaction experience. This shift gives users a greater role in shaping their own multimedia experiences.

Evolving User Intent and Expectations

Interactions with generative AI may lead to changes in users’ intentions and expectations. Initial generated results may inspire new ideas, encourage further exploration, or prompt users to reconsider their original goals. Subsequent interactions may further reshape both the generated content and users’ perceptions of the experience, creating a dynamic relationship among user intentions, system behavior, and perceived quality. Understanding this evolving relationship presents an important direction for QoE research in the age of generative AI.

Beyond Output Quality: User Engagement and Agency

In interactive generative AI applications, users’ experiences may depend on factors beyond output quality, such as their ability to express intentions, maintain control, explore alternatives, and develop a sense of ownership over the resulting content [Amershi 2019, Shneiderman 2020]. For example, a recent study found that model-led collaboration improved creative output quality but reduced idea diversity and users’ perceived ownership, while human-led approaches achieved a better balance among these aspects [Maier 2026]. Together, these developments suggest an evolving perspective on multimedia QoE, in which generated content, user participation, and interactive processes jointly contribute to the overall experience.

Rethinking QoE Assessment and Modeling

Perceptual quality assessment of AI-generated content has attracted growing research attention [Wang 2025]. The dynamic and interactive nature of generative AI experiences introduces new challenges, calling for new approaches to understanding and modeling QoE [Zhou 2026].

QoE Modeling based on Influence Factors

One promising approach is to identify key influence factors and investigate their relationships with QoE, building on established methodologies in traditional QoE research. These factors may include perceptual quality, semantic consistency, generation speed, response latency, and interaction characteristics. Controlled subjective experiments can help examine their effects and develop interpretable QoE models. Existing studies have explored QoE modeling for interactive LLM services using such approaches [Hupont 2026, Schlechte 2025]. However, the relevant factors and their relationships may vary considerably across different generative AI tasks and contexts, making such models difficult to generalize.

QoE Modeling from Human Experience Data

Advances in foundation models offer another approach to QoE modeling by learning directly from human experience data. Such data may include multimodal content, interaction histories, user feedback, and contextual information, which could be used to train AI-based QoE predictors that approximate human QoE judgments. However, since QoE fundamentally concerns human experience, continuous validation against real human feedback is essential to prevent the evaluation objective from shifting toward model preferences.

How QoE can Guide Generative AI Systems

QoE has long guided multimedia service optimization, including adaptive streaming and resource allocation, to balance perceived quality and system constraints [Seufert 2014]. Generative AI further expands this optimization space by allowing QoE to influence content generation itself, alongside inference, interaction, and delivery. With reliable QoE models, generative AI systems could make decisions based on anticipated user experience, such as balancing generation quality against response time, allocating resources according to user needs, or adapting interaction strategies to different tasks. Recent studies have explored using human-aligned quality assessments as reward signals to improve generative video models [Wang 2025 (LOVE)], suggesting the potential for extending such approaches toward broader QoE-driven optimization. Looking ahead, QoE could become an integral part of generative AI systems, guiding how content is created, refined, and delivered in response to user expectations. This would open opportunities for connecting human experience with generative model development and intelligent service optimization.

Outlook and Takeaways

The rapid development of generative AI is opening new directions for QoE research. Generative AI is reshaping how users create and experience multimedia content, calling for new approaches to understanding and modeling dynamic user experiences. Meanwhile, QoE offers a human-centered perspective to guide content generation, interaction, and system optimization. Looking ahead, QoE-in-the-loop generative multimedia represents a promising direction for enabling more adaptive, personalized, and experience-driven services.

This vision aligns closely with the discussions envisioned for QoMEX’27, which will explore the evolving landscape of quality of multimedia experience in the age of generative AI. As generative technologies reshape how multimedia is created, delivered, and experienced, the conference invites the research community to explore emerging challenges and opportunities in QoE assessment, modeling, and optimization, and to advance more human-centered multimedia systems.

These directions reflect the expanding scope of QoE research and reaffirm QoMEX as an important forum for exchanging ideas and advancing multimedia experience research. The 19th International Conference on Quality of Multimedia Experience (QoMEX’27) will take place in Shanghai, China, from July 6 to 9, 2027. More information is available at https://qomex2027.itec.aau.at/.

References

  • [Möller 2014] Sebastian Möller and Alexander Raake. 2014. Quality of experience. Springer.
  • [Amershi 2019] Saleema Amershi, Dan Weld, Mihaela Vorvoreanu, Adam Fourney, Besmira Nushi, Penny Collisson, Jina Suh, Shamsi Iqbal, Paul N. Bennett, Kori Inkpen, Jaime Teevan, Ruth Kikin-Gil, and Eric Horvitz. 2019. Guidelines for Human-AI Interaction. In Proceedings of the 2019 CHI Conference on Human Factors in Computing Systems (CHI ’19). Association for Computing Machinery, New York, NY, USA, Paper 3, 1–13. https://doi.org/10.1145/3290605.3300233
  • [Shneiderman 2020] Shneiderman, B. 2020. Human-Centered Artificial Intelligence: Reliable, Safe & Trustworthy. International Journal of Human–Computer Interaction, 36(6), 495–504. https://doi.org/10.1080/10447318.2020.1741118
  • [Maier 2026] Sebastian Maier, Manuel Schneider, and Stefan Feuerriegel. 2026. Partnering with Generative AI: Experimental Evaluation of Model-Led and Human-Led Interaction in Human-AI Co-Creation. In Proceedings of the 2026 CHI Conference on Human Factors in Computing Systems (CHI ’26). Association for Computing Machinery, New York, NY, USA, Article 1260, 1–28. https://doi.org/10.1145/3772318.3791185
  • [Wang 2025] Jiarui Wang, Huiyu Duan, Guangtao Zhai, Juntong Wang, and Xiongkuo Min. 2025. AIGV-ASSESSOR: Benchmarking and Evaluating the Perceptual Quality of Text-to-Video Generation with LMM. In 2025 IEEE/CVF conference on computer vision and pattern recognition (CVPR). IEEE, 18869–18880. https://doi.org/10.1109/CVPR52734.2025.01758
  • [Zhou 2026] Wei Zhou, Hadi Amirpour, Tobias Hoßfeld, and Christian Timmerer. 2026. Quality of Multimedia Experience Meets Machine Intelligence. SIGMultimedia Rec. 18, 1, Article 3 (January 2026), 1 pages. https://doi.org/10.1145/3811013.3811016
  • [Hupont 2026] Isabelle Hupont, Katrien De Moor, Lea Skorin-Kapov, Martin Varela, Tobias Hoßfeld, and Christian Timmerer. 2026. Rethinking QoE in the Age of AI: From Algorithms to Experience-Based Evaluation. SIGMultimedia Rec. 17, 4, Article 3 (October 2025), 1 pages. https://doi.org/10.1145/3811005.3811008
  • [Schlechte 2025] Florian Schlechte, Yusra Tasnim Farooqi, and Matthias Hirth. 2025. Assessing the Influence of End-to-End Request Latency and Response Length on Waiting Time Satisfaction of LLM Users. In 2025 17th International Conference on Quality of Multimedia Experience (QoMEX). IEEE, 1–4. https://doi.org/10.1109/QoMEX65720.2025.11219949
  • [Seufert 2014] Michael Seufert, Sebastian Egger, Martin Slanina, Thomas Zinner, Tobias Hoßfeld, and Phuoc Tran-Gia. 2014. A Survey on Quality of Experience of HTTP Adaptive Streaming. IEEE Communications Surveys & Tutorials 17, 1 (2014), 469–492. https://doi.org/10.1109/COMST.2014.2360940
  • [Wang 2025 (LOVE)] Jiarui Wang, Huiyu Duan, Ziheng Jia, Yu Zhao, Woo Yi Yang, Zicheng Zhang, Zijian Chen, Juntong Wang, Yuke Xing, Guangtao Zhai, et al. 2025. LOVE: Benchmarking and Evaluating Text-to-Video Generation and Video-to-Text Interpretation. arXiv preprint arXiv:2505.12098 (2025). https://doi.org/10.48550/arXiv.2505.12098
MPEG Column: 156th MPEG Meeting

At the 156th MPEG meeting in Hangzhou, China, MPEG Video Coding (WG 4) advanced Video Coding for Machines (VCM, ISO/IEC 23888-2) to Final Draft International Standard (FDIS) and Feature Coding for Machines (FCM, ISO/IEC 23888-4) to Draft International Standard (DIS). VCM compresses video for analysis after decoding, while FCM compresses the intermediate features exchanged between parts of a model. In parallel, MPEG Systems (WG 3) is exploring how to package both types of bitstream for storage and delivery. The full press release is available here.

Video Coding for Machines

VCM combines a conventional video codec with tools that adapt the video before encoding and process the decoded signal before analysis. An encoder can reduce spatial resolution, transmit fewer frames, or allocate more bits to regions that matter for the downstream task. The receiver can then apply operations such as upsampling or frame synthesis before passing the reconstructed video to the vision model [Eimon 2026].

In resolving comments on the VCM draft, WG 4 addressed the delivery of neural network weights and set an upper limit on the number of regions of interest. The group also updated the reference software so that the VCM multiplexer and demultiplexer can operate independently of the Versatile Video Coding (VVC) Test Model. This allows the reference pipeline to use an alternative inner codec such as High Efficiency Video Coding (HEVC). Other updates configure bit-depth restoration automatically based on day or night conditions and add supplemental signaling related to decoder timing and buffering. WG 4 also established a study on verification testing.

Feature Coding for Machines

The input to an FCM encoder is a feature tensor, an array of activations produced by the first part of a model. The encoder can transform the tensor into a more compact representation and quantize its values for transmission. The receiver reconstructs the tensor and passes it to the remaining layers. The split point affects how much computation each device performs, how much data the sender transmits, and which features are available to downstream tasks [Eimon 2026, Yang 2024].

The FCM DIS specifies the bilinear interpolation used in reconstruction and the bit widths of floating-point syntax elements. Its levels account for the neural network used to invert the feature transform and the size of the transformed tensor. WG 4 also simplified parts of the reconstruction network, introduced lower-complexity integer convolution, and adapted feature refinement to the distribution of the reconstructed values. The draft supports temporal scalability and aligns the ordering of picture-level metadata with that of the inner coded data to support random access.

Separately, WG 4 updated channel rearrangement and nonlinear quantization in the FCM Test Model and introduced a method based on singular value decomposition to estimate channel importance. The group updated the Common Test and Training Conditions with a single-layer feature-transform configuration, 4:2:0 input for the HEVC Main 10 inner codec, and a revised configuration for the Neural Network Coding (NNC) inner codec. Further studies will examine FCM levels and deterministic operation for conformance testing.

Systems Carriage for VCM and FCM

Through the Exploration on Systems technology for AI-based media standards (SyfAI), MPEG Systems (WG 3) is studying how to carry VCM and FCM bitstreams. The Hangzhou outputs include separate preliminary carriage drafts for VCM and FCM [MPEG156]. The VCM proposal describes how to package single-layer VCM streams in the ISO Base Media File Format (ISOBMFF, ISO/IEC 14496-12), either as a file for storage or as an initialization segment followed by media segments for streaming.

The VCM proposal also describes how the container conveys timing and decoder configuration. An inner-coded picture and its restoration data share the same timed sample. A picture synthesized at the decoder has its own timed sample carrying the synthesis instructions. The proposed configuration box carries initialization information for both VCM and its inner codec.

Offshore Wind Turbine Inspection

When several inspection drones share a limited wireless link, the choice of what to send depends on how much analysis each drone can perform onboard and what the ground station needs to combine observations from different cameras.

DORBINE [DORBINE], a collaboration between the University of Klagenfurt and AIR6 Systems funded by the Austrian Research Promotion Agency (FFG), aims to inspect wind turbine blades while the turbines continue generating power. In their IEEE Access paper, Leopold et al. describe how several drones divide the work of observing the turbine, capturing close-up blade imagery, and measuring blade deflection. A ground station coordinates the drones and combines data from their cameras. Experiments on a scaled turbine model demonstrated persistent blade identification and deflection estimation during rotation [Leopold 2026].

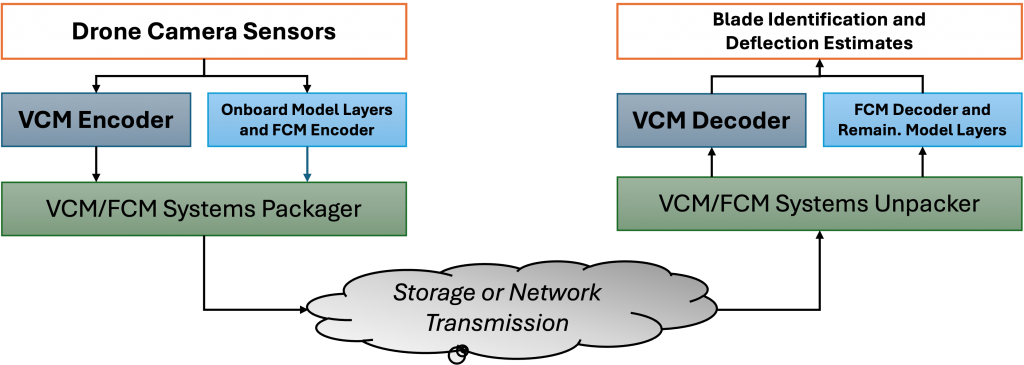
Figure 1 shows how VCM and FCM could fit into a DORBINE-style inspection. In the VCM path, the drone encodes video, and the ground station reconstructs the frames and runs the full inspection model. In the FCM path, the drone runs the first layers of the model and encodes their output. The ground station reconstructs those features and runs the remaining layers. In both paths, the sender packages the bitstream for storage or transmission, and the receiver extracts it and passes it to the appropriate decoder.

Figure 1: Proposed VCM and FCM workflow for drone-based wind turbine inspection. Both paths support blade identification and deflection estimation at the ground station.

Research Directions for the ACM SIGMM Community

Compression for machine accuracy and human review. How much can VCM reduce bitrate while preserving small-defect recall and keeping deflection estimates within a target error? Compare how encoders allocate bits across blade regions and frames, and assess whether engineers can verify suspected defects from selected clips [Eimon 2026].

Adaptive split inference. When should a drone send VCM video, transmit FCM features, or run the full model onboard? Replay the same inspection under different network conditions and onboard compute budgets. Compare bitrate, time to result, and onboard energy per inference at comparable task performance [Eimon 2026].

Feature reuse across tasks and model versions. Can one compressed feature stream support blade identification, surface defect detection, and deflection estimation? Test which tasks can share a representation and whether a ground-station model can be upgraded while remaining compatible with feature extractors already deployed on drones [Yang 2024].

Coordinated coding across drones. When several drones observe the same rotating blade over a shared uplink, which views should receive more of the available bitrate? Compare independent encoding with a scheduler that prioritizes complementary views. Measure how synchronization errors, missing views, and compression affect the combined estimate [Leopold 2026].

Carriage and recovery under variable network conditions. What information does a receiver need to join a live stream, recover after segment loss, or resume inference after a configuration change? Measure the time to the first usable result and the effect of stale or missing inputs on the inspection outcome [MPEG156].

Reproducible end-to-end benchmarks. Pair synchronized footage and task annotations with recorded network traces. Compare conventional video coding with remote inference, VCM, FCM, and fully onboard inference on the same source material. Hold out entire turbines or flights to test whether the results generalize beyond the sequences used for tuning.

Concluding Remarks

The Hangzhou milestones give the multimedia research community a basis for evaluating coding, inference, and delivery together. Offshore wind turbine inspection offers a concrete test of whether these technologies can deliver reliable blade measurements within the bandwidth and energy available during a flight.

The 157th MPEG meeting will be held in Brisbane, Australia, from January 18 to 22, 2027. Click here for more information about MPEG meetings and ongoing developments.
References

JPEG Column: 112th JPEG Meeting in Leiria, Portugal

JPEG XE becomes an International Standard

The 112th JPEG meeting was held in Leiria, Portugal, from 6 to 10 July 2026.

This meeting was marked by several major achievements. JPEG XE final text of the International Standard was issued, and it is expected to be published in the near future by both ISO/IEC and ITU-T as twin texts. This is a major milestone, as JPEG XE defines the first standard for event-based vision, with the support of major industrial and academic players and under the auspices of three standardization organizations.

The following sections summarise the main highlights of the 112th JPEG meeting.

  • JPEG XE becomes an international standard.
  • JPEG Trust has major advances in its different parts.
  • JPEG DNA proceeds as Draft International Standard.
  • JPEG Pleno continues work on quality evaluation of coded light fields.
  • JPEG XS enables slice-level embedded metadata.
  • JPEG AI proceeds with the implementation’s performance evaluation.
  • JPEG RF exploration launches a call for datasets.

JPEG XE

The joint effort between ITU-T SG21 and ISO/IEC JTC1/SC29/WG1 on JPEG XE continues to make significant progress toward establishing a comprehensive international framework for event-based vision coding. At its 112th meeting, the JPEG Committee completed the final International Standard text of ISO/IEC 26112-1 after successful approval of the DIS ballot and requested its publication. This milestone marks JPEG XE as the first international standard for lossless coding of visual events produced by event vision sensors, providing a standardized and interoperable foundation for the rapidly growing event-based vision ecosystem. Developed jointly between ISO, IEC and ITU-T, the standard ISO/IEC 26112 will also be published as ITU-T Recommendation T.841.1 in the near future.

The JPEG Committee also completed the DIS texts of ISO/IEC 26112-2, Profiles and Levels, and ISO/IEC 26112-3, Reference Software, both of which were approved for progression to the DIS stage. Under the joint ISO, IEC and ITU-T collaboration, these standards will also become ITU-T Recommendations T.841.2 and T.841.3, respectively. ISO/IEC 26112-2 includes the Embedded Lossless Constrained Profile, specifically designed to enable interoperability with the MIPI CSI-2 v4.2 Event Stream Protocol (ESP) specification. The profile represents the successful outcome of a close liaison between the MIPI Alliance and the JPEG Committee to promote industry-wide interoperability for event-based imaging systems.

Work will now continue on ISO/IEC 26112-4, which will define formal compliance testing procedures, and on ISO/IEC 26112-5, which will specify file formats and metadata structures for the storage and exchange of event data. In particular, Part 5 will introduce mechanisms enabling synchronization of event timestamps with real-world atomic time references, supporting demanding industrial, scientific, automotive, and machine vision applications. In parallel, the JPEG Committee will explore advanced coding technologies aimed at further improving both lossless and lossy compression efficiency for event data.

The JPEG XE Joint Ad Hoc Group, established under the collaboration between ITU-T SG21/Q7 and ISO/IEC JTC1/SC29/WG1, was reestablished to continue the development of the JPEG XE family of standards. The JPEG Committee remains committed to delivering a unified, open, and internationally recognized framework for event-based vision technologies, accelerating interoperability, innovation, and adoption across this emerging field. If you are interested in contributing to this effort, please consider joining this joint AHG.

JPEG Trust

At the 112th JPEG meeting in Leiria, major advances were made across all parts of JPEG Trust. The 2nd edition of JPEG Trust Part 1 – Core Foundation has been completed and is progressing towards publication, incorporating assertions for attributions and declarations of rights. JPEG Trust Part 2 – Trust Profiles and Reports, which extends the framework specified in Part 1 with functionalities for Trust Profiles and Trust Reports, was promoted to FDIS stage. JPEG Trust Part 3 – Media Asset Watermarking, incorporating specific tools and associated assessment methodologies for usage scenarios that rely on invisible watermarking of media assets, is currently at the DIS stage. JPEG Trust Part 4 – Reference Software is also at the DIS stage, with further extensions planned to include additional software implementations and test datasets.

Looking ahead, JPEG Trust is expanding its activities to address emerging requirements for media authenticity and transparency, while continuing to evolve the JPEG Trust framework. A revised structure for the JPEG Trust family of standards is being considered to provide a clearer separation between the core trust framework, provenance, attribution, and rights declarations, watermarking, and emerging detection technologies.

Preparations for the first JPEG Trust Summit, to be held on 12–13 November 2026 in London, are well underway. More information on upcoming events related to JPEG Trust can be found on the jpeg.org website.

JPEG DNA

At its 112th meeting, the JPEG Committee continued the standardization and validation activities for JPEG DNA Part 1 (ISO/IEC 25508-1), which is currently undergoing DIS ballot. The DIS stage follows a multi-year standardization effort that began with the Final Call for Proposals at the 99th JPEG meeting and progressed through the creation of the Verification Model at the 102nd meeting, the first Working Draft at the 103rd meeting, the Committee Draft, and the study DIS text produced at the 108th meeting. A significant part of the meeting was dedicated to analyzing and continuing the JPEG DNA Core Experiments. In particular, the results of Core Experiment 11 (CE11) were discussed, providing further validation of the end-to-end JPEG DNA workflow on synthetic DNA. The experiment demonstrated the feasibility of recovering and decoding the information stored in DNA while also highlighting areas where further improvements to the decoding process are desirable, especially for the header encoding/decoding. Based on these results, the JPEG Committee identified the need for a further Core Experiment, CE12, aimed in particular at improving and further validating the decoding process under realistic synthesis and sequencing conditions.

JPEG Pleno

JPEG Pleno Light Field Quality Assessment advanced its work on subjective and objective quality assessment activities. The group reviewed the user documentation for the subjective assessment software, further investigated the performance of the deep-learning-based metric currently under consideration for inclusion in the standard, and discussed the next steps for objective quality assessment standardization activities.

At its 112th meeting, the JPEG Committee approved the release of the Common Test Conditions (CTC) for JPEG Pleno Light Field Coding v4.0 document, establishing a unified framework to ensure consistency and comparability across core experiments. The document defines testing procedures, software reference configurations, and environmental settings required to evaluate and compare light field coding solutions accurately. The CTC document is supported by the JPEG Pleno Light Field Coding (LFC) CTC Toolkit, a modular software toolkit with automated scripts for file conversion, coding, and quality metrics to assist in executing the CTC guidelines. AHG.

JPEG XS

JPEG XS, the lightweight low-latency image and video compression standard, continues to expand its capabilities while preserving its core strengths of visually lossless quality, ultra-low latency, and low implementation complexity. Following the 112th JPEG meeting, the JPEG Committee is happy to announce the publication of ISO/IEC 21122-1:2024 AMD1 that introduces the SYM marker to allow user-defined metadata to be embedded at the slice level. This feature can be leveraged to facilitate the needs of video transmission in AR/VR applications. Furthermore, ISO/IEC 21122-2:2024 AMD1, which adds new levels, sublevels, and a frame buffer level to better address proxy-stream extraction use cases, completed the DIS approval process and was issued for publication as a new amendment. The JPEG Committee also progressed ISO/IEC 21122-2:2024 AMD2, which introduces the new CMainBayer profile for raw Bayer content. The profile is designed to simplify implementations while maintaining backward decoding compatibility with existing MainBayer and HighBayer decoders. Following a successful technical evaluation, the amendment was approved to advance to the DIS stage, marking the next step toward standardization.

JPEG AI

At its 112th meeting, the JPEG Committee continued advancing JPEG AI, reviewing progress in its Core Experiments on hardware deployment performance, bit-exact reconstruction, and objective and subjective evaluation. New results were reported for a heterogeneous CPU–GPU–FPGA deployment in which the codec is split at the quantized latent representation, mapping the main analysis and synthesis transforms to GPU and the hyperprior transforms to FPGA, while entropy coding and bitstream handling remain on CPU, and the rate–distortion behaviour is preserved. Evaluated on 100 images at native 2K resolution across five bitrates, this deployment achieved a runtime close to GPU-only execution while reducing energy consumption, yielding an improved end-to-end energy-delay product with respect to both GPU-only and FPGA-only execution. Progress was also reported towards cross-platform reproducible reconstruction, where floating-point convolutions are replaced by per-channel integer arithmetic derived from a two-step quantization procedure; all convolutional layers of the base operating point encoder have now been quantized, with the remaining components to follow. In parallel, a systematic evaluation of JPEG AI was set in motion, encompassing a new dataset and updated common training and test conditions, ablation studies, objective and subjective comparisons with state-of-the-art conventional and learning-based codecs, and a computational complexity assessment. Further contributions addressed low-latency FPGA deployment and compressed-domain processing for geospatial segmentation. AHG.

JPEG RF

At the 112th JPEG meeting, the JPEG Committee made significant progress in its JPEG Radiance Fields activity, which explores future standardization needs for compact and high-quality coding of radiance field representations. A Call for Datasets was finalized to broaden the content available for future benchmarking, advanced discussions on Common Test Conditions and evaluation protocols, and the roadmap toward a future Call for Proposals was reviewed. The meeting also progressed work on subjective and objective quality assessment pipelines, including an extensive evaluation of objective metrics and the identification of promising directions for future anchor coding technologies. These activities strengthen the technical foundation for a transparent and reproducible JPEG RF standardization process.

“At the 112th meeting, the JPEG Committee released JPEG XE as the first ever International Standard for visual event lossless coding, providing a crucial tool for interoperability between event-based imaging systems. This will be instrumental for the success of imaging and machine vision applications that rely on event sensors.” said Prof. Touradj Ebrahimi, the Convenor of the JPEG Committee.

Reviving the PhD Thesis Column at ACM SIGMM Records

Doctoral dissertations represent some of the most substantial and original research contributions in multimedia. They reflect years of exploration, technical innovation, and scientific discovery, often opening new directions for the broader research community.

ACM SIGMM Records has historically provided a platform for showcasing doctoral dissertations in multimedia. I am excited to help revive this tradition through the PhD Thesis Column, bringing renewed attention to the outstanding research contributions of emerging scholars across our community.

About Me

Image of Mallesham Dasari - Northeastern University College of Engineering

I am Mallesham Dasari, an Assistant Professor in the Department of Electrical and Computer Engineering at Northeastern University, where I lead the Spatial Intelligence Research Group (SINRG). My research spans multimedia systems, computer networking, immersive computing, and spatial intelligence, with particular interests in 3D/4D media, extended reality, and AI-driven multimedia systems. Many important ideas emerge from PhD dissertations but do not always reach audiences beyond their immediate research communities. I see this column as an opportunity to help bridge that gap.

Vision for the Column

My vision is to reestablish the PhD Thesis Column as a regular feature of ACM SIGMM Records, celebrating doctoral research and making it accessible to the broader multimedia community.

The column will highlight recently completed dissertations spanning the breadth of multimedia research, including multimedia understanding and generation, multimodal AI, search and recommendation, reasoning, human-centered computing, embodied and immersive experiences, multimedia systems, and emerging applications. Rather than simply reproducing dissertation abstracts, each contribution will tell the story behind the research: What motivated the work? What fundamental challenges did it address? What are its most significant contributions? And what new research opportunities does it create?

I hope the column will serve three purposes: recognize the achievements of recent PhD graduates, help researchers discover ideas beyond their immediate specializations, and inspire current doctoral students exploring new research directions.

How Students Can Contribute

I warmly invite recent PhD graduates and their advisors to contribute to the column. Contributors are encouraged to prepare a concise, accessible summary covering:

  • Research motivation: What problem does the dissertation address, and why is it important?
  • Key contributions: What are the main technical innovations and research findings?
  • Impact: How does the work advance multimedia research or enable new applications?
  • Future directions: What open questions and opportunities emerge from the dissertation?

Submissions should also include the thesis title, author, institution, advisor(s), graduation year, and links to the dissertation and relevant research artifacts. Check out previous PhD thesis summaries highlighted on the SIGMM records webpage here: https://records.sigmm.org/scientific-reports/catlist-example/

I look forward to working with the SIGMM community to highlight the next generation of multimedia researchers and their contributions.

Interested in contributing or nominating a dissertation? Please contact me at m.dasari@northeastern.edu.

Mallesham Dasari
Assistant Professor, Northeastern University, USA
Editor, PhD Thesis Column, ACM SIGMM Records

Webpages: mallesham.com | sinrg.org

MediaEval Multimedia Benchmark: From 2026 in Amsterdam to 2027 in Bucharest

Introduction including co-location at ICMR

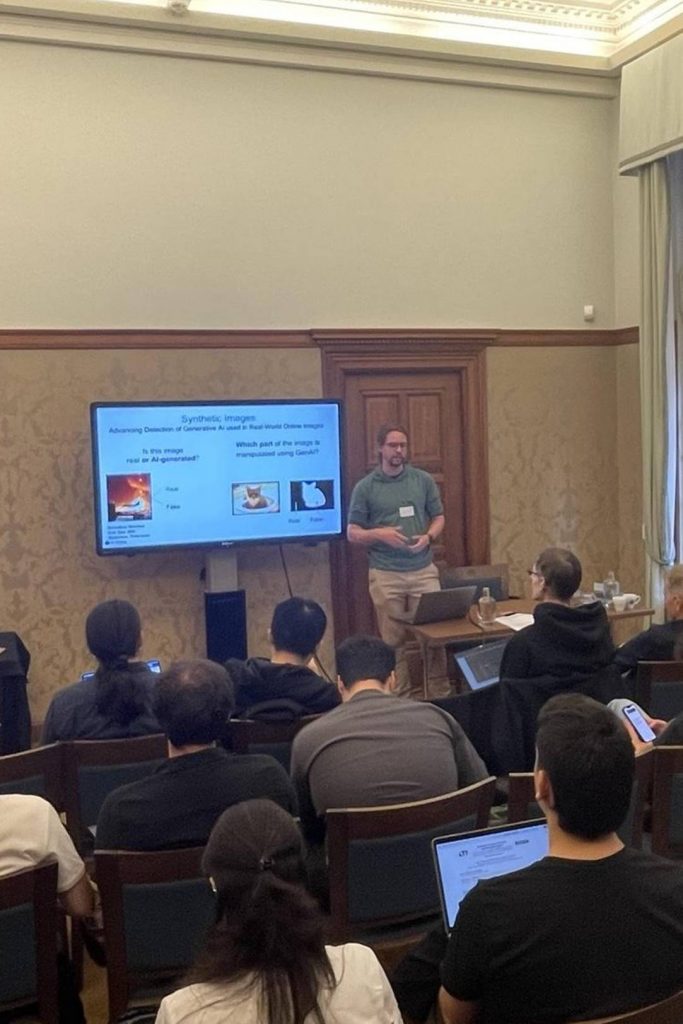
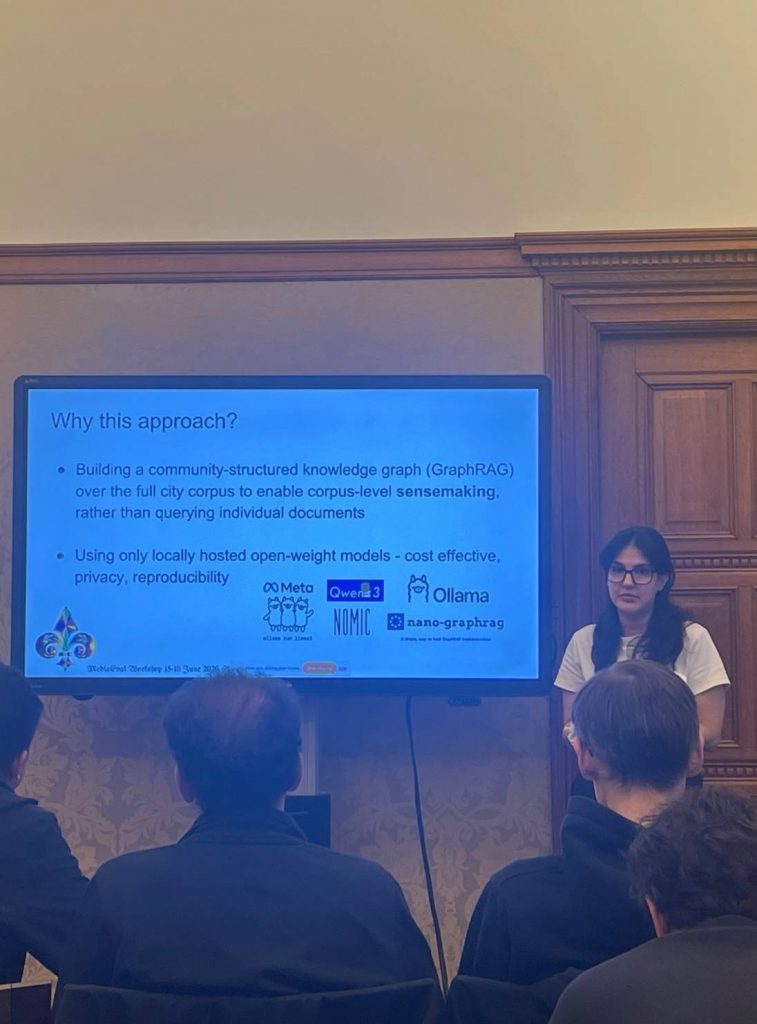
MediaEval, the benchmarking initiative for Multimedia Evaluation, brings together researchers each year to focus their research on a set of challenging tasks involving multimedia data. This year, MediaEval was co-located with the ACM International Conference on Multimedia Retrieval (ICMR) in Amsterdam and also welcomed participants online. Again in 2026, MediaEval was supported by SIGMM. The MediaEval community is thankful to both SIGMM and the organizers of ACM ICMR for making possible the success of the 16th annual MediaEval workshop.

The tasks offered by MediaEval in 2026 covered a diverse range of domains, spanning social media, medicine, media processing, media retrieval, and generative AI, while maintaining the emphasis on human-centered AI, multimodality, and socially relevant topics.

Medico proposed a Visual Question Answering task for gastrointestinal imaging, with an emphasis on explainability, clinical safety, and multimodal reasoning. Memorability used data from short movie excerpts and commercial videos to determine the long-term memorability of videos. Missing Pieces and Misinformation challenged participants to build models that can detect arguments with implicit premises or conclusions in controversial social media posts. MultiSumm tasked participants with creating a multimodal summary of food sharing initiative (FSI) activities in a city, satisfying specified criteria. The NewsImages organizers created a task that pairs news articles with the most fitting images depicting their contents. Finally, Synthetic Images sought to advance the detection and localization of generative AI used on real-world images.

Workshop Keynote

Jaap Kamps of the University of Amsterdam delivered a keynote which gave workshop participants a perspective on the history of AI research in the Netherlands. The keynote discussed the intersection between Dutch Cultural Heritage and AI research, which dates back 25 years. Dutch expertise in AI for Cultural Heritage has been built over the years in a series of programs and projects, the latest of which is HAICu “digital Humanities – Artificial Intelligence – Cultural heritage”funded within a program of the Dutch Research Agenda. HAICu contributed to the organization of the 2026 MediaEval NewsImages task.

The keynote discussed the origin story of MediaEval, which began in 2008 as a track at CLEF called VideoCLEF. The track worked with data from Sound & Vision, the national institute for media culture in the Netherlands. Participants were invited to select videos to create topic-based RSS-feeds and represent each video by extracting a keyframe. The keynote also discussed the important role that digitization plays in preserving cultural heritage and perspectives on the ways that AI can help bring cultural heritage to life.

MediaEval Distinctive Mentions

MediaEval has a tradition of highlighting the contributions of participants who transcend traditional benchmarking. Such participants go beyond a narrow focus on test-set performance and also analyze interesting aspects of the tasks that they participate in. Their contributions include in-depth analysis of the data or exploration of interesting modalities, multimodal approaches, and the implications of modalities for a given task. The MediaEval benchmark iteratively improves its tasks on the basis of insights provided by participants that are related to the methodology or concepts deep within the tasks. MediaEval Distinctive Mentions (MDMs) have been a constant presence in MediaEval since 2013, representing one of the ways our initiative nudges participants towards broadening the focus beyond performance-only approaches.

This year, several teams stood out for digging deep into the data provided by the organizers, and were awarded MDMs: NTHU-CY (Hao-Tien Yu and Yi-En Dong) for their rigorous insight into EEG subject-variability biases in Memorability and to Jarno van Arkel, who created a comprehensive account of annotator disagreement in the Missing Pieces task. The work of team FAST-NU (Moez Ur Rehman) also received an MDM in the Missing Pieces task for their failure analysis that illuminated the task.

Other mentions recognized methodological contributions. MDMs were awarded for the generalizability of participating models, to team AIT-SoftBank (Hengwei Zhao and Takayuki Hori) and for a novel fusion method of complementary features to team ANLAM-NET-M (Berkay Bayramoglu, Ismail Erol, Rukiye Savran Kiziltepe, and Murat Karakus), both of the two teams in the Synthetic Images task, as well as for the results of their non-specialist models in the Medico task to team LaSID–UFSCar.

Early-Career Researchers at MediaEval

MediaEval puts SIGMM support to work in order to fund early-career researchers to take part in the MediaEval workshop, who would not have otherwise been able to attend the workshop in person. Three travel-grant awardees report on their experiences at MediaEval:

One aspect of MediaEval I truly value is its community-wide effort to go beyond mere metric-chasing and focus on a genuine ‘quest for insights.’ This spirit was incredibly evident throughout the event in Amsterdam. While we specifically presented our work in the ‘Memorability’ and ‘Synthetic Images’ tasks, the workshop provided an amazing platform to engage in deeply rewarding discussions with colleagues from around the globe. Observing the diverse and innovative approaches applied across all the entirely different tasks – not just our own – was a fascinating learning experience. It was truly inspiring to see different disciplines come together to share deeper reflections on their results in such a supportive environment. I thoroughly enjoyed being a part of this dynamic community, and I will definitely be participating again next year!

Berkay Bayramoğlu, Undergraduate Student, Software Engineering, Ankara University

Attending the MediaEval Benchmark for the very first time has been an incredible and unforgettable experience. Traveling all the way from Turkey with my teammate Berkay, we were completely captivated by the charm of Amsterdam and the breathtaking, historic architecture of the KIT Royal Tropical Institute building. This year, we challenged ourselves by participating in both the Synthetic Images and Media Memorability tasks, focusing our efforts on experimenting with novel, creative approaches. The workshop presentations were immensely informative, offering profound academic insights that helped us clearly identify key areas to improve in our own project while sparking fresh ideas for our future research directions. Beyond the technical sessions, connecting with researchers from various countries and experiencing different cultures was deeply rewarding. We absolutely plan to stay an active part of this inspiring community and look forward to participating in future MediaEval editions!

İsmail Erol, Undergraduate Student, Software Engineering, Ankara University

Participating in the MultiSumm task at MediaEval 2026 was my first experience with a MediaEval challenge, and it was an incredibly rewarding one. I joined the task because I had several ideas for approaching multimodal summarization and wanted to test my methodology and research skills in a benchmark setting. Throughout the challenge, the support from the organizers and supervisors was outstanding, creating a welcoming and encouraging environment.

I was very happy to be part of the MediaEval community, present our work, and learn from the approaches developed by other participants. Meeting researchers and students from different countries and at different stages of their academic journeys gave me valuable new perspectives. One of the highlights was the technical retreat sessions, where participants could discuss their methods in depth and receive feedback from people with diverse backgrounds and expertise.

I also appreciated that MediaEval encourages creativity and experimentation rather than focusing solely on numerical results. Finally, I am very grateful for the travel grant that enabled me to attend the workshop in person, meet members of the community, and experience the beautiful city of Amsterdam. Overall, MediaEval 2026 was an inspiring experience, and I hope to participate again in the future.

Kimia Rabishokr, Master’s Student in Data Science at ZHAW, Switzerland

MediaEval 2027

We are happy to announce that MediaEval 2027 will be held in Bucharest on Monday 13 September 2027 at the CAMPUS Research Institute, National University of Science and Technology Politehnica Bucharest, and will be co-located with CLEF 2027. We look forward to seeing you in Bucharest for MediaEval and CLEF. More information on the tasks offered in this edition will be available on the MediaEval 2027 webpage.

ACM SIGMM China Chapter

From building a local multimedia community to fostering international collaboration

Multimedia research advances when ideas, disciplines, and communities meet. Professional societies help create the connections that allow research to grow locally and contribute globally. Since its establishment in January 2009, the ACM SIGMM China Chapter has worked to connect researchers in China with the international SIGMM community, create sustained opportunities for exchange, and build platforms for collaboration across academia and industry.

At the heart of this work is a long-term ambition: to cultivate a connected and collaborative multimedia community in which researchers, students, engineers, and practitioners can share ideas, develop partnerships, and contribute to the direction of the field. Established during a period of rapid growth in multimedia research in China, the Chapter was first led by founding chair Yong Rui. It is currently led by Changsheng Xu (Chair), Shuqiang Jiang (Vice Chair), and Richang Hong (Secretary-General). Volunteers from universities, research institutes, and industry have helped sustain its activities and broaden its connections over the years.

The Chapter also works with academic organizations in China to strengthen the wider community. In collaboration with the CCF Multimedia Technical Committee, it has supported activities such as the Multimedia Technology Summit and Young Scholars Forum, creating opportunities for exchange across institutions and career stages. These activities reflect the Chapter’s role as a bridge between local research communities and the global SIGMM network.

From ICIMCS to ACM Multimedia Asia

The development of the Chapter can be clearly seen in its conference-hosting history.

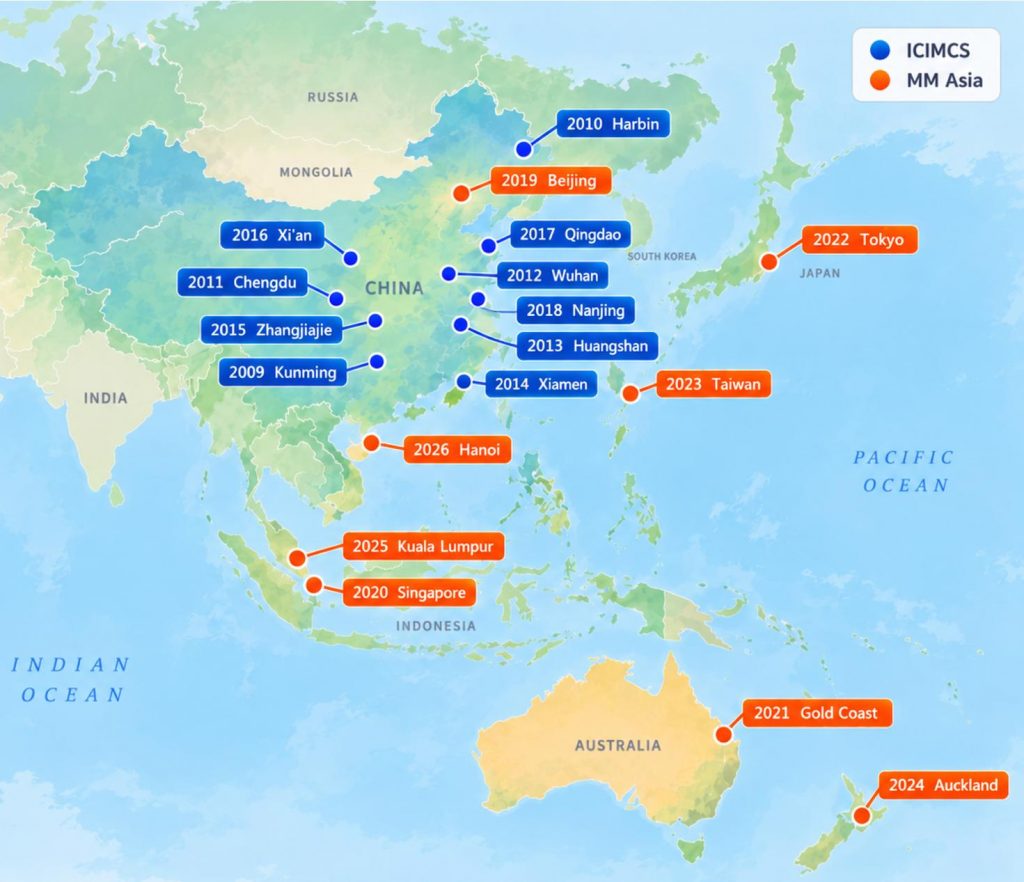
The International Conference on Internet Multimedia Computing and Service (ICIMCS) was the Chapter’s first major conference initiative. From 2009 to 2018, ICIMCS was held in Kunming, Harbin, Chengdu, Wuhan, Huangshan, Xiamen, Zhangjiajie, Xi’an, Qingdao, and Nanjing. The annual series provided an international forum for research in multimedia computing, analysis, systems, and applications. It also gave the Chapter extensive experience in international conference organization and helped establish a sustained network of researchers and volunteers.

Figure 1. The hosted-conference map of the ACM SIGMM Chian Chapter, from ICIMCS (2009–2018) in China to ACM Multimedia Asia (2019–2026) across the Asia-Pacific region.

By 2017, the Chapter saw an opportunity to extend this community-building work beyond a China-based series. Tao Mei and Changsheng Xu submitted a proposal on behalf of the Chapter to merge ICIMCS with the Pacific-Rim Conference on Multimedia (PCM) and establish ACM Multimedia Asia (MM Asia). The proposal joined ICIMCS’s established network in China with PCM’s long-standing Pacific-Rim community, creating the basis for a regional platform serving researchers and practitioners across Asia and the broader Asia-Pacific region.

SIGMM approved the proposal in October 2017, and MM Asia began in 2019 under the organization of the SIGMM China Chapter and SIGMM sponsorship. ICIMCS 2018 in Nanjing and PCM 2018 in Hefei marked the end of the two predecessor series, followed by the inaugural ACM Multimedia Asia in Beijing on December 16–18, 2019.

Since its launch, MM Asia has developed into a rotating Asia-Pacific conference series. After Beijing in 2019, it moved to Singapore in 2020, with that edition held virtually in March 2021, followed by Gold Coast in 2021, Tokyo in 2022, Taiwan in 2023, Auckland in 2024, and Kuala Lumpur in 2025. The 2026 edition is scheduled for Hanoi, Vietnam, in December.

This expansion represents more than a change in venue. It reflects the Chapter’s growing role in sustaining an international platform that connects multimedia communities across the region. By combining local volunteer effort, SIGMM sponsorship, and international collaboration, MM Asia carries forward the experience of ICIMCS and PCM while creating new opportunities for the wider community.

Looking Ahead: A Connected Multimedia Community

As multimedia research increasingly intersects with multimodal AI, generative media, and intelligent interactive systems, the need for exchange across disciplines and regions will continue to grow. The Chapter can build on its experience in conference organization and community engagement to support early-career researchers, encourage collaboration across institutions and industry, and strengthen links between researchers in China and the global SIGMM community. Researchers and practitioners can contribute by organizing seminars and workshops, participating in conference committees, and supporting activities for young scholars. The Chapter’s long-term ambition is to help ensure that the community it serves remains active, collaborative, and engaged in shaping the future of multimedia research.

CBMI 2026: Bringing Master’s Students into the Research Community

The 23rd International Conference on Content-Based Multimedia Indexing (CBMI 2026) was held in Toulouse, France, from October 21 to 23, 2026. CBMI brings researchers working across multimedia analysis, indexing, retrieval, and related areas. The 2026 edition offered three days of scientific presentations, special sessions, demonstrations, and opportunities for exchange across domains and generations.

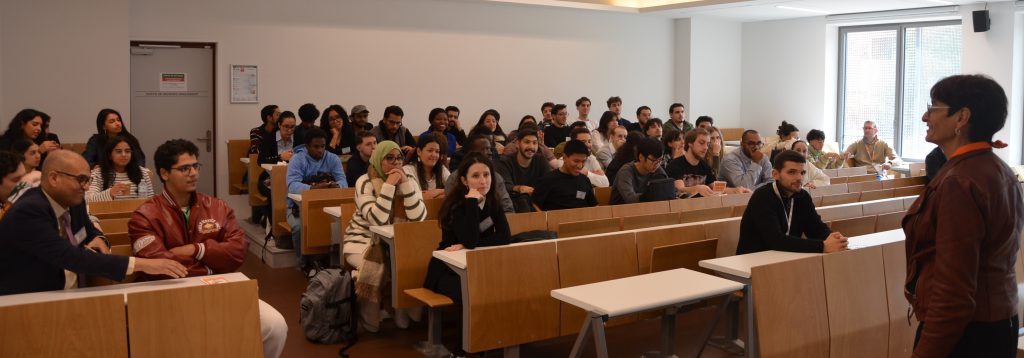
Alongside the scientific program, this year we wanted to create a stronger connection between the conference community and Master’s students who are beginning to consider their future academic and professional paths. With the support of ACM SIGMM and Région Occitanie, CBMI 2026 therefore organized a dedicated one-day program involving around 60 Master’s students. The objective was to give them direct exposure to an international research conference and, more importantly, to encourage them to see research as a possible future path.

Scientific highlights

The CBMI 2026 scientific program covered a broad range of topics at the intersection of multimedia, artificial intelligence, multimodal analysis, and information retrieval. Application domains ranged from agriculture, medicine, cultural heritage, human behavior to ethics.

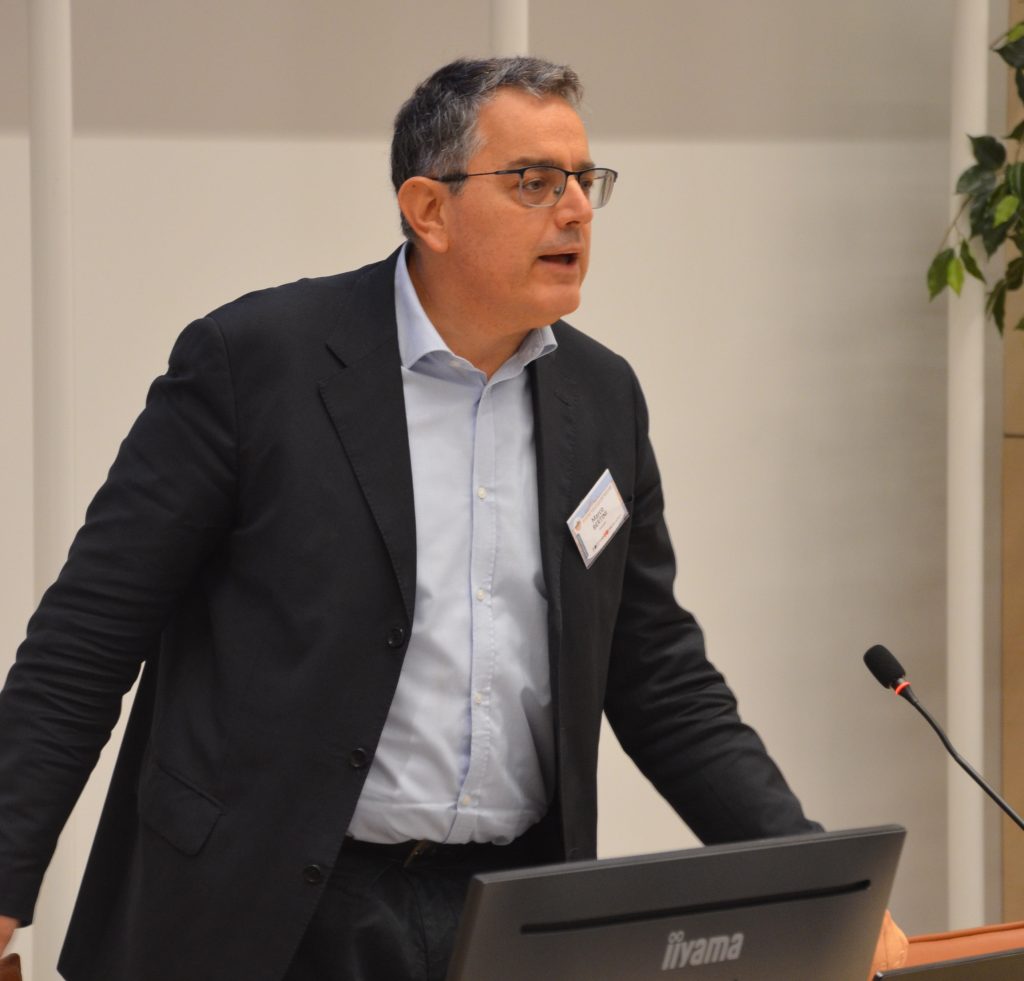
 A highlight of the conference was the keynote by Marco Bertini, Associate Professor at the University of Florence and member of the Media Integration and Communication Center (MICC). His talk explored image-text alignment, from composed image retrieval to image quality assessment, illustrating the growing role of vision-language models and multimodal representations in multimedia research.

The conference also devoted attention to diversity and the place of women in the research community. A Women in AI event, chaired by Florence Sèdes, Professor at the Université de Toulouse, provided an opportunity to reflect on the role and visibility of women in science and artificial intelligence and on the importance of continuing to improve diversity within our research communities.

Supporting researchers at the beginning of their careers was another important dimension of CBMI 2026. Organized for the first time, the Doctoral Symposium, chaired by Björn Thor Jonsson (Reykjavik University) and Julien Pinquier (Université de Toulouse) provided early-stage researchers with a dedicated setting in which to present their work, discuss their research with members of the CBMI community, and receive constructive feedback and mentoring. Three doctoral papers were selected for presentation.

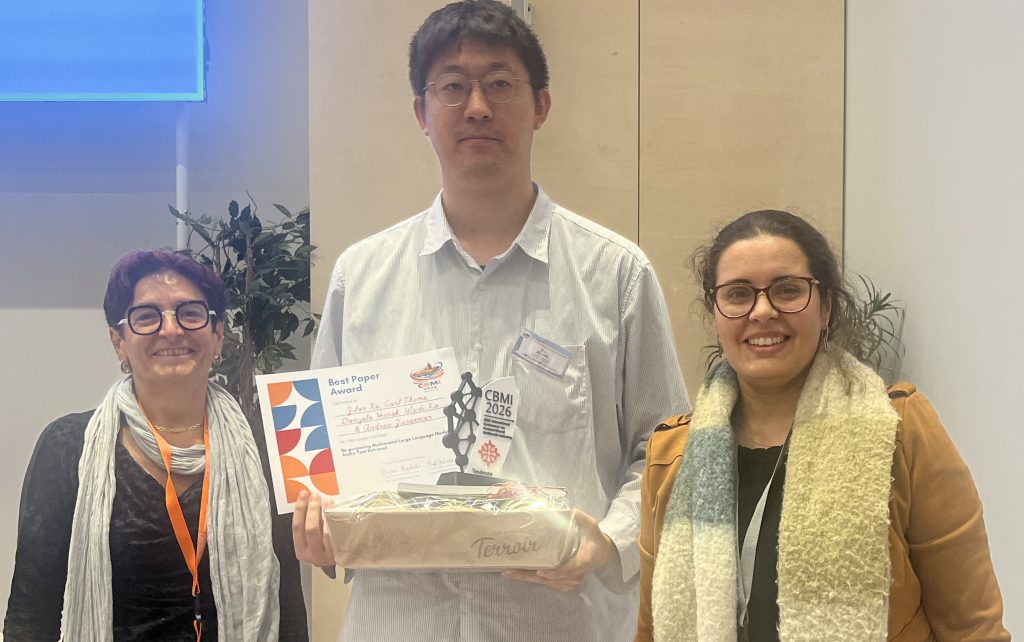
The conference also recognized outstanding contributions. The Best Paper Award was presented to “Re-purposing Multimodal Large Language Models for Audio-Text Retrieval” by Jilan Xu, Carl Thome, Danijela Horak, Weidi Xie, and Andrew Zisserman. The work investigates how multimodal large language models can be repurposed for audio-text retrieval.

The Best Demo Award went to “TimeLineXR: An Interactive Exploration of Time in Vision-Language Models” by Nidham Tekaya, Markus Passecker, and Matthias Zeppelzauer, highlighting the importance of interactive demonstrations as a means of exploring and communicating emerging multimedia research.

The Master’s students joined CBMI for one full day designed to expose them to several complementary aspects of research.

During the morning, they attended the keynote talk and selected conference sessions. Rather than learning about research only through university courses, the students could see researchers presenting recent results, discussing open questions, and exchanging ideas in an international scientific setting.

This immersion was an important part of the initiative. Before asking the students to develop research ideas of their own, we wanted them to experience how research questions are presented and discussed by an active scientific community.

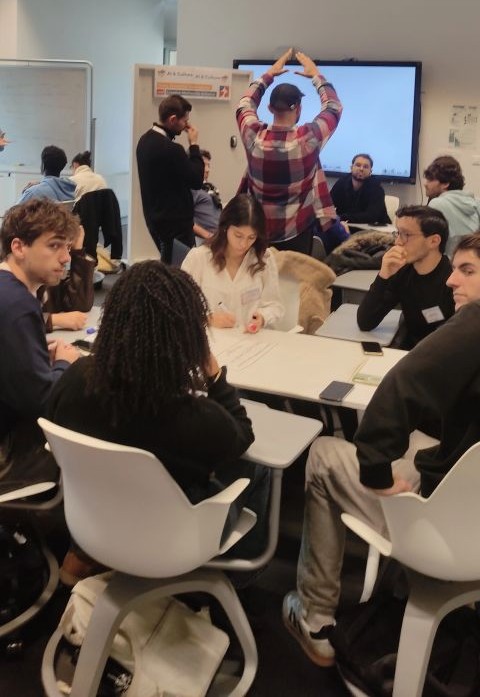
The afternoon then shifted the students from observers to participants through an Ideation Workshop on the theme Culture and AI.

The Culture and AI Ideation Workshop, chaired by Josiane Mothe, Professor at Université de Toulouse, was designed to stimulate the students’ curiosity about research and encourage them to move from using or observing AI technologies to identifying questions that could themselves become subjects of investigation. The workshop began with a talk by Alan Smeaton, Professor at Dublin City University, who presented concrete examples of the use of artificial intelligence in relation to culture. He chose to exemplify the use of AI in the cinema industry. These examples provided starting points for thinking about the possibilities offered by AI, but also about the technical, cultural, and societal questions that emerge when artificial intelligence interacts with cultural content. Two members of the tiers-lieu and incubator of the Université de Toulouse, then introduced the principles of ideation and the collaborative approach that the students would use during the afternoon.

Working in small groups in a hackathon-like format, the students developed ideas around Culture and AI. Sixfacilitators helped the groups refine their ideas, question their initial assumptions, and develop their proposals.

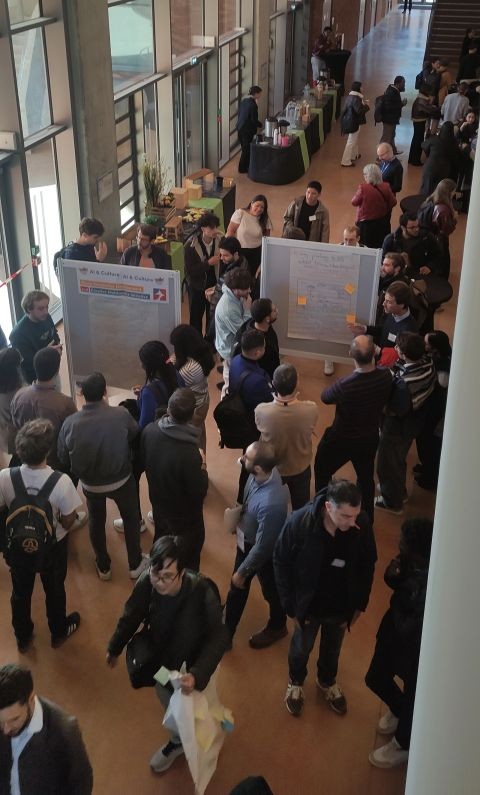
An important element of the activity was that it did not end with the workshop itself. The students subsequently presented their ideas during the CBMI poster session, alongside conference participants. This gave them the opportunity not only to formulate an idea but also to explain it, discuss it with researchers, answer questions, and receive feedback. An award was given to the best idea. It was given to “Art You Can Hear”, An AI-powered headphone that helps visually impaired visitors experience artwork through sound and touch. It combines spatial audio, haptic feedback, and a proximity sensor, by Usman Ashfaq, Syed Zulqarnain Haider, Hafiz Masood Ur Rehman, Aleksandra Ershova, Mohamad Khriess, Hancheng Chen. By the end of the day, the students were no longer simply visitors to the conference: they had themselves contributed to its discussions.

Research beyond formal presentations

The student initiative was also intended to highlight that a research conference is more than a succession of technical presentations. It is a space where ideas develop through formal talks, collaborative work, demonstrations, social events, and informal discussions, and where participants can engage with perspectives beyond their own immediate research context.

In this spirit, CBMI 2026 placed particular emphasis on international, intergenerational and interdisciplinary exchange among Master’s students, PhD students, and established researchers. Bringing together participants from 22 countries at different career stages and from different domains created opportunities to share experiences, approaches, and viewpoints, while opening the way to new ideas, connections, and potential collaborations.

CBMI 2026 also included the Music Meets Science event, which brought together the worlds of multimedia research and musical performance. The Occitan vocal trio Diluvienne performed during the event, offering another perspective on the relationship between technology and creative practice, encouraging participants to consider multimedia not simply as data to be processed, but also as content that is created, interpreted, and experienced by people.

CBMI 2027 will be hosted in Thessaloniki, Greece, from October 19 to 21.

Photo by Hugo Boisaubert, Yohann Chasseray, Josiane Mothe. The latest is AI generated from 2 real photos

MPEG Column: 155th MPEG Meeting

The 155th MPEG meeting took place in Geneva, Switzerland, from July 13 to 17, 2026. The official MPEG press release can be found here. This report highlights key outcomes from the meeting, with a focus on research directions relevant to the ACM SIGMM community:

  • Gaussian Splat Coding Use Cases and Current Status
  • Call for Proposals on Media Authenticity and Provenance Indication
  • Joint Call for Proposals on video compression with capability beyond VVC
  • Joint ITU-T SG 21 and ISO/IEC JTC 1/SC 29 Workshop on Media Streaming Services
  • Exploration on Systems technologies for AI-based media standards (SyfAI)

Gaussian Splat Coding Use Cases and Current Status

The previous MPEG column [MPEG154] introduced MPEG’s Gaussian Splat Coding (GSC) exploration, its two tracks (I-3DGS and A-3DGS), and a first set of 27 draft use cases. At the 155th meeting, WG 2 (Technical Requirements) approved an updated document (WG 2 N531) that drops the draft qualifier and adds two use cases.

The additions matter less for their number than their nature: both concern storage and delivery rather than compression. Use case 28 stores a static splat asset in a single file together with a cover image, thumbnail, and audio annotation, so that a capable receiver renders it interactively while a legacy receiver displays the cover image, with no modification of the file. Use case 29 is the temporal counterpart, delivering a dynamic splat track by HTTP adaptive streaming alongside synchronized audio, a pre-rendered video track serving as preview and fallback, and timed text, with representations offered per bitrate, level of detail, spherical harmonics subset, or attribute subset. The application-oriented use cases are unchanged, although the derived requirements are being refactored, notably by separating attribute subset scalability from random access.

GSC remains an exploration activity, but a busy one: 83 input contributions and nine Joint Exploration Experiments re-conducted across WG 2, WG 4 (Video Coding), WG 5 (Joint Video Experts Team, JVET), and WG 7 (3D Graphics and Haptics), with WG 1 (JPEG) now engaged on quality metrics and WG 4 examining Neural Network Coding (NNC) as a compression tool. On the fast track, GS4 (Video-based Point Cloud Compression, V-PCC, Amd. 1) and GS5 (Geometry-based Point Cloud Compression, G-PCC, Amd. 1) progress on reference software and conformance, while the JVET codec track carries five competing proposals. The Call for Proposals (CfP) still has no date, and I-3DGS planning is more mature than A-3DGS. The clearest message from the meeting is that single-frame compression is essentially solved and that the difficulty and the expected gain now lie in dynamic content.

Research aspects: Temporal coding is no longer one open question among many, but the central one, covering inter-prediction for anisotropic primitives, deformation models, and primitive correspondence across frames. Quality assessment remains unresolved: current test conditions score rendered views with peak signal-to-noise ratio (PSNR), structural similarity (SSIM), and learned perceptual image patch similarity (LPIPS) along a pose trace, a fragile proxy for artifacts such as floaters and popping; the involvement of JPEG makes this a good moment to contribute. Use case 29 gives the streaming question a concrete form: when quality varies along several orthogonal axes at once, what is the right abstraction for a representation, and what should an adaptation algorithm optimize?

Call for Proposals on Media Authenticity and Provenance Indication

At the 155th meeting, WG 2 approved a CfP on media authenticity and provenance indication with the MPEG Systems technologies (WG 2 N535), following an exploration phase in WG 3 (Systems) that produced requirements, a gap analysis, and several technical proposals (WG 3 N1842, attached to the call). The scope is the system layer: carriage and signaling of metadata that allows a receiver to verify that a media asset comes from a trusted producer and to convey provenance information, rather than the definition of a provenance language itself.

Three interfaces are addressed, namely (i) elementary streams and non-timed items, (ii) the file format level (ISO Base Media File Format (ISOBMFF) and Common Media Application Format (CMAF)), and (iii) packaged delivery (Dynamic Adaptive Streaming over HTTP (DASH), CMAF, MPEG Media Transport (MMT), and MPEG-2 Transport Stream (MPEG-2 TS)). The use cases span deepfakes and manipulated news media, forgery in insurance claims, surveillance and investigations, labeling of AI-generated content, and legitimate modifications such as editing, transcoding, ad insertion, and archival preservation. Detecting whether an asset is fake without embedded data is explicitly out of scope.

A response may be a complete solution or a single tool addressing one or more requirements, and is evaluated on requirement coverage, computational complexity, the bandwidth needed to convey the authenticity information, compatibility and backward compatibility with existing MPEG standards, and extensibility, with self-evaluation tables provided in the annexes. Proposals are submitted as input contributions to the 157th meeting in Brisbane, Australia, by January 13, 2027. Review at that meeting will produce one or more working drafts or new work item proposals, and the preliminary development plan targets Committee Draft (CD) or Committee Draft Amendment (CDAM) at the 158th meeting, Draft International Standard (DIS) or Draft Amendment (DAM) at the 159th, and Final Draft International Standard (FDIS) or Final Draft Amendment (FDAM) in early 2028.

Research aspects: The requirements make this more interesting than a signing exercise. A conventional signature breaks on any bit change, yet the call demands that verification survive transcoding, dropped scalability layers, representation switching, splicing, late binding, and loss of frames or audio, and that the unmodified remainder of a presentation stay verifiable after an authorized edit. Designing verification structures with that granularity and quantifying their overhead per segment against the added latency in live scenarios is an open problem at the intersection of cryptography and streaming systems. A second question is joint verification: establishing that a given audio track was the one the producer intended to accompany a given video, including their synchronization, cannot be achieved by signing each file separately. Finally, interoperability with provenance schemes defined elsewhere, and the question of what a receiver should do with a verification result, leave room for work on usable trust signaling.

Joint Call for Proposals on Video Compression with Capability Beyond VVC

The draft of this call was described in the previous MPEG column [MPEG154], and JVET has now issued the final version (JVET-AQ2021 [JVET-AQ2021]), approved at its 43rd meeting in Geneva in July 2026. The target is video coding technology that significantly exceeds Versatile Video Coding (VVC) in compression, implementability, applicability across content types, and features such as latency, robustness, and scalability, benchmarked against the VVC Main 10 profile. Four test cases are defined: one for improved compression without runtime limits, and three in which the aggregate encoder run time is constrained to 5x, 1x, and 0.2x that of the VVC Test Model (VTM) anchor. All are evaluated over seven categories covering (i) standard dynamic range (SDR) random access at ultra-high definition (UHD) and (ii) at high definition (HD), (iii) SDR low delay HD, (iv) high dynamic range (HDR) with perceptual quantizer (PQ) and (v) with hybrid log-gamma (HLG) transfer functions, (vi) gaming, and (vii) user-generated content. A separate track invites technology offering additional functionality, together with proposals on how its benefit should be assessed.

Formal subjective testing uses degradation category rating, with objective results reported as PSNR, multiscale SSIM (MS-SSIM), and, for PQ content, weighted PSNR. The schedule is tight: anchors have been available since May 2026, registration runs from August 1 to September 1, 2026, and the main package of bitstreams, reconstructed sequences, and binaries must reach the test coordinator on physical media by October 26, 2026. Subjective assessment then runs until late December, blind cross-checking by other proponents is mandatory, and proposals are evaluated at the 45th JVET meeting in January 2027, with an initial test model selected during 2027 and the standard targeted for October 2029. Participation is not free: up to EUR 20k per test case is charged to cover the hiring of test subjects.

Research aspects: Two design choices in the call are worth attention. First, a supplemental set of sequences is disclosed to proponents only after the decoder binaries have been submitted, and results on it are due six weeks later, which turns the call into a held-out generalization test. Read together with the ban on training on test sequences and the obligation to disclose training material, this makes out-of-domain behavior of learned coding tools measurable at scale, and reporting it well is a contribution in itself. Second, run time is aggregated as the sum over threads, which measures total compute rather than latency and therefore reads very differently for a massively parallel or GPU-resident design than for a sequential one. How to characterize the rate, distortion, and complexity trade-off fairly across such architectures, and how to value functionality such as scalability or error resilience against a plain bitrate gain, are open questions the call poses rather than answers.

Joint ITU-T SG 21 and ISO/IEC JTC 1/SC 29 Workshop on Media Streaming Services

On July 14, 2026, ITU-T SG 21 and MPEG Systems held a joint half-day workshop in Geneva, collocated with their meetings, on “Media Streaming Service, What’s next” (call for presentations, program). The premise was that after the transitions from analog to digital, enabled by MPEG-2 Systems, and from broadcast to over the top (OTT), enabled by MPEG-DASH, integrated networks, edge computing, and AI are driving another shift, and that both bodies wanted industry views before committing to new work. On challenges, Netflix spoke on the shortcomings and evolution of ISOBMFF, Bitmovin on where streaming trends meet the container, ETRI on future streaming services, and Huawei on ultra-low latency communication and streaming. On opportunities, 5G-MAG addressed standards and open source, DVB heterogeneous networks, and 3GPP SA4 delivery beyond OTT. The closing session was an open mic with questions and answers from both speakers and the audience.

The wrap-up set the existing systems standards, namely MPEG-2 TS, ISOBMFF, DASH, and CMAF as well as the volumetric, scene, and augmented reality (AR) formats, plus ongoing work on authenticity, SyfAI (see below), common metadata, and Gaussian splats, against what industry actually asked for: low latency, low overhead, AI-driven media, and open source software. The resulting agenda is an exploration of a better or new container format, an analysis of overhead, processing-friendly metadata, including JSON and ontology issues, WebCodecs integration, and ingest. Just as notable are the conclusions about process: more open access and industry involvement, faster turnaround, possibly a new home or outlet for this work, and software with interoperability testing from day one rather than reference software at the end. Three ad hoc groups were set up: (i) on MP4, DASH, and file formats, reviewing ISOBMFF against emerging transports and the delivery of AI input and output data; (ii) on vision, analyzing bottlenecks and requirements beyond ISOBMFF; and (iii) on working methods.

Research aspects: Two of these items are directly researchable. Container overhead is asserted more often than measured, and as segments shrink toward frame level for low latency, the ratio of container to media bytes grows; a careful comparison across ISOBMFF, CMAF, and object-based transports at equal latency would inform the exploration rather than follow it. Media over QUIC (MOQ) is the bigger change, since it replaces the segment with the object as the unit of delivery and pulls streaming and real-time communication into a single design space, which reopens rate adaptation, interaction with congestion control, caching, and relay behavior, and the question of what a container still contributes when the transport itself frames media. Carrying AI input and output data alongside media, finally, links this work to coding for machines and to semantic streaming.

Exploration on Systems Technologies for AI-based Media Standards (SyfAI)

Several MPEG coding standards now put a neural network inside the decoder, among them video and feature coding for machines, AI-based point cloud coding, and neural network coding. The previous MPEG column [MPEG154] described that coding side through the MPEG-AI vision document. SyfAI, an MPEG Systems exploration started at the 153rd MPEG meeting, asks the complementary and much less glamorous question: what does the surrounding infrastructure have to do so that such content can actually be stored, delivered, and played back interoperably? The underlying shift is that a media file has traditionally been self-contained, meaning that a conforming decoder and the bitstream are sufficient. Once the decoder depends on a trained model that may be selected, delivered, or updated separately, that assumption no longer holds, and the system layer has to say how a player learns which model it needs, how that model reaches it, and how both sides can be sure they are using the same one. Work so far has advanced on the most concrete piece, namely storing video coding for machines content in the MPEG file format, while proposals for carrying compressed neural networks were sent back for clearer use cases. The more interesting development is a new thread on an AI update framework, opened jointly with WG 7, which collects five topics: (i) a format for AI parameter data, (ii) a manifest for updating parameters, (iii) a repository to serve them, (iv) integrity checking, and (v) bit exactness together with conformance.

Research aspects: Each of those topics is a research problem in its own right. Distributing and updating models alongside media turns into a delivery question that looks familiar but has not been studied: when to fetch an update, how to cache and version models, what a manifest must express about capability and compatibility, and how to treat weights as a second class of asset next to the media. Conformance is harder, because a standard normally guarantees that every decoder produces identical output, whereas neural inference varies with library and hardware, so deciding what conformance means and how to test it remains open and extends the reproducibility concerns already visible in MPEG-AI. A repository of updatable weights is also an attack surface, which is why this work sits naturally beside the media authenticity call discussed above: signing and verifying a model raises the same questions one level down from signing content. And because the choice of where a model lives affects how quickly playback can start and how smoothly a player can switch, the apparently dry container questions have measurable consequences for the quality of experience (QoE).

Concluding Remarks

Taken together, the five items show MPEG engaging early with technologies whose momentum comes from outside the committee. With Gaussian splatting, it is compressing a representation that already has a renderer and a user base, which is a better starting point than earlier attempts at three-dimensional video had, even if wider adoption will depend on capture and display ecosystems as much as on coding efficiency. The authenticity call is scoped pragmatically at establishing origin, which is achievable in the near term and provides the system-level plumbing that regulation and industry are asking for. The call for video coding beyond VVC visibly reflects deployment experience, with runtime-constrained test cases treating practicality as a first-class criterion, while questions of licensing and market uptake sit largely outside MPEG itself. In systems, the joint workshop and the new ad hoc groups show a willingness to re-examine long-standing assumptions as transports such as MOQ emerge, and SyfAI stakes out the system-level questions of the AI era before they become urgent. For our community, the result is an unusually rich set of open problems in evaluation and methodology.

The 156th MPEG meeting will be held in Hangzhou, China, from October 19 to 23, 2026. Click here for more information about MPEG meetings and ongoing developments.

References

  • [MPEG154] C. Timmerer. 2026. MPEG Column: 154th MPEG Meeting. SIGMultimedia Rec. 18, 2, Article 8 (April 2026).
  • [JVET-AQ2021] J.-R. Ohm, M. Wien, F. Bossen. 2026. Joint Call for Proposals on video compression with capability beyond VVC, JVET-AQ2021 (July 2026).

The 4th Edition of Spring School on Social XR, ACM Seasonal School organised by CWI

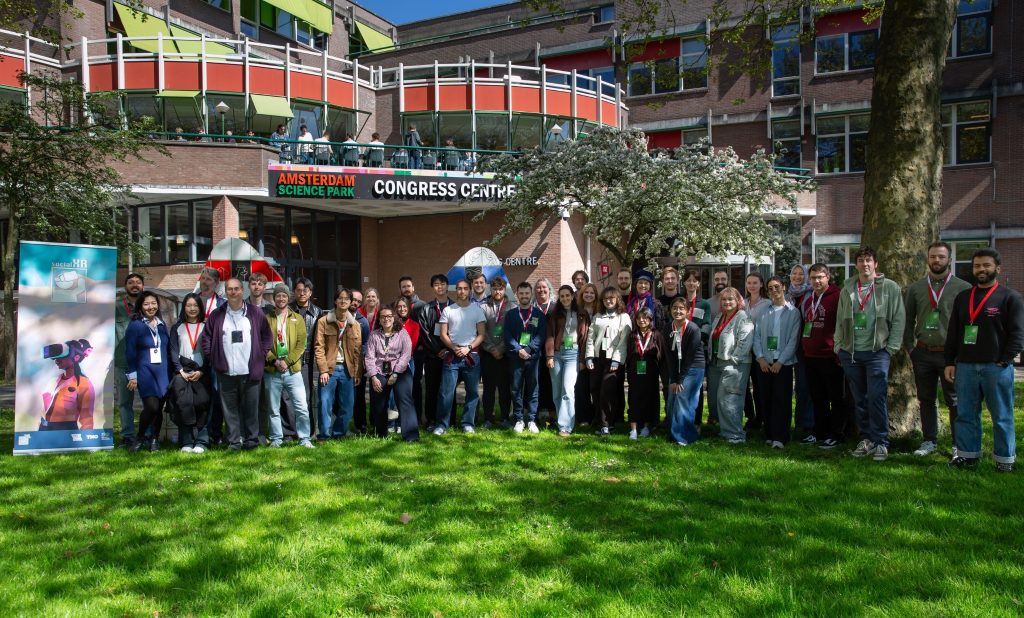
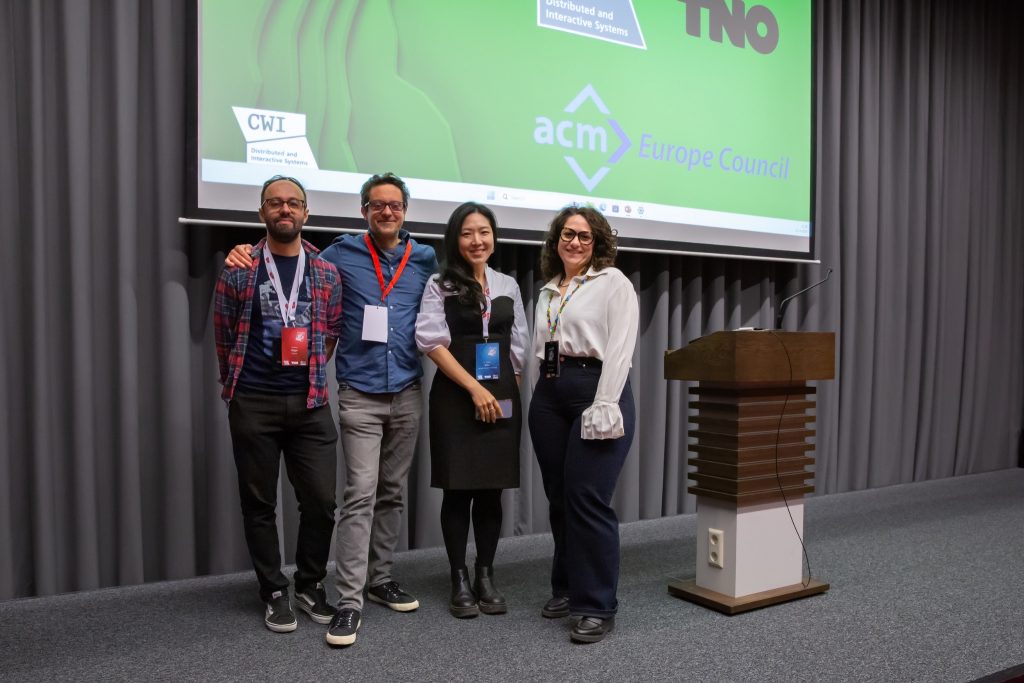
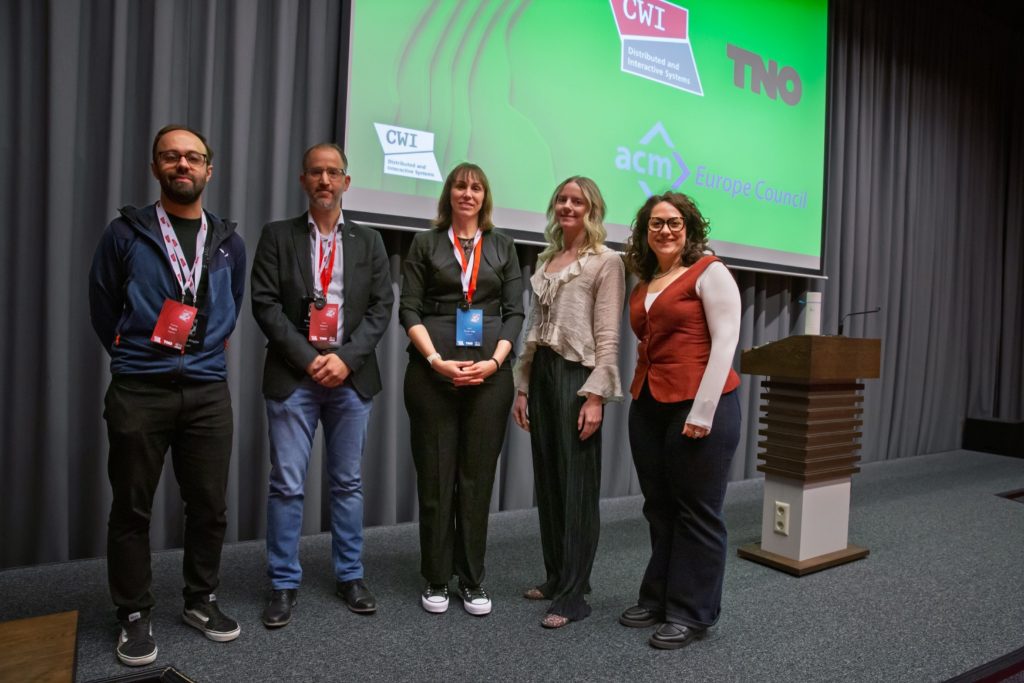
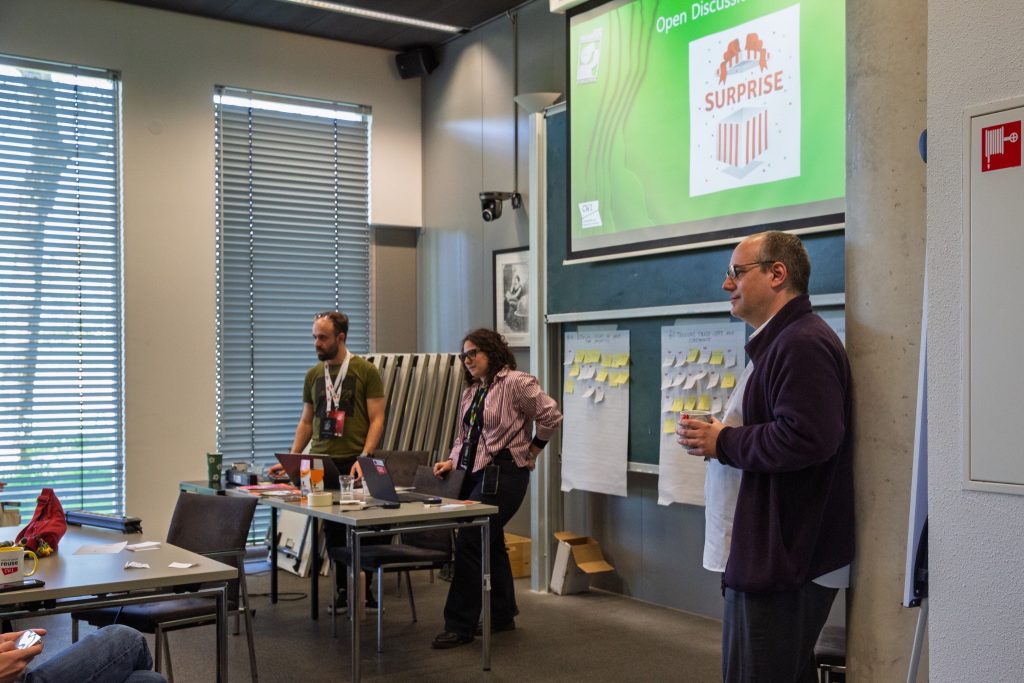
The 4th edition of the Spring School on Social XR organised by Distributed and Interactive Systems group (DIS) at CWI in Amsterdam took place from 20 to 23 April 2026 and attracted 31 students from various disciplines, including technology, the social sciences, and the humanities. The event was organized by Silvia Rossi, Irene Viola, Thomas Röggla, and Pablo Cesar from CWI, and Omar Niamut from TNO. Also this year, it was co-sponsored by ACM SIGMM, thanks to the founding for Special initiatives, and it has been recognised also as an ACM Europe Council Seasonal School.

Students and organisers of the 4th Spring School on Social XR, 2026

Across 11 lectures (4 of them open to public) and 3 hands‑on workshops led by 12 international instructors, participants had the possibility to have cross-domain interactions on Social XR. The program covered a broad range of topics at the intersection of immersive technology, human behavior and system design: trust and safety in social virtual environments, ethical and human-centered approaches to XR design, affective computing and mental health applications, socially intelligent and AI-driven virtual humans, haptics and tactile interaction, volumetric video technologies, mobility research in XR, and the future of communications in education and research. Together, they provided a multidisciplinary perspective that went beyond knowledge transfer: bringing together early-career researchers from diverse backgrounds to create the groundwork for new collaborations and a growing community around Social XR.

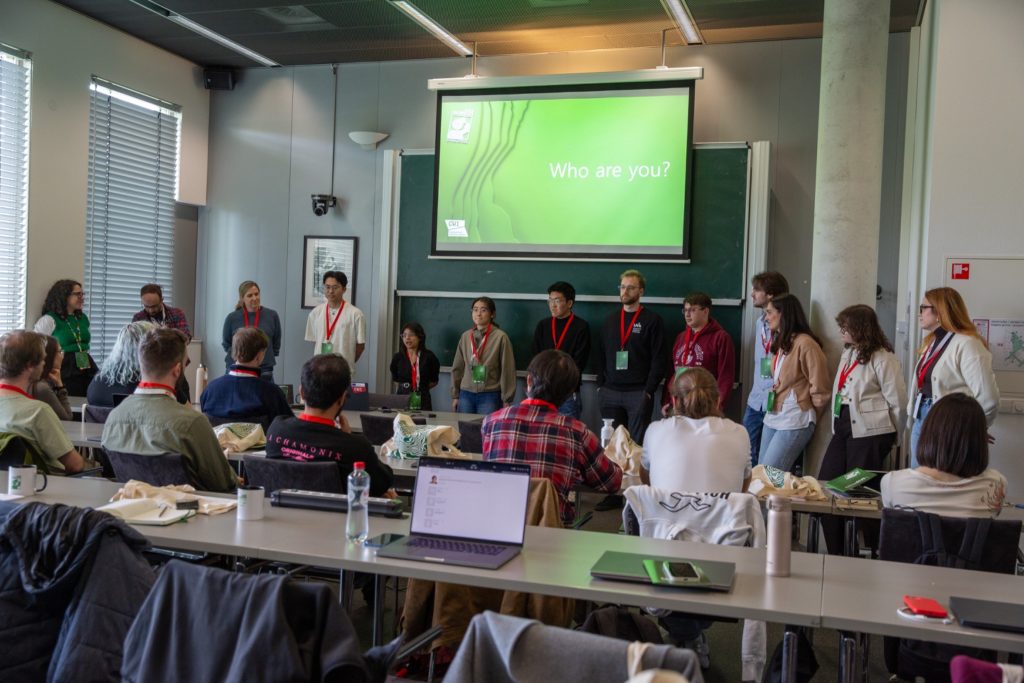
Students presenting themself during first day.

List of talks and workshops:

  • “The Future of Communications and Interaction” by Gül Akcaova and Mark Cole— workshop
  • “Towards Ethical, Human-Centered XR Experiences: From Theory to Practice” by Katrien de Moor — workshop
  • “Volumetric Video Technologies for Real-Time Immersive Communication” by Guillaume Gautier and Alexandre Mercat — workshop 
  • “Studying Mobility in eXtended Reality” by Yan Feng
  • “A Brief History of Virtual Humans” by Marco Gillies
  • “Affective Social XR and Intercorporeal Regulation: A Multi-Method Approach to Supporting Mental Health and Well-being” by Alexandra Kitson
  • “Designing Inclusive XR: Experience from Day-to-Day Industrial Research” by Marta Orduna
  • “Socially Intelligent Digital Humans” by Chirag Raman
  • “Tactile Extended Reality: The Role of Haptics in Immersive Interactive Applications” by Maria Torres Vega
  • “Trust and Safety in Social XR” by D. Yvette Wohn
  • “AI-driven Animation for Virtual Humans” by Zerrin Yumak

JPEG Column: 111th JPEG Meeting

JPEG DNA reaches Draft International Standard stage at the 111th JPEG meeting

The 111th JPEG meeting was held in virtual mode from 13 to 17 April 2026.

This meeting was marked by several major achievements. JPEG DNA, the first image format that uses a quaternary representation suitable for synthesis into nucleotide sequences to be used for storage on DNA support, reached the Draft International Standard (DIS) stage. This was ensured after a successful wet-lab experiment, including DNA synthesis/sequencing that allowed a test of reliability in real conditions.

Furthermore, the DIS stage was also reached for JPEG XE, the first International standard for coding of visual events; JPEG Pleno Light Field Quality Assessment, which establishes a model for quality evaluation of encoded light fields; JPEG Trust Media Asset Watermarking, which provides watermarking support to media asset authenticity; and JPEG Trust reference software, which will provide a valuable tool for the development of applications using this family of standards. Furthermore, JPEG Pleno Light Field coding, 2nd edition, reached the Final Draft International Stage.

The following sections summarize the main highlights of the 111th JPEG meeting.

  • JPEG DNA reaches DIS stage.
  • JPEG XE reaches DIS stage.
  • JPEG Trust part 4 – Reference Software – reaches DIS stage.
  • JPEG Pleno Light Field Quality Assessment reaches DIS.
  • JPEG XS Part 2 prepares a new amendment to define a new raw Bayer profile.
  • JPEG RF explores methodologies for quality evaluation of Gaussian Splatting coding distortions.
  • JPEG AI explores machine-oriented applications in the compressed domain.

JPEG DNA

At its 111th meeting, the JPEG Committee reached a major milestone with JPEG DNA Part 1 (ISO/IEC 25508-1) advancing to the Draft International Standard (DIS) stage. This achievement marks the culmination of a multi-year standardization effort, beginning with the Final Call for Proposals at the 99th JPEG meeting and proceeding through the creation of the Verification Model at the 102nd meeting, the first Working Draft at the 103rd meeting, the Committee Draft, and the study DIS text produced at the 108th meeting. With DIS now reached, the core technical specification for the efficient coding of images into quaternary representations suitable for archival on DNA synthetic polymers is frozen for the first edition of the standard. The JPEG Committee expects publication of Part 1 an International Standard before the end of 2026.

The DIS milestone was accompanied by the successful completion of wet-lab experiments initiated at the 109th JPEG meeting and whose synthesis and sequencing phases were carried out between the 110th and 111th meetings. The sequenced results from the independent parties have now been delivered to the JPEG Committee and analyzed. The experiments confirmed that the information recorded in the DNA solution was successfully extracted and that the corresponding compressed images were correctly decoded, in accordance with the end-to-end workflow defined in the specification, including biochemical constraints, the recovery mechanism used to cope with the noise introduced by the synthesis and sequencing processes, and the procedures for reading the encoded image information back from the synthesized oligonucleotides. These results provide concrete validation that the current specification of JPEG DNA satisfies the conditions required for applications relying on the current state of the art in DNA synthesis and sequencing and represents the first end-to-end demonstration of the standard on real biological media.

JPEG XE

The joint effort between ITU-T SG21 and ISO/IEC JTC1/SC29/WG1 on JPEG XE is ongoing, with JPEG XE Part 1 ready to become the first of a series of standards for coding of visual events. During its 111th meeting, the JPEG Committee made substantial progress on the ongoing development of the additional JPEG XE Parts 2, 3, 4, and 5. Technical discussions advanced the work on Part 2, which will define Profiles and Levels, as well as a normative buffer model to ensure safe and interoperable decoder operation across implementations. Further enhancements were made to the code of the open source reference software, which will be published under Part 3 as a proof‑of‑concept and conformance testing implementation. Preparatory work commenced for Part 4, which will establish the structure and scope of formal conformance testing and will become the focus during the coming months. Finally, consensus was reached about Part 5, where the JPEG Committee converged on an ISOBMFF‑based file format design supporting efficient storage, streaming, and precise event timestamping. The JPEG Committee, mandated for the joint effort between ISO/IEC/JTC1/SG29 and ITU-T SG21, remains committed to the development of a comprehensive and industry-aligned standard that meets the growing demand for event-based vision technologies. This collaborative approach underscores a shared vision for a unified, international standard to accelerate innovation and interoperability in this emerging field. The JPEG XE joint AHG (ITU-T SG21 and ISO/IEC JTC1 SC29 WG1) was reestablished to continue the JPEG XE standards development. If you are interested, please consider joining this public joint AHG.

JPEG Trust

There have been major advances in all parts of JPEG Trust. Recently, a 2nd edition of JPEG Trust Part 1 – Core Foundation, was published to accommodate assertions for attributions (based on The Dublin Core metadata element set, ISO 15836-1:2017) and declarations of rights (based on the W3C ODRL Information Model 2.2). JPEG Trust Part 2 – Trust profiles and reports extends the framework specified in Part 1 with extended functionalities for Trust Profiles and Trust Reports; it has now entered the DIS stage. JPEG Trust Part 3 – Media asset watermarking, incorporating specific tools and associated assessment methodologies for usage scenarios that rely on invisible watermarking of media assets, has now been released for DIS balloting. The DIS for JPEG Trust Part 4 – Reference Software was also released for balloting; this Part will be extended in the future with additional implementations and test datasets.

A first JPEG Trust Summit is planned on 12-13 November 2026 in London. More information on upcoming events related to JPEG Trust can be found here.

JPEG Pleno

The JPEG Pleno Light Field activity analyzed the DoCR for the Final Draft International Standard (FDIS) of the 2nd edition of ISO/IEC 21794-2 (“Plenoptic image coding system (JPEG Pleno) Part 2: Light field coding”). This 2nd edition integrates AMD1 of ISO/IEC 21794-2 (“Profiles and levels for JPEG Pleno Light Field Coding”) and includes the specification of a third coding mode entitled “Slanted 4D Transform Mode” and its associated profile. It is expected that at the 112th JPEG meeting this new edition will become an International Standard (IS).

The JPEG committee made significant progress in JPEG Pleno Light Field Quality Assessment (Part 7) activities. Key developments were achieved, including the review and finalization of the DIS text for ISO/IEC 21794-7, which was approved for registration at this meeting. Core experiments on light field quality assessment were presented and discussed, contributing to the validation of subjective testing frameworks and the further development of objective metrics, including improvements to learning-based approaches.

JPEG XS

JPEG XS, the image and video compression format for transmitting visually lossless, high-quality pictures with minimal latency and low resource consumption, is currently in a mature state. Two amendments, JPEG XS Part 1 and Part 2, are expected to be published in July of 2026. JPEG XS AMD1 provides a new syntax to allow embedding of user-defined metadata at the slice-level in addition to the frame-level that was already possible. JPEG XS Part 2 amendment AMD1 provides additional levels and sublevels, as well as a new frame buffer level, to better support proxy-stream extraction use cases. At its 111th meeting, the JPEG Committee prepared another amendment (AMD2) for JPEG XS Part 2 to define a new raw Bayer profile, called CMainBayer, that supports reducing the implementation complexity compared to the MainBayer profile. It will be an inclusive profile, meaning that existing HighBayer and MainBayer implementations will be capable of decoding the newly proposed CMainBayer profile. A core experiment was issued to verify the proposed parameters and the impact on the coding performance and the potential resource savings. The plan is to issue the DAMD2 text at the next JPEG meeting in July 2026.

JPEG RF

At its 111th meeting, the JPEG committee continued its active exploration of technologies for radiance field representations. Significant progress was achieved, particularly in the areas of quality assessment and visualization methods for radiance fields, where an exploration study was presented and discussed, contributing to a deeper understanding of how radiance field content should be rendered and evaluated in subjective experiments. These discussions support the development of reliable and practical assessment frameworks in preparation for a future Call for Proposals. JPEG also initiated a new exploration focusing on the identification of suitable objective quality metrics and subjectively annotated datasets, as well as the evaluation of metrics’ performance for radiance field content. This work builds on prior efforts covering coding methods, subjective assessment protocols, and trajectory design, and aims to support the development of standardized evaluation methodologies.

In parallel, outreach activities continued to expand community engagement and support the preparation of dissemination materials, while work progresses toward revising the JPEG RF Common Test Conditions. The outcome of these efforts will guide future standardization in radiance field coding.

JPEG AI

At its 111th meeting, the JPEG Committee continued advancing JPEG AI. The Committee reviewed progress in key JPEG AI Core Experiments, including energy-consumption analysis, and bit-exact reconstruction, with results showing promising implementation trade-offs across CPU, GPU, and FPGA platforms. The FPGA implementation was identified as the most energy-efficient, while GPU execution provided the lowest latency. JPEG also reported progress on compressed-domain machine analysis, where JPEG AI latent representations enabled earth-observation segmentation with nearly ten times fewer model parameters. Further work will continue through new Core Experiments on energy consumption, bit-exact reconstruction, and objective and subjective evaluation. This activity reinforces JPEG AI’s role as the first International Standard for end-to-end learning-based image coding and as a technology relevant to both human visualization and machine-oriented applications.

Final Quote

“At the 111th meeting, five JPEG standardization projects reached DIS stage, a testimony to the commitment of its experts who work tirelessly towards the development of efficient standardized solutions that guarantee interoperability between emerging imaging products and services,” said Prof. Touradj Ebrahimi, the Convenor of the JPEG Committee.