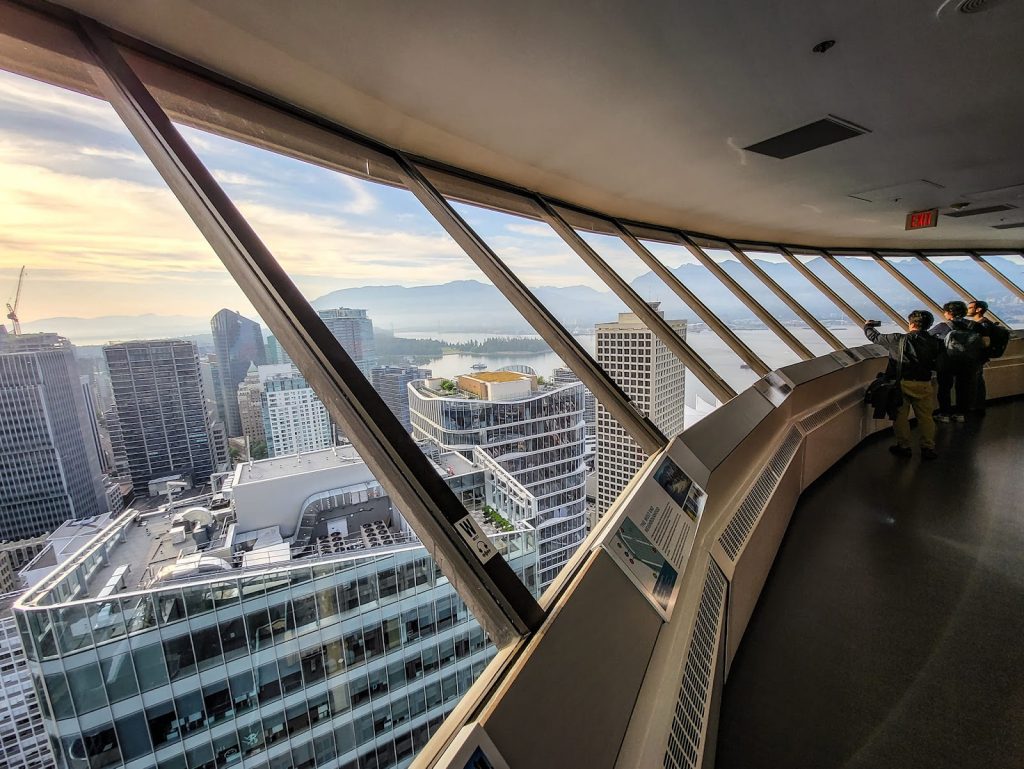
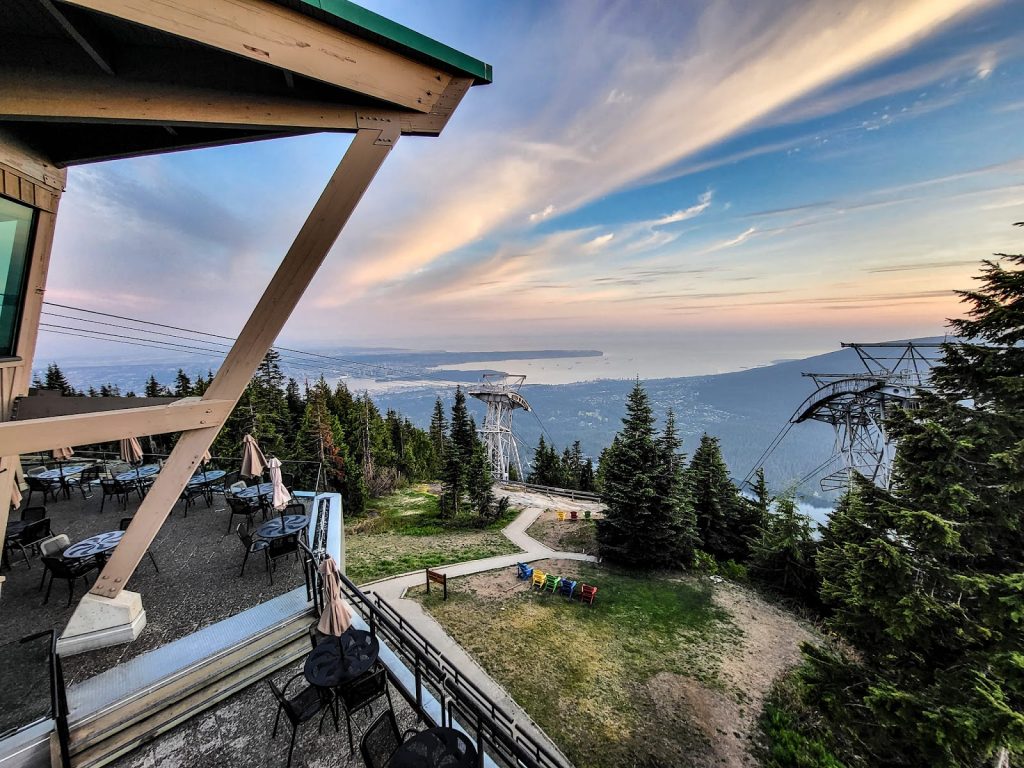
The 14th ACM Multimedia Systems Conference (with the associated workshops: NOSSDAV 2023, MMVE 2023, and the first edition of GMSys 2023) took place from 7th – 10th June 2023 in Vancouver, Canada. The MMSys conference brings together researchers in multimedia systems to showcase and exchange their cutting-edge research findings. Once again, there were technical talks spanning various multimedia domains and inspiring keynote presentations. Participants had also the opportunity to further interact with colleagues while enjoying the sunset with a 360° view of Vancouver on the Lookout tower or during a dinner in the core of the rainforest. Additionally, this year’s event included a special session dedicated to the memory of Dr. Kuan-Ta Chen, to honor his invaluable contributions to the multimedia community and to inspire the future generation of researches.
To encourage junior researchers to participate on-site, SIGMM has sponsored a group of students with Student Travel Grant Awards. For many of them, this was their first time presenting at an international conference, and it was a wonderful experience. In this article, the recipients of the travel grants share their experiences at MMSys 2023.
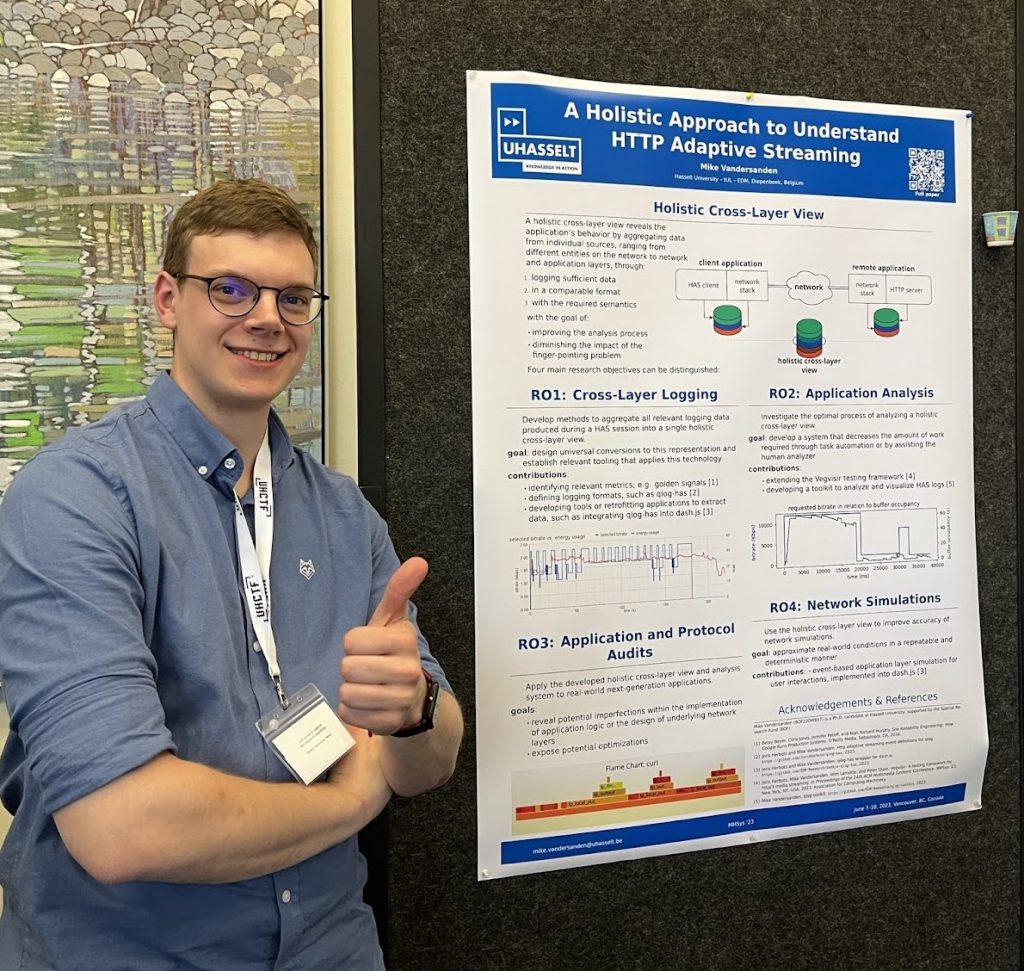
Mike Vandersanden, PhD student from Hasselt University, Belgium
As a new PhD student starting my professional academic career less than a year before MMSys ’23, I focused on finding my place in the academic community. My advisor and colleagues encouraged me to achieve two goals: get feedback on my research and build a network. I submitted my first paper and it got accepted for the Doctoral Symposium at the conference, which was a great opportunity to work towards achieving my goals. Presenting my paper allowed me to receive helpful feedback, have interesting discussions, and gain new perspectives. It was motivating to see people interested in my work. During the rest of the conference, I connected with many attendees from different parts of the world. The social events were a great way to meet others, and we also had enjoyable evenings downtown. Upon returning home, I was happy to report to my advisor that I accomplished all my goals for the first year. I am grateful for receiving a student travel grant, as it made it easier to travel to another continent. It also gave me the freedom to manage my budget and increases my chances of attending the conference again next year.
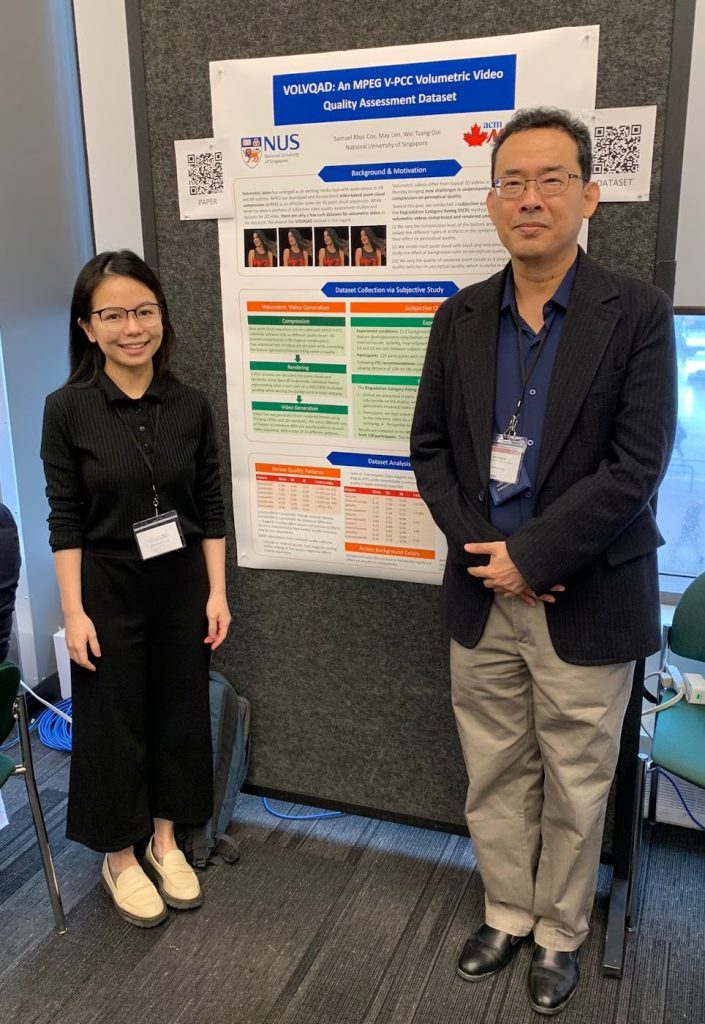
May Lim, PhD student from National University of Singapore, Singapore
I was both excited and nervous for MMSys 2023 as it was not only my first in-person conference but also in a country I had never visited before. The conference turned out to be one of the most unforgettable and pleasant experience I ever had. It was well-organized with very insightful presentations, many opportunities to interact and exchange contacts with fellow researchers, and not forgetting the organizers’ thoughtful efforts to ensure the great comfort and welfare of the participants. Vancouver’s weather and people were very kind as well.
I am thankful for the travel grant and the support from ACM SIGMM was truly heartening. I hope to continue to be part of this community and pay it forward in other ways.
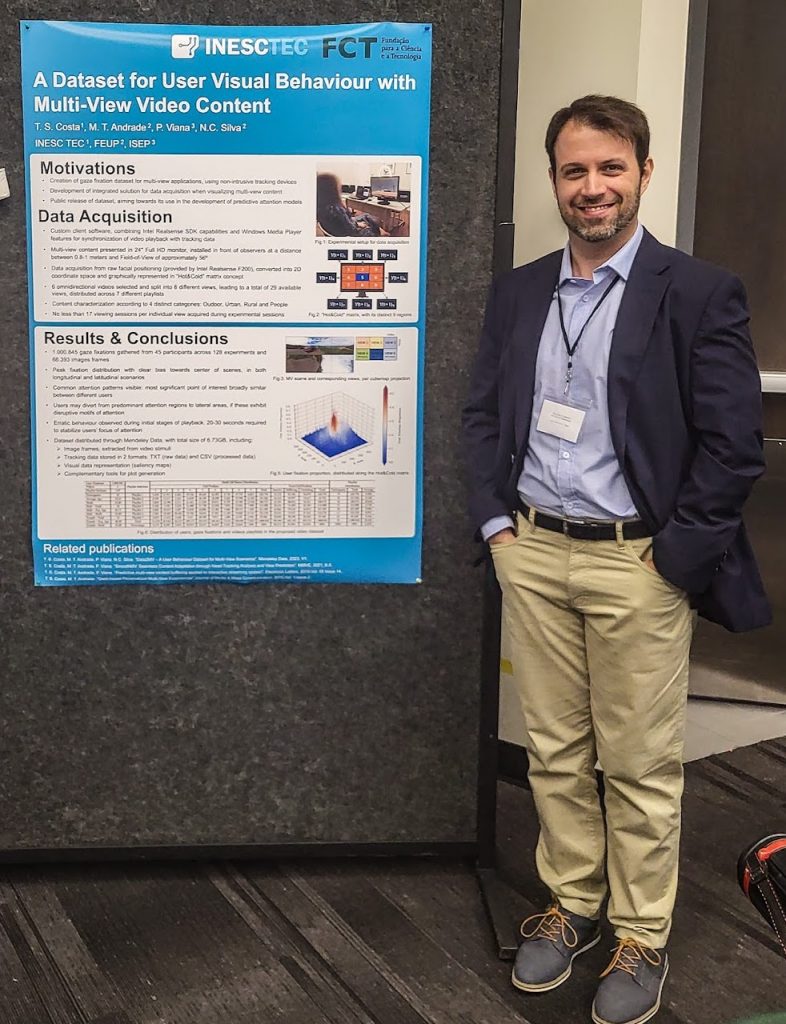
Tiago Soares da Costa, PhD student from FEUP, Portugal
MMSys 2023 marked my return to in-person conferences and was one of the most well organized conferences I had the pleasure to participate in. After several virtual conferences, being able to actively meet and discuss interesting topics related to multimedia with fellow researchers was a breath of fresh air. The keynote presentation from Klara Nahrstedt was one of my highlights from MMSys 2023, due to its extensive focus on multi-view streaming, one of the main topics from my PhD research. Ihab Amer was another welcome surprise, presenting us with the current trends in AI encoding from one of the leading tech enterprises, AMD. Regarding paper presentations, I have to highlight the following works: 1) “The AD△ER Framework: Tools for Event Video Representations“, for providing us with a new approach to frameless videos; 2) “Remote Expert Assistance System for Mixed-HMD Clients over 5G Infrastructure” for delivering an impressive tech demonstration; 3) “FleXR: A System Enabling Flexibly Distributed Extended Reality“, for presenting us with a distributed stream processing solution which can be effectively applied to XR-based environments. As for the social events from MMSys 2023, the sights and sounds from Grouse Mountain and the impressive view from the Vancouver Lookout Tower were among some of my favourite moments in Vancouver, that I will forever cherish. Overall, MMSys 2023 was an amazing conference and I’m particularly grateful to the SIGMM committee for providing me with the travel grant.
Yu-Szu Wei from National Tsing Hua University, Taiwan
It is a great honor for me to receive the student travel grant and I appreciate it so much. ACM MMsys 2023 is my first in-person experience attending an international conference, it certainly is a fantastic experience for me. I met lots of astonishing researchers and volunteers who solve problems with different, creative, and novel approaches. I exchanged my ideas with them and learned a lot from them. The keynote sessions also gave me brand-new mindsets, finding out that there are lots of issues for us to investigate and deal with. The most impressive thing for me is to stand on the stage and present my work to those experts. I’m so proud of myself for delivering my research ideas in front of the public and gaining abundant feedback from the audience.
Thanks to the committee that organized this awesome event, and provided me the travel grant to attend the conference. I’m looking forward to attending ACM MMSys again in the future.
The 142nd MPEG meeting was held as a face-to-face meeting in Antalya, Türkiye, and the official press release can be found here and comprises the following items:
MPEG issues Call for Proposals for Feature Coding for Machines
MPEG finalizes the 9th Edition of MPEG-2 Systems
MPEG reaches the First Milestone for Storage and Delivery of Haptics Data
MPEG completes 2nd Edition of Neural Network Coding (NNC)
MPEG completes Verification Test Report and Conformance and Reference Software for MPEG Immersive Video
MPEG finalizes work on metadata-based MPEG-D DRC Loudness Leveling
The press release text has been modified to match the target audience of ACM SIGMM and highlight research aspects targeting researchers in video technologies. This column focuses on the 9th edition of MPEG-2 Systems, storage and delivery of haptics data, neural network coding (NNC), MPEG immersive video (MIV), and updates on MPEG-DASH.
Feature Coding for Video Coding for Machines (FCVCM)
At the 142nd MPEG meeting, MPEG Technical Requirements (WG 2) issued a Call for Proposals (CfP) for technologies and solutions enabling efficient feature compression for video coding for machine vision tasks. This work on “Feature Coding for Video Coding for Machines (FCVCM)” aims at compressing intermediate features within neural networks for machine tasks. As applications for neural networks become more prevalent and the neural networks increase in complexity, use cases such as computational offload become more relevant to facilitate the widespread deployment of applications utilizing such networks. Initially as part of the “Video Coding for Machines” activity, over the last four years, MPEG has investigated potential technologies for efficient compression of feature data encountered within neural networks. This activity has resulted in establishing a set of ‘feature anchors’ that demonstrate the achievable performance for compressing feature data using state-of-the-art standardized technology. These feature anchors include tasks performed on four datasets.
Research aspects: FCVCM is about compression, and the central research aspect here is compression efficiency which can be tested against a commonly agreed dataset (anchors). Additionally, it might be attractive to research which features are relevant for video coding for machines (VCM) and quality metrics in this emerging domain. One might wonder whether, in the future, robots or other AI systems will participate in subjective quality assessments.
9th Edition of MPEG-2 Systems
MPEG-2 Systems was first standardized in 1994, defining two container formats: program stream (e.g., used for DVDs) and transport stream. The latter, also known as MPEG-2 Transport Stream (M2TS), is used for broadcast and internet TV applications and services. MPEG-2 Systems has been awarded a Technology and Engineering Emmy® in 2013 and at the 142nd MPEG meeting, MPEG Systems (WG 3) ratified the 9th edition of ISO/IEC 13818-1 MPEG-2 Systems. The new edition includes support for Low Complexity Enhancement Video Coding (LCEVC), the youngest in the MPEG family of video coding standards on top of more than 50 media stream types, including, but not limited to, 3D Audio and Versatile Video Coding (VVC). The new edition also supports new options for signaling different kinds of media, which can aid the selection of the best audio or other media tracks for specific purposes or user preferences. As an example, it can indicate that a media track provides information about a current emergency.
Research aspects: MPEG container formats such as MPEG-2 Systems and ISO Base Media File Format are necessary for storing and delivering multimedia content but are often neglected in research. Thus, I would like to take up the cudgels on behalf of the MPEG Systems working group and argue that researchers should pay more attention to these container formats and conduct research and experiments for its efficient use with respect to multimedia storage and delivery.
Storage and Delivery of Haptics Data
At the 142nd MPEG meeting, MPEG Systems (WG 3) reached the first milestone for ISO/IEC 23090-32 entitled “Carriage of haptics data” by promoting the text to Committee Draft (CD) status. This specification enables the storage and delivery of haptics data (defined by ISO/IEC 23090-31) in the ISO Base Media File Format (ISOBMFF; ISO/IEC 14496-12). Considering the nature of haptics data composed of spatial and temporal components, a data unit with various spatial or temporal data packets is used as a basic entity like an access unit of audio-visual media. Additionally, an explicit indication of a silent period considering the sparse nature of haptics data has been introduced in this draft. The standard is planned to be completed, i.e., to reach the status of Final Draft International Standard (FDIS), by the end of 2024.
Research aspects: Coding (ISO/IEC 23090-31) and carriage (ISO/IEC 23090-32) of haptics data goes hand in hand and needs further investigation concerning compression efficiency and storage/delivery performance with respect to various use cases.
Neural Network Coding (NNC)
Many applications of artificial neural networks for multimedia analysis and processing (e.g., visual and acoustic classification, extraction of multimedia descriptors, or image and video coding) utilize edge-based content processing or federated training. The trained neural networks for these applications contain many parameters (weights), resulting in a considerable size. Therefore, the MPEG standard for the compressed representation of neural networks for multimedia content description and analysis (NNC, ISO/IEC 15938-17, published in 2022) was developed, which provides a broad set of technologies for parameter reduction and quantization to compress entire neural networks efficiently.
Recently, an increasing number of artificial intelligence applications, such as edge-based content processing, content-adaptive video post-processing filters, or federated training, need to exchange updates of neural networks (e.g., after training on additional data or fine-tuning to specific content). Such updates include changes in the neural network parameters but may also involve structural changes in the neural network (e.g. when extending a classification method with a new class). In scenarios like federated training, these updates must be exchanged frequently, such that much more bandwidth over time is required, e.g., in contrast to the initial deployment of trained neural networks.
The second edition of NNC addresses these applications through efficient representation and coding of incremental updates and extending the set of compression tools that can be applied to both entire neural networks and updates. Trained models can be compressed to at least 10-20% and, for several architectures, even below 3% of their original size without performance loss. Higher compression rates are possible at moderate performance degradation. In a distributed training scenario, a model update after a training iteration can be represented at 1% or less of the base model size on average without sacrificing the classification performance of the neural network. NNC also provides synchronization mechanisms, particularly for distributed artificial intelligence scenarios, e.g., if clients in a federated learning environment drop out and later rejoin.
Research aspects: The incremental compression of neural networks enables various new use cases, which provides research opportunities for media coding and communication, including optimization thereof.
MPEG Immersive Video
At the 142nd MPEG meeting, MPEG Video Coding (WG 4) issued the verification test report of ISO/IEC 23090-12 MPEG immersive video (MIV) and completed the development of the conformance and reference software for MIV (ISO/IEC 23090-23), promoting it to the Final Draft International Standard (FDIS) stage.
MIV was developed to support the compression of immersive video content, in which multiple real or virtual cameras capture a real or virtual 3D scene. The standard enables the storage and distribution of immersive video content over existing and future networks for playback with 6 degrees of freedom (6DoF) of view position and orientation. MIV is a flexible standard for multi-view video plus depth (MVD) and multi-planar video (MPI) that leverages strong hardware support for commonly used video formats to compress volumetric video.
ISO/IEC 23090-23 specifies how to conduct conformance tests and provides reference encoder and decoder software for MIV. This draft includes 23 verified and validated conformance bitstreams spanning all profiles and encoding and decoding reference software based on version 15.1.1 of the test model for MPEG immersive video (TMIV). The test model, objective metrics, and other tools are publicly available at https://gitlab.com/mpeg-i-visual.
Research aspects: Conformance and reference software are usually provided to facilitate product conformance testing, but it also provides researchers with a common platform and dataset, allowing for the reproducibility of their research efforts. Luckily, conformance and reference software are typically publicly available with an appropriate open-source license.
MPEG-DASH Updates
Finally, I’d like to provide a quick update regarding MPEG-DASH, which has become a new part, namely redundant encoding and packaging for segmented live media (REAP; ISO/IEC 23009-9). The following figure provides the reference workflow for redundant encoding and packaging of live segmented media.
Reference workflow for redundant encoding and packaging of live segmented media.
The reference workflow comprises (i) Ingest Media Presentation Description (I-MPD), (ii) Distribution Media Presentation Description (D-MPD), and (iii) Storage Media Presentation Description (S-MPD), among others; each defining constraints on the MPD and tracks of ISO base media file format (ISOBMFF).
Additionally, the MPEG-DASH Break out Group discussed various technologies under consideration, such as (a) combining HTTP GET requests, (b) signaling common media client data (CMCD) and common media server data (CMSD) in a MPEG-DASH MPD, (c) image and video overlays in DASH, and (d) updates on lower latency.
An updated overview of DASH standards/features can be found in the Figure below.
Research aspects: The REAP committee draft (CD) is publicly available feedback from academia and industry is appreciated. In particular, first performance evaluations or/and reports from proof of concept implementations/deployments would be insightful for the next steps in the standardization of REAP.
The 143rd MPEG meeting will be held in Geneva from July 17-21, 2023. Click here for more information about MPEG meetings and their developments.
The works addressed by this new group can be of interest for the SIGMM community since they are related to AI-based technologies for image and video processing, greening of streaming, blockchain in media and entertainment, and ongoing related standardization activities.
About ETG
The main objective of this group is to address various aspects of multimedia that do not fall under the scope of any of the existing VQEG groups. The group, through its activities, aims to provide a common platform for people to gather together and discuss new emerging topics and ideas, discuss possible collaborations in the form of joint survey papers/whitepapers, funding proposals, etc. The topics addressed are not necessarily directly related to “video quality” but rather focus on any ongoing work in the field of multimedia which can indirectly impact the work addressed as part of VQEG.
Scope
During the creation of the group, the following topics were tentatively identified to be of possible interest to the members of this group and VQEG in general:
AI-based technologies:
Super Resolution
Learning-based video compression
Video coding for machines, etc.,
Enhancement, Denoising and other pre- and post-filter techniques
Greening of streaming and related trends
For example, trade-off between HDR and SDR to save energy and its impact on visual quality
Ongoing Standards Activities (which might impact the QoE of end users and hence will be relevant for VQEG)
3GPP, SVTA, CTA WAVE, UHDF, etc.
MPEG/JVET
Blockchain in Media and Entertainment
Since the creation of the group, four talks on various topics have been organized, an overview of which is summarized next.
Overview of the Presentations
We briefly provide a summary of various talks that have been organized by the group since its inception.
On the work by MPEG Systems Smart Contracts for Media Subgroup
The first presentation was on the topic of the recent work by MPEG Systems on Smart Contract for Media [1], which was delivered by Dr Panos Kudumakis who is the Head of UK Delegation, ISO/IEC JTC1/SC29 & Chair of British Standards Institute (BSI) IST/37. Dr Panos in this talk highlighted the efforts in the last few years by MPEG towards developing several standardized ontologies catering to the needs of the media industry with respect to the codification of Intellectual Property Rights (IPR) information toward the fair trade of media. However, since inference and reasoning capabilities normally associated with ontology use cannot naturally be done on DLT environments, there is a huge potential to unlock the Semantic Web and, in turn, the creative economy by bridging this interoperability gap [2]. In that direction, ISO/IEC 21000-23 Smart Contracts for Media standard specifies the means (e.g., APIs) for converting MPEG IPR ontologies to smart contracts that can be executed on existing DLT environments [3]. The talk discussed the recent works that have been done as part of this effort and also on the ongoing efforts towards the design of a full-fledged ISO/IEC 23000-23 Decentralized Media Rights Application Format standard based on MPEG technologies (e.g., audio-visual codecs, file formats, streaming protocols, and smart contracts) and non-MPEG technologies (e.g., DLTs, content, and creator IDs). The recording of the presentation is available here, and the slides can be accessed here.
Introduction to NTIRE Workshop on Quality Assessment for Video Enhancement
The second presentation was given by Xiaohong Liu and Yuxuan Gao from Shanghai Jiao Tong University, China about one of the CVPR challenge workshops called the NTIRE 2023 Quality Assessment of Video Enhancement Challenge. The presentation described the motivation for starting this challenge and how this is of great relevance to the video community in general. Then the presenters described the dataset such as the dataset creation process, subjective tests to obtain ratings, and the reasoning behind the choice of the split of the dataset into training, validation, and test sets. The results of this challenge are scheduled to be presented at the upcoming spring meeting end of June 2023. The presentation recording is available here.
Perception: The Next Milestone in Learned Image Compression
Johannes Balle from Google was the third presenter on the topic of “Perception: The Next Milestone in Learned Image Compression.” In the first part, Johannes discussed the learned compression and described the nonlinear transforms [4] and how they could achieve a higher image compression rate than linear transforms. Next, they emphasized the importance of perceptual metrics in comparison to distortion metrics by introducing the difference between perceptual quality vs. reconstruction quality [5]. Next, an example of generative-based image compression is presented where the two criteria of distortion metric and perceptual metric (named as realism criteria) are combined, HiFiC [6]. Finally, the talk concluded with an introduction to perceptual spaces and an example of a perceptual metric, PIM [7]. The presentation slides can be found here.
Compression with Neural Fields
Emilien Dupont (DeepMind) was the fourth presenter. He started the talk with a short introduction on the emergence of neural compression that fits a signal, e.g., an image or video, to a neural network. He then discussed the two recent works on neural compression that he was involved in, named COIN [8] and COIN++ [9]. He then made a short overview of other Implicit Neural Representation in the domain of video such as NerV [10] and NIRVANA [11]. The slides for the presentation can be found here.
Upcoming Presentations
As part of the ongoing efforts of the group, the following talks/presentations are scheduled in the next two months. For an updated schedule and list of presentations, please check the ETG homepage here.
Sustainable/Green Video Streaming
Given the increasing carbon footprint of streaming services and climate crisis, many new collaborative efforts have started recently, such as the Greening of the Streaming alliance, Ultra HD Sustainability forum, etc. In addition, research works recently have started focussing on how to make video streaming more greener/sustainable. A talk providing an overview of the recent works and progress in direction is tentatively scheduled around mid-May, 2023.
Panel discussion at VQEG Spring Meeting (June 26-30, 2023), Sony Interactive Entertainment HQ, San Mateo, US
During the next face-to-face VQEG meeting in San Mateo there will be an interesting panel discussion on the topic of “Deep Learning in Video Quality and Compression.” The goal is to invite the machine learning experts to VQEG and bring the two groups closer. ETG will organize the panel discussion, and the following four panellists are currently invited to join this event: Zhi Li (Netflix), Ioannis Katsavounidis (Meta), Richard Zhang (Adobe), and Mathias Wien (RWTH Aachen). Before this panel discussion, two talks are tentatively scheduled, the first one on video super-resolution and the second one focussing on learned image compression. The meeting will talk place in hybrid mode allowing for participation both in-person and online. For further information about the meeting, please check the details here and if interested, register for the meeting.
Joining and Other Logistics
While participation in the talks is open to everyone, to get notified about upcoming talks and participate in the discussion, please consider subscribing to etg@vqeg.org email reflector and join the slack channel using this link. The meeting minutes are available here. We are always looking for new ideas to improve. If you have suggestions on topics we should focus on or have recommendation of presenters, please reach out to the chairs (Nabajeet and Saman).
JPEG explores standardization in event-based imaging
The 98th JPEG meeting was held in Sydney, Australia, from the 16th to 20th January 2023. This was a welcome return to face-to-face meetings after a long period of online meetings due to Covid-19 pandemics. Interestingly, the previous face-to-face meeting of the JPEG Committee was also held in Sydney, in January 2020. The face-to-face 98th JPEG meeting was complemented with online connections to allow the remote participation of those who could not be present.
The recent calls for proposals, such as JPEG Fake Media, JPEG AI and JPEG Pleno Learning Based Point Cloud Coding, resulted in a very dynamic and participative meeting in Sydney, with multiple technical sessions and decisions. Exploration activities such as JPEG DNA and JPEG NFT also produced drafts of future calls for proposals as a consequence of reaching sufficient maturity.
Furthermore, and considering the current trends in machine-based imaging applications, the JPEG Committee initiated an exploration on standardization in event-based imaging.
98th JPEG Meeting first plenary.
The 98th JPEG meeting had the following highlights:
New JPEG exploration in event-based imaging;
JPEG Fake Media and NFT;
JPEG AI;
JPEG Pleno Learning-based Point Cloud Coding improves its Verification Model;
JPEG AIC prepares the analysis of the responses to the Call for Contribution;
JPEG XL second editions;
JPEG Systems;
JPEG DNA prepares its call for proposals;
JPEG XS 3rd Edition;
JPEG 2000 guidelines.
The following summarizes the major achievements during the 98th JPEG meeting.
New JPEG exploration in event-based imaging
The JPEG Committee has started a new exploration activity on event-based imaging named JPEG XE.
Event-based Imaging revolves around a new and emerging image modality created by event-based visual sensors. Event-based sensors are the foundation for a new class of cameras that allow the efficient capture of visual information at high speed while at the same time requiring low computational cost, a requirement which it is common in many machine vision applications. Such sensors are modeled based on the mechanisms of the human visual system for the detection of scene changes and the asynchronous capture of those changes. This means that every pixel works individually to detect scene changes and creates the associated events. If nothing happens, then no events are generated. This contrasts with conventional image sensors, where pixels are sampled in a continuous and periodic manner, with images generated regardless of any changes in the scene and a risk of reacting with delay and even missing quick changes.
The JPEG Committee recognizes that this new image modality opens doors to a large number of applications where capture and processing of visual information is needed. Currently, there is no standard format to represent event-based information, and therefore existing and emerging applications are fragmented and lack interoperability. The new JPEG XE activity focuses on establishing a scope and relevant definitions, collecting use cases and their associated requirements, and investigating the role that JPEG can play in the definition of timely standards in the near- and long-term. To start, an Ad-hoc Group has been established. To stay informed about the activities please join the event based imaging Ad-hoc Group mailing list.
JPEG Fake Media and NFT
In April 2022, the JPEG Committee released a Final Call for Proposals on JPEG Fake Media. The scope of JPEG Fake Media is the creation of a standard that can facilitate the secure and reliable annotation of media assets creation and modifications. During the 98th meeting, the JPEG Committee finalised the evaluation of the six submitted proposals and initiated the process for establishing a new standard.
The JPEG Committee also continues to explore use cases and requirements related to Non-Fungible Tokens (NFTs). Although the use cases for both topics are very different, there is a clear commonality in terms of requirements and relevant solutions. An updated version of the “Use Cases and Requirements for JPEG NFT” was produced and made publicly available for review and feedback.
To stay informed about the activities, please join the mailing list of the Ad-hoc Group and regularly check the JPEG website for the latest information.
JPEG AI
Following the creation of the JPEG AI Verification Model at the previous 97th JPEG meeting, more discussions occurred at the 98th meeting to improve the coding efficiency, and complexity, especially on the decoder side. The JPEG AI VM has several unique characteristics, such as a parallelizable context model to perform latent prediction, decoupling of prediction and sample reconstruction, and rate adaptation, among others. JPEG AI VM shows up to 31% compression gain over VVC Intra for natural content. A new JPEG AI test set was released during the 98th meeting. This is a large dataset for the evaluation of the JPEG AI VM containing 50 images, with the objective of tracking the performance improvements at every meeting. The JPEG AI Common Training and Test Conditions were updated to include this new dataset. In this meeting, it was also decided to integrate several changes into the JPEG AI VM, speeding up training, improving performance at high rates and fixing bugs. A set of core experiments were established at this meeting targeting RD performance and complexity improvements. The JPEG AI VM Software Guidelines were approved, describing the initial setup repository of JPEG AI VM, how to obtain the JPEG AI dataset, and how to run tests and training. A description of the structure of the JPEG AI VM repository was also made available.
JPEG Pleno Learning-based Point Cloud coding
The JPEG Pleno Point Cloud activity progressed at this meeting with a number of technical submissions for improvements to the VM in the area of colour coding, artefact processing and improvements to coding speed. In addition, the JPEG Committee released the “Call for Content for JPEG Pleno Point Cloud Coding” to expand on the current training and test set with new point clouds representing key use cases. Prior to the 99th JPEG Meeting, JPEG experts will promote the Call for Content as well as investigate possible advancements to the VM in the areas of auto-regressive entropy encoding, sparse tensor convolution, meta-data controlled post-filtering of colour and a flexible split geometry and colour coding framework for the VM.
JPEG AIC
During the 98th JPEG meeting in Sydney, Australia, Exploration Study 1 on JPEG AIC was established. This exploration study will collect results from three types of previously standardized subjective evaluation methodologies in order to provide an informative reference for the JPEG AIC submissions to the Call for Contributions that are due by April 1st, 2023. Corrections and additions to the JPEG AIC Common Test Conditions were issued in order to reflect the addition of a new codec for testing content generation and a new anchor subjective quality assessment methodology.
The JPEG Committee is working on the continuation of the previous standardization efforts (AIC-1 and AIC-2) and aims at developing a new standard, known as AIC-3. The new standard will focus on the methodologies for quality assessment of images in a range that goes from high quality to near-visually lossless quality, which are not covered by any previous AIC standards.
JPEG XL
The second editions of JPEG XL Part 1 (Core coding system) and Part 2 (File format) have reached the CD stage. These second editions provide clarifications, corrections and editorial improvements that will facilitate independent implementations. Also, an updated version of the JPEG XL White Paper has been published and is freely available through jpeg.org.
JPEG Systems
The JLINK standard (19566-7:2022) is now published by ISO. JLINK specifies an image file format capable of linking multiple media elements, such as image and text in any JPEG file format. It enables enhanced curated experiences of a set of images for education, training, virtual museum tours, travelogs, and similar visually-oriented content.
The JPEG Snack (19566-8) standard is expected to be published in February 2023. JPEG Snack specifies the coding of audio, picture, multimedia and hypermedia information, enabling a rich, image-based, short-form animated experiences for social media.
The second edition of JUMBF (JPEG Universal Metadata Box Format, 19566-5) is progressing to IS stage; the second edition brings new capabilities and support for additional types of media.
JPEG DNA
The JPEG Committee has been working on an exploration for coding of images in quaternary representations particularly suitable for image archival on DNA storage. The scope of JPEG DNA is the creation of a standard for efficient coding of images that considers biochemical constraints and offers robustness to noise introduced by the different stages of the storage process that is based on DNA synthetic polymers. During the 98th JPEG meeting, a draft Call for Proposals for JPEG DNA was issued and made public, as a first concrete step towards standardisation. The draft call for proposals for JPEG DNA is complemented by a JPEG DNA Common Test Conditions document which is also made public, describing details about the dataset, operating points, anchors and performance assessment methodologies and metrics that will be used to evaluate anchors and future responses to the Call for Proposals. The final Call for Proposals for JPEG DNA is expected to be released at the conclusion of the 99th JPEG meeting in April 2023, after a set of exploration experiments have validated the procedures outlined in the draft Call for Proposals for JPEG DNA and JPEG DNA Common Test Conditions. The deadline for submission of proposals to the Call for Proposals for JPEG DNA is 2 October 2023 with a pre-registration due by 10 July 2023. The JPEG DNA international standard is expected to be published by early 2025.
JPEG XS
The JPEG Committee continued with the definition of JPEG XS 3rd edition. The primary goal of the 3rd edition is to deliver the same image quality as the 2nd edition, but with half of the required bandwidth. The Committee Draft for Part 1 (Core coding system) will proceed to ISO ballot. This means that the standard is now technically defined, and all the new coding tools are known. Most notably, Part 1 adds a temporal decorrelation coding mode to further improve the coding efficiency, while keeping the low-latency and low-complexity core aspects of JPEG XS. This new coding tool is of extreme importance for remote desktop applications and screen sharing. In addition, mathematically lossless coding can now support up to 16 bits precision (up from 12 bits). For Part 2 (Profiles and buffer models), the committee created a second Working Draft and issued further core experiments to proceed and support this work. Meanwhile, ISO approved the creation of a new edition of Part 3 (Transport and container formats) that is needed to address the changes of Part 1 and Part 2.
JPEG 2000
The JPEG committee publishes two sets of guidelines for implementers of JPEG 2000, available on jpeg.org.
The first describes an algorithm for controlling JPEG 2000 coding quality using a single number (Qfactor) between 1 (worst quality) and 100 (best quality), as is commonly done with JPEG.
The second explains how to create, parse and use HTJ2K placeholder passes and HT Sets. These features are an integral part of HTJ2K and enable mathematically lossless transcoding between HT- and J2K-based codestreams, among other applications.
Final Quote
“The interest in event-based imaging has been rising with several products designed and offered by the industry. The JPEG Committee believes in interoperable solutions and has initiated an exploration for standardization of event-based imaging in order to accelerate creation of an ecosystem.” said Prof. Touradj Ebrahimi, the Convenor of the JPEG Committee.
Upcoming JPEG meetings are planned as follows:
No 99, will be online from 24-28 April 2023
No 100, will be in Covilhã, Portugal from 17-21 July 2023
ACM SIGMM co-sponsored the Spring School on Social XR, organized by the Distributed and Interactive Systems group (DIS) at CWI in Amsterdam. The event took place on March 13th – 17th 2023 and attracted 33 students from different disciplines (technology, social sciences, and humanities). The program included 18 lectures, 4 of them open, by 20 instructors. The event was co-sponsored by the ACM Special Interest Group on Multimedia ACM SIGMM, making available student grants, and The Netherlands Institute for Sound and Vision (https://www.beeldengeluid.nl/en). The event was part of the recently started research semester programmes of CWI.
Students and organisers of the Spring School on Social XR (March 13th – 17th 2023, Amsterdam)
“The future of media communication is immersive, and will empower sectors such as cultural heritage, education, manufacturing, and provide a climate-neutral alternative to travelling in the European Green Deal”. With such a vision in mind, the organization committee created a holistic program around the research topic of Social XR. The program included keynotes and workshops, where prominent scientists in the field shared their knowledge with students and triggered meaningful conversations and exchanges.
The program included topics such as the capturing and modelling of realistic avatars and their behavior, coding and transmission techniques of volumetric video content, ethics for the design and development of responsible social XR experiences, novel rending and interaction paradigms, and human factors and evaluation of experiences. Together, they provided a holistic perspective, helping participants to better understand the area and to initiate a network of collaboration to overcome current limitations of current real-time conferencing systems.
Apart from science, there is always time for fun, so a number of social events took place, including a visit to the recently renovated Museum of Sound and Vision!
Museum of Sound and Vision
The spring school is part of the semester program organized by the DIS group of CWI, which was initiated in May 2022 with the Symposium on human-centered multimedia systems: a workshop and seminar to celebrate the inaugural lecture, “Human-Centered Multimedia: Making Remote Togetherness Possible” of Prof. Pablo Cesar.
This column provides an overview of the last Video Quality Experts Group (VQEG) plenary meeting, which took place from 12 to 16 December 2022. Around 100 participants from 21 different countries around the world registered for the meeting that was organized online by Brightcove (United Kingdom). During the five days, there were more than 40 presentations and discussions among researchers working on topics related to the projects ongoing within VQEG. All the related information, minutes, and files from the meeting are available online on the VQEG meeting website, and video recordings of the meeting are available on Youtube.
Many of the works presented in this meeting can be relevant for the SIGMM community working on quality assessment. Particularly interesting can be the proposals to update and merge ITU-T recommendations P.913, P.911, and P.910, the kick-off of the test plan to evaluate the QoE of immersive interactive communication systems, and the creation of a new group on emerging technologies that will start working on AI-based technologies and greening of streaming and related trends.
We encourage readers interested in any of the activities going on in the working groups to check their websites and subscribe to the corresponding reflectors, to follow them and get involved.
Group picture of the VQEG Meeting 12-16 December 2022 (online).
Overview of VQEG Projects
Audiovisual HD (AVHD)
The AVHD group investigates improved subjective and objective methods for analysing commonly available video systems. Currently, there are two projects ongoing under this group: Quality of Experience (QoE) Metrics for Live Video Streaming Applications (Live QoE) and Advanced Subjective Methods (AVHD-SUB).
In this meeting, there were three presentations related to topics covered by this group. In the first one, Maria Martini (Kingston University, UK), presented her work on converting video quality assessment metrics. In particular, the work addressed the relationship between SSIM and PSNR for DCT-based compressed images and video, exploiting the content-related factor [1]. The second presentation was given by Urvashi Pal (Akamai, Australia) and dealt with video codec profiling with video quality assessment complexities and resolutions. Finally, Jingwen Zhu (Nantes Université, France) presented her work on the benefit of parameter-driven approaches for the modelling and the prediction of a Satisfied User Ratio for compressed videos [2].
Quality Assessment for Health applications (QAH)
The QAH group works on the quality assessment of health applications, considering both subjective evaluation and the development of datasets, objective metrics, and task-based approaches. Currently there is an open discussion on new topics to address within the group, such as the application of visual attention models and studies to health applications. Also, an opportunity to conduct medical perception research was announced, which was proposed by Elizabeth Krupinski and will take place in the European Congress of Radiology (Vienna, Austria, Mar. 2023).
In addition, four research works were presented at the meeting. Firstly, Julie Fournier (INSA Rennes, France) presented new insights on affinity therapy for people with ASD, based on an eye-tracking study on images. The second presentation was delivered by Lumi Xia (INSA Rennes, France) and dealt with the evaluation of the usability of deep learning-based denoising models for low-dose CT simulation. Also, Mohamed Amine Kerkouri (University of Orleans, France), presented his work on deep-based quality assessment of medical images through domain adaptation. Finally, Jorge Caviedes (ASU, USA) delivered a talk on cognition inspired diagnostic image quality models, emphasising the need of distinguishing among interpretability (e.g., medical professional is confident in making a diagnosis), adequacy (e.g., capture technique shows the right area for assessment), and visual quality (e.g., MOS) in quality assessment of medical contents.
Statistical Analysis Methods (SAM)
The SAM group works on improving analysis methods both for the results of subjective experiments and for objective quality models and metrics. The group is currently working on updating and merging the ITU-T recommendations P.913, P.911, and P.910. The suggestion is to make P.910 and P.911 obsolete and make P.913 the only recommendation from ITU-T on subjective video quality assessments. The group worked on the liaison and document to be sent to ITU-T SG12 and will be available in the meeting files.
In addition, Mohsen Jenadeleh (Univerity of Konstanz, Germany) presented his work
on collective just noticeable difference assessment for compressed video with
Flicker Test and QUEST+.
Computer Generated Imagery (CGI)
CGI group is devoted to analysing and evaluating computer-generated content, with a focus on gaming in particular. The group is currently working in collaboration with ITU-T SG12 on the work item P.BBQCG on Parametric bitstream-based Quality Assessment of Cloud Gaming Services. In this sense, Saman Zadtootaghaj (Sony Interactive Entertainment, Germany) provided an update on the ongoing activities. In addition, they are working on two new work items: G.OMMOG on Opinion Model for Mobile Online Gaming applications and P.CROWDG on Subjective Evaluation of Gaming Quality with a Crowdsourcing Approach. Also, the group is working on identifying other topics and interests in CGI rather than gaming content.
No Reference Metrics (NORM)
The NORM group is an open collaborative project for developing no-reference metrics for monitoring visual service quality. Currently, the group is working on three topics: the development of no-reference metrics, the clarification of the computation of the Spatial and Temporal Indexes (SI and TI, defined in the ITU-T Recommendation P.910), and the development of a standard for video quality metadata.
In relation to the first topic, Margaret Pinson (NTIA/ITS, US), talked about why no-reference metrics for image and video quality lack accuracy and reproducibility [3] and presented new datasets containing camera noise and compression artifacts for the development of no-reference metrics by the group. In addition, Oliver Wiedeman (University of Konstanz, Germany) presented his work on cross-resolution image quality assessment.
Finally, related to the third topic, Ioannis Katsavounidis (Meta, US) provided an update on the status of the project. Given that the idea is already mature enough, a contribution will be made to MPEG to consider the insertion of metadata of video metrics into the encoded video streams. In addition, a liaison with AOMedia will be established that may go beyond this particular topic. And include best practices on subjective testing, IMG topics, etc.
Joint Effort Group (JEG) – Hybrid
The JEG group was focused on a joint work to develop hybrid perceptual/bitstream metrics and gradually evolved over time to include several areas of Video Quality Assessment (VQA), such as the creation of a large dataset for training such models using full-reference metrics instead of subjective metrics. Currently, the group is working on research problems rather than algorithms and models with immediate applicability. In addition, the group has launched a new website, which includes a list of activities of interest, freely available publications, and other resources.
The 5GKPI group studies the relationship between key performance indicators of new 5G networks and QoE of video services on top of them. In this meeting, Pablo Pérez (Nokia XR Lab, Spain) presented an overview of activities related to QoE and XR within 3GPP.
Immersive Media Group (IMG)
The IMG group is focused on the research on quality assessment of immersive media. The main joint activity going on within the group is the development of a test plan to evaluate the QoE of immersive interactive communication systems. After the discussions that took place in previous meetings and audio calls, a tentative schedule has been proposed to start the execution of the test plan in the following months. In this sense, a new work item will be proposed in the next ITU-T SG12 meeting to establish a collaboration between VQEG-IMG and ITU on this topic.
Quality Assessment for Computer Vision Applications (QACoViA)
The goal of the QACoViA group is to study the visual quality requirements for computer vision methods, where the “final observer” is an algorithm. Four presentations were delivered in this meeting addressing diverse related topics. In the first one, Mikołaj Leszczuk (AGH University, Poland) presented a method for assessing objective video quality for automatic license plate recognition tasks [6]. Also, Femi Adeyemi-Ejeye (University of Surrey, UK) presented his work related to the assessment of rail 8K-UHD CCTV facing video for the investigation of collisions. The third presentation dealt with the application of facial expression recognition and was delivered by Lucie Lévêque (Nantes Université, France), who compared the robustness of humans and deep neural networks on this task [7]. Finally, Alban Marie (INSA Rennes, France) presented a study video coding for machines through a large-scale evaluation of DNNs robustness to compression artefacts for semantic segmentation [8].
Other updates
In relation to the Human Factors for Visual Experiences (HFVE) group, Maria Martini (Kingston University, UK) provided a summary of the status of IEEE recommended practice for the quality assessment of light field imaging. Also, Kjell Brunnström (RISE, Sweden) presented a study related to the perceptual quality of video on simulated low temperatures in LCD vehicle displays.
In addition, a new group was created in this meeting called Emerging Technologies Group (ETG), whose main objective is to address various aspects of multimedia that do not fall under the scope of any of the existing VQEG groups. The topics addressed are not necessarily directly related to “video quality” but can indirectly impact the work addressed as part of VQEG. In particular, two major topics of interest were currently identified: AI-based technologies and greening of streaming and related trends. Nevertheless, the group aims to provide a common platform for people to gather together and discuss new emerging topics, discuss possible collaborations in the form of joint survey papers/whitepapers, funding proposals, etc.
Moreover, it was agreed during the meeting to make the Psycho-Physiological Quality Assessment (PsyPhyQA) group dormant until interest resumes in this effort. Also, it was proposed to move the Implementer’s Guide for Video Quality Metrics (IGVQM) project into the JEG-Hybrid, since their activities are currently closely related. This will be discussed in future group meetings and the final decisions will be announced. Finally, as a reminder, the VQEG GitHub with tools and subjective labs setup is still online and kept updated.
The next VQEG plenary meeting will take place in May 2023 and the location will be announced soon on the VQEG website.
After several years of online meetings, the 140th MPEG meeting was held as a face-to-face meeting in Mainz, Germany, and the official press release can be found here and comprises the following items:
MPEG evaluates the Call for Proposals on Video Coding for Machines
MPEG evaluates Call for Evidence on Video Coding for Machines Feature Coding
MPEG reaches the First Milestone for Haptics Coding
MPEG completes a New Standard for Video Decoding Interface for Immersive Media
MPEG completes Development of Conformance and Reference Software for Compression of Neural Networks
MPEG White Papers: (i)MPEG-H 3D Audio, (ii)MPEG-I Scene Description
Video Coding for Machines
Video coding is the process of compression and decompression of digital video content with the primary purpose of consumption by humans (e.g., watching a movie or video telephony). Recently, however, massive video data is more and more analyzed without human intervention leading to a new paradigm referred to as Video Coding for Machines (VCM) which targets both (i) conventional video coding and (ii) feature coding (see here for further details).
At the 140th MPEG meeting, MPEG Technical Requirements (WG 2) evaluated the responses to the Call for Proposals (CfP) for technologies and solutions enabling efficient video coding for machine vision tasks. A total of 17 responses to this CfP were received, with responses providing various technologies such as (i) learning-based video codecs, (ii) block-based video codecs, (iii) hybrid solutions combining (i) and (ii), and (iv) novel video coding architectures. Several proposals use a region of interest-based approach, where different areas of the frames are coded in varying qualities.
The responses to the CfP reported an improvement in compression efficiency of up to 57% on object tracking, up to 45% on instance segmentation, and up to 39% on object detection, respectively, in terms of bit rate reduction for equivalent task performance. Notably, all requirements defined by WG 2 were addressed by various proposals.
Furthermore, MPEG Technical Requirements (WG 2) evaluated the responses to the Call for Evidence (CfE) for technologies and solutions enabling efficient feature coding for machine vision tasks. A total of eight responses to this CfE were received, of which six responses were considered valid based on the conditions described in the call:
For the tested video dataset increases in compression efficiency of up to 87% compared to the video anchor and over 90% compared to the feature anchor were reported.
For the tested image dataset, the compression efficiency can be increased by over 90% compared to both image and feature anchors.
Research aspects: the main research area is still the same as described in my last column, i.e., compression efficiency (incl. probably runtime, sometimes called complexity) and Quality of Experience (QoE). Additional research aspects are related to the actual task for which video coding for machines is used (e.g., segmentation, object detection, as mentioned above).
Video Decoding Interface for Immersive Media
One of the most distinctive features of immersive media compared to 2D media is that only a tiny portion of the content is presented to the user. Such a portion is interactively selected at the time of consumption. For example, a user may not see the same point cloud object’s front and back sides simultaneously. Thus, for efficiency reasons and depending on the users’ viewpoint, only the front or back sides need to be delivered, decoded, and presented. Similarly, parts of the scene behind the observer may not need to be accessed.
At the 140th MPEG meeting, MPEG Systems (WG 3) reached the final milestone of the Video Decoding Interface for Immersive Media (VDI) standard (ISO/IEC 23090-13) by promoting the text to Final Draft International Standard (FDIS). The standard defines the basic framework and specific implementation of this framework for various video coding standards, including support for application programming interface (API) standards that are widely used in practice, e.g., Vulkan by Khronos.
The VDI standard allows for dynamic adaptation of video bitstreams to provide the decoded output pictures so that the number of actual video decoders can be smaller than the number of elementary video streams to be decoded. In other cases, virtual instances of video decoders can be associated with the portions of elementary streams required to be decoded. With this standard, the resource requirements of a platform running multiple virtual video decoder instances can be further optimized by considering the specific decoded video regions to be presented to the users rather than considering only the number of video elementary streams in use. The first edition of the VDI standard includes support for the following video coding standards: High Efficiency Video Coding (HEVC), Versatile Video Coding (VVC), and Essential Video Coding (EVC).
Research aspect: VDI is also a promising standard to enable the implementation of viewport adaptive tile-based 360-degree video streaming, but its performance still needs to be assessed in various scenarios. However, requesting and decoding individual tiles within a 360-degree video streaming application is a prerequisite for enabling efficiency in such cases, and VDI provides the basis for its implementation.
MPEG-DASH Updates
Finally, I’d like to provide a quick update regarding MPEG-DASH, which seems to be in maintenance mode. As mentioned in my last blog post, amendments, Defects under Investigation (DuI), and Technologies under Consideration (TuC) are output documents, as well as a new working draft called Redundant encoding and packaging for segmented live media (REAP), which eventually will become ISO/IEC 23009-9. The scope of REAP is to define media formats for redundant encoding and packaging of live segmented media, media ingest, and asset storage. The current working draft can be downloaded here.
Research aspects: REAP defines a distributed system and, thus, all research aspects related to such systems apply here, e.g., performance and scalability, just to name a few.
The 141st MPEG meeting will be online from January 16-20, 2023. Click here for more information about MPEG meetings and their developments.
JPEG initiates specification on fake media based on responses to its call for proposals
The 97th JPEG meeting was held online from 24 to 28 October 2022. JPEG received responses to the Call for Proposals (CfP) on JPEG Fake Media, the first multimedia international standard designed to facilitate the secure and reliable annotation of media assets creation and modifications. In total six responses were received addressing different requirements in the scope of this standardization initiative. Moreover, relevant advances were made on the standardization of learning-based coding, notably the learning-based coding of images, JPEG AI, and JPEG Pleno point cloud coding. Furthermore, the explorations on quality assessment of images, JPEG AIC, and of JPEG Pleno light field had relevant advances with the definition of their Calls for Contributions and Common Test Conditions.
Also relevant, the 98th JPEG meeting will be held in Sydney, Australia, representing a return to physical meetings after the long COVID pandemics. This is a return, as the last physical meeting was also held in January 2020 in the same location, in Sydney, Australia.
The 97th JPEG meeting had the following highlights:
JPEG Fake Media responses to the Call for Proposals analysed,
JPEG AI Verification Model,
JPEG Pleno Learning-based Point Cloud coding Verification Model,
JPEG Pleno Light Field issues a Call for Contributions on Subjective Light Field Quality Assessment,
JPEG AIC issues a Call for Contributions on Subjective Image Quality Assessment,
JPEG DNA releases a draft of Common Test Conditions,
JPEG XS prepares third edition of core coding system, and profiles and buffer models,
JPEG 2000 conformance is under development.
Fig. 1: Fake Media application scenarios: Good faith vs Malicious intent.
The following summarises the major achievements of the 97th JPEG meeting.
JPEG Fake Media
In April 2022, the JPEG Committee
released a Final Call for Proposals on JPEG Fake Media. The scope of JPEG Fake
Media is the creation of a standard that can facilitate the secure and reliable
annotation of media assets creation and modifications. The standard shall
address use cases that are in good faith as well as those with malicious
intent. During the 97th meeting in October 2022, the following six responses to
the call were presented:
Adobe/C2PA: C2PA Specification
Huawei: Provenance and Right Management for Digital Contents in
JPEG Fake Media
Sony Group Corporation: Methods to keep track provenance of
media asset and signing data
Vrije Universiteit Brussel/imec: Media revision history tracking
via asset decomposition and serialization
UPC: MIPAMS Provenance module
Newcastle University: Response to JPEG Fake Media
standardization call
In the coming months,
these proposals will be thoroughly evaluated following a process that is open,
transparent, fair and unbiased and allows deep technical discussions to assess
which proposals best address identified requirements. Based on the conclusions
of these discussions, a new standard will be produced to address fake media and
provide solutions for transparency related to media authenticity. The standard
will combine the best elements of the six proposals.
To stay informed about the
activities please join the JPEG Fake Media & NFT AHG mailing list and regularly
check the JPEG website for the latest information.
JPEG AI
JPEG
AI (ISO/IEC 6048) aims at the development of a learning-based image coding
standard offering a single-stream, compact compressed domain representation,
targeting both human visualization with significant compression efficiency
improvement over state-of-the-art image coding standards at similar subjective
quality, and improved performance for image processing and computer vision
tasks. The evaluation of the Call for Proposals responses had already
confirmed the industry interest, and the subjective tests presented at the 96th
JPEG meeting showed results that significantly outperform conventional image
compression solutions.
The
JPEG AI verification model has been issued as the outcome of this meeting and
follows the integration effort of several neural networks and tools. There are
several characteristics that make the JPEG AI Verification Model (VM) unique,
such as the decoupling of the entropy decoding from the sample reconstruction
and the exploitation of the spatial correlation between latents using a
prediction and a fusion network as well as a massively parallelized
auto-regressive network. The performance evaluation has shown significant RD
performance improvements (as much as 32.2% of BD-rate over H.266/VVC) with
competitive decoding complexity. Other functionalities such as rate adaptation
and device interoperability have also been addressed with the use of gain units
and the quantization of the weights in the entropy decoding module. Moreover,
the adoption process for architectural changes and for new or improved coding
tools in JPEG AI VM was approved. A set of core experiments have been
defined for improving the JPEG AI VM and target the improvement of the coding
efficiency and the reduction of the encoding and decoding complexity. The core
experiments represent a set of promising technologies, such as learning-based
GAN training, simplification of the analysis/synthesis transform, adaptive
entropy coding alphabet, and even encoder-only tools and procedures
for training speed-up.
JPEG Pleno Learning-based Point Cloud coding
The JPEG Pleno Point Cloud
activity progressed at this meeting with the successful validation of the
Verification Model under Consideration (VMuC). The VMuC was confirmed as the
Verification Model (VM) to form the core of the future standard; ISO/IEC 21794
Part 6 JPEG Pleno: Learning-based Point Cloud Coding. The JPEG Committee has
commenced work on the Working Draft of the standard, with initial text reviewed
at this meeting. Prior to the next 98th JPEG Meeting, JPEG experts
will investigate possible advancements to the VM in the area of auto-regressive
entropy encoding and sparse tensor convolution as well as sourcing additional
point clouds for the JPEG Pleno Point Cloud test set.
JPEG Pleno Light Field
During the 97th meeting, the JPEG Committee released the
“JPEG Pleno Final Call for Contributions on Subjective Light Field Quality
Assessment”, to collect new procedures and best practices regarding light field
subjective quality evaluation methodologies to assess artifacts induced by
coding algorithms. All contributions, including test procedures, datasets, and
any additional information, will be considered to develop the standard by
consensus among the JPEG experts following a collaborative process approach.
The deadline for submission of contributions is April 1, 2023.
The JPEG Committee organized its 1st workshop on light
field quality assessment to discuss challenges and current solutions for
subjective light field quality assessment, explore relevant use cases and requirements,
and provide a forum for researchers to discuss the latest findings in this
area. The JPEG Committee also promoted its 2nd workshop on
learning-based light field coding to exchange experiences and to present
technological advances in learning-based coding solutions for light field
data. The proceedings and video footage of both workshops are now
accessible on the JPEG website.
JPEG AIC
At the 97th
JPEG Meeting, a new JPEG AIC Final Call for Contributions on Subjective Image
Quality Assessment was issued. The JPEG Committee is working on the continuation
of the previous standardization efforts (AIC-1 and AIC-2) and aims at
developing a new standard, known as AIC-3. The new standard will be focusing on
the methodologies for quality assessment of images in a range that goes from
high quality to near-visually lossless quality, which are not covered by the
previous AIC standards.
The Call
for Contributions on Subjective Image Quality Assessment is asking for
contributions to the standardization process that will be collaborative from
the very beginning. In this context, all received contributions will be
considered for the development of the standard by consensus among the JPEG
experts.
The JPEG Committee
will be releasing a new JPEG AIC-3 Dataset on the 15th of December
2022. And the deadline for submitting contributions to the call is set to the 1st
of April 2023 23:59 UTC. The contributors will be presenting their
contributions at the 99th JPEG Meeting in April 2023.
The Call
for Contributions on Subjective Image Quality Assessment addresses the development
of a suitable subjective evaluation methodology standard. A second stage will
address the objective perceptual visual quality evaluation models that perform
well and have a good discriminative power in the high quality to near-visually
lossless quality range.
JPEG DNA
The JPEG
Committee has continued its exploration of the coding of images in quaternary
representations, as it is particularly suitable for DNA storage applications.
The scope of JPEG DNA is the creation of a standard for efficient coding of
images that considers biochemical constraints and offers robustness to noise
introduced by the different stages of the storage process that is based on DNA
synthetic polymers. During the 97th JPEG meeting, the JPEG DNA
Benchmark Codec and the JPEG DNA Common Test Conditions were updated to allow
for additional concrete experiments to take place prior to issuing a draft call
for proposals at the next meeting. This will also allow further validation and
extension of the JPEG DNA benchmark codec to simulate an end-to-end image
storage pipeline using DNA and in particular include biochemical noise
simulation which is an essential element in practical implementations.
JPEG XS
The 2nd edition
of JPEG XS is now fully completed and published. The JPEG Committee continues
its work on the 3rd edition of JPEG XS, starting with Part 1 (Core
coding system) and Part 2 (Profiles and buffer models). These editions will
address new use cases and requirements for JPEG XS by defining additional
coding tools to further improve the coding efficiency, while keeping the
low-latency and low-complexity core aspects of JPEG XS. The primary goal of the
3rd edition is to deliver the same image quality as the 2nd
edition, but with half of the required bandwidth. During the 97th JPEG
meeting, a new Working Draft of Part 1 and a first Working Draft of Part 2 were
created. To support the work a new Core Experiment was also issued to further
test the proposed technology. Finally, an update to the JPEG XS White Paper has
been published.
JPEG 2000
A new edition of Rec.
ITU-T T.803 | ISO/IEC 15444-4 (JPEG 2000 conformance) is under development.
This new edition proposes to relax the maximum allowable errors so that
well-designed 16-bit fixed-point implementations pass all compliance tests; adds
two test codestreams to facilitate testing of inverse wavelet and component
decorrelating transform accuracy, and adds several codestreams and files conforming
to Rec. ITU-T 801 |ISO/IEC 15444-2 to facilitate the implementation of decoders
and file format readers
“Motivated by the consumers’ concerns of manipulated contents, the JPEG Committee has taken concrete steps to define a new standard that provides interoperable solutions for a secure and reliable annotation of media assets creation and modifications” said Prof. Touradj Ebrahimi, the Convenor of the JPEG Committee.
Upcoming JPEG meetings are planned as follows:
No 98, will be in Sydney, Australia from 14-20 January 2022
ACM Multimedia 2022 was held in a hybrid format in Lisbon, Portugal from October 10-14, 2022.
This was the first local participation in three years for many participants, as the strict travel restrictions associated with Covid-19 in 2020 and 2021 made it difficult to participate locally by travelling out of the host and neighbouring countries.
In Portugal, the Covid-19 restrictions were almost lifted, and the city was bustling with tourists. Participants were careful to avoid infectious diseases and enjoyed Lisbon’s local wine “Vinho Verde” and cod dishes with their colleagues and engaged in lively discussions about multimedia research.
For many students, this was their first time presenting at an international conference, and it was a wonderful experience.
To encourage student authors to participate on-site, SIGMM has sponsored a group of students with Student Travel Grant Awards. Students who wanted to apply for this travel grant needed to submit an online form before the submission deadline. The selected students received either 1,000 or 2,000 USD to cover their airline tickets as well as accommodation costs for this event. Of the recipients, 25 were able to attend the conference. We asked them to share their unique experience attending ACM Multimedia 2022. In this article, we share their reports of the event.
Xiangming Gu, PhD student, National University of Singapore, Singapore
It is a great honour to receive a SIGMM Student Grant. ACM Multimedia 2022 is my first time attending an academic conference physically. During the conference, I presented my oral paper “MM-ALT: Multimodal Automatic Lyric Transcription”, which was also selected as “Top Rated Papers”. Besides the presentation, I also met a lot of people who shared similar research interests. It was very inspiring to learn from others’ papers and discuss them with the authors directly. Moreover, I was also a volunteer for ACM Multimedia 2022 and attended the session of the 5th International ACM Workshop on Multimedia Content Analysis in Sports. During the session, I learnt how to organize a workshop, which was a great exercise for me. Now, after I come back to Singapore, I still miss the conference. I wish I can get my paper accepted next year and attend the conference again.
Avinash Madasu, Computer Science Master’s student at the University of North Carolina Chapel Hill, USA.
It is my absolute honour to receive the student travel grant for attending the ACM Multimedia 2022 conference. This is the first time I have attended a top AI conference in-person. I enjoyed it a lot during the conference and I was sad that the conference ended quickly. Within the conference days, I was able to attend a lot of oral sessions, keynote talks and poster sessions. I was able to interact with fellow researchers from both academia and industry. I learnt a lot about exciting research going on in my area of interest as well as other areas. It provided a new refreshing experience and I hope to bring this to my research. I presented a poster and felt happy when fellow researchers appreciated my work. Apart from technical details, I was able to forge a lot of new friendships which I truly cherish for my whole life.
Moreno La Quatra, PhD student, Politecnico di Torino
The ACM Multimedia 2022 conference was an amazing experience. After a few years of remote conferences, it was a pleasure to be able to attend the conference in person. I got the opportunity to meet many researchers of different seniorities and backgrounds, and I learned a lot from them. The poster sessions were one of the highlights of the conference. They were a very valuable opportunity to present interesting ideas and explore the details of other researchers’ work. I found the keynotes, presentations, and workshops to be very inspiring and engaging as well. Throughout them, I learned about specific topics and interacted with friendly, passionate researchers from around the world. I would like to thank the ACM Multimedia 2022 organization for the opportunity to attend the conference in Lisbon, all the other volunteers for their friendly and helpful attitude, and the SIGMM Student Travel Grant committee for the financial support.
Sheng-Ming Tang, Master student, National Tsing Hua University, Hsinchu, Taiwan
My name is Sheng-Ming Tang from National Tsing Hua University, Hsinchu, Taiwan. It is a great honour for me to receive the student travel grant. First, I want to thank the committee for organizing this fantastic event. As ACM MM 2022 is my first in-person experience presenting at a conference, I felt a little bit nervous in the first place. However, I started to get comfortable in the conference through the interaction of those astonishing researchers and the volunteers. It was great to not only present in front of the public but also participate in the events. I met a lot of people who solved problems with different and creative approaches, learned brand-new mindsets from the keynote sessions, and gained abundant feedback from the audience, which would boost my research. Thank the committee again for giving me this greatest opportunity to present and share my work in person. I enjoyed a lot during the event.
Tai-Chen Tsai, Graduate student, National Tsing Hua University Taiwan
First, I would like to thank ACM for providing a student travel grant that allowed me to attend the conference. This is my first time presenting my work at a conference. The conference I attended was the interactive art session. I was worried that the setup would be complicated abroad. However, as soon as I arrived at the site, volunteers assisted me with the installation. The conference provided complete hardware resources, allowing me to have a smooth and excellent exhibition experience. Also, I took the opportunity to see many interesting researchers from different countries. The work “Emotional Machines” in the interactive art exhibition surprised me. His system collects and combines what participants are saying and their current emotions. The data is transformed into 360-degree image content in the VR environment through the model so that everyone’s information forms a small universe in the VR environment. The idea is creative. Additionally, I can chat and discuss projects with published researchers while volunteering at workshops. They shared their lifestyle and work experiences as researchers in European countries, and we discussed what interesting study is and what is not. This is the best reward for me.
Bhalaji Nagarajan, PhD Student, Universitat de Barcelona, Spain
ACM-Multimedia was the first big conference I was able to participate in person after two years of complete virtual participation. I presented my work both as oral and poster presentations at the Workshop on Multimedia-Assisted Dietary Management (MADiMa). It gave me an excellent opportunity to present my work and to get valuable input from reputed pioneers regarding the future scope. It gave me a new dimension and helped in expanding my technical skill set. This was also my first volunteering experience on such a massive scale. It gave me a great learning experience to see and learn how to manage conferences of such a large scale. I am very happy that I attended the conference in person. I was able to meet new people, and reputed pioneers in the field, learn new things and of course, made some new friends. A big thank you for the SIGMM Travel Grant that allowed me to attend the conference in-person in Lisbon.
Kiruthika Kannan, MS by Research, International Institute of Information Technology, Hyderabad, India.
My paper on “DrawMon: A Distributed System for Detection of Atypical Sketch Content in Concurrent Pictionary Games” was accepted at the 30th ACM International Conference on Multimedia. It was my first international conference, and I felt honoured to be able to present my research in front of experienced researchers. The conference also exhibited diverse research projects addressing fascinating scientific and technological problems. The poster sessions and talks at the conference improved my knowledge of the research trends in multimedia. In addition to this, I was able to interact with fellow researchers from diverse cultures. It was interesting to hear about their experiences and learn about their work at their institution. As a volunteer at the conference, I witnessed the hard work of the behind the scene organizers and volunteering team to smoothly run the events. I am grateful to the SIGMM Student Travel Grant for supporting my attendance at the ACMMM 22 conference.
Garima Sharma, PhD Student, Department of Human-Centred Computing, Monash University
It was a pleasure to receive a SIGMM travel grant and to attend the ACM Multimedia 2022 conference in person. ACM Multimedia is one of the top conferences in my research area and it was my first in-person conference during my PhD. I had a great experience interacting with numerous researchers and fellow PhD students. Along with all the interesting keynotes, I attended as many oral sessions as possible. Some of these sessions were aligned with my research work and some were outside of my work. This gave me a new research perspective at different levels. Also, working with organisers in a few sessions gave me a whole new experience in managing these events. Overall, I got many insightful comments, suggestions and feedback which motivated me with some interesting directions in my research work. I would like to thank the organisers for making this year’s ACM Multimedia a wonderful experience for every attendee.
Alon Harell, PhD student at the Multimedia Lab at Simon Fraser University
I had the pleasure to receive the SIGMM Student Travel Grant and to attend and volunteer at ACM Multimedia 22 in Lisbon, Portugal. The work I submitted to the conference was done outside of my regular PhD research, and thus without this grant, I would have not been able to participate. The workshop at which I presented, ACM MM Sport 22, was incredibly eye-opening with many fantastic papers, great presentations, and above all great people with which I was able to exchange ideas, form bonds, and perhaps even create future collaborations. The main conference, which coincides more closely with my main research on image and video coding for machines, was just as good. With fascinating talks, some in person, and some virtual, I was exposed to many new ideas (or perhaps just new to me) and learned a great deal. I was also able to benefit from the generosity and experience of Prof. Chong Wah Ngo from Singapore Management University, during my PhD. Mentor lunch, who shared with me his thoughts on pursuing a career in academia. Overall, ACM Multimedia 22 was an especially unique experience because it was the first in-person conference I was able to attend since the beginning of the COVID-19 pandemic, and being back face-to-face with fellow researchers was a great pleasure.
Lorenzo Vaiani, Ph.D. student (1st year), Politecnico di Torino, Italy
ACM MM 2022 was my first in-person conference. Being able to present my works and discuss them with other participants in person was an incredible experience. I enjoyed every activity, from presentations and posters to workshops and demos. I received excellent feedback and new inspiration to continue my research. The best part was definitely strengthening the bonds with friends I already knew and making more with the amazing people I met there. I learned a lot from all of them. Volunteer activities helped a lot in making these kinds of connections. Thanks to the organizers for this fantastic opportunity and the SIGMM Student Travel Grant committee for the financial support. This edition of ACM MM was just the first for me, but I hope for many more in the future.
Xiaoyu Lin, third-year PhD student at Inria Grenoble, France
It is a great honour to attend ACM MM 2022 in Lisbon. It was a great experience. I have met lots of nice professors and researchers. Discussing with them gave me lots of inspiration on both research directions and career development. I presented my work during the doctoral symposium. I’ve got plenty of useful feedback which can help me to improve our work. During the “Ask Me Anything” lunch, I have the chance to discuss with several senior researchers. They provide me with some kind and very useful advice on how to do research. Besides, I have also served as a volunteer for a workshop. It also helped me to meet other volunteers and made some new friends. Thanks to all the chairs and organizers who have worked hard to make ACM MM 2022 such a wonderful conference. It’s really an impressive experience!
I would like to thank the ACM Multimedia Committee provided me with the student travel grant so that I can attend the conference in person. ACM Multimedia is the worldwide top conference in the Multimedia field. It provides me with an opportunity to present my work and communicate with the researchers working on this topic of multimedia search. Besides, the excellent keynotes and passionate panel talk also picture a good vision of future research in the multimedia field. Overall, I must express that ACM MM22 is amazing and well-organized. I again appreciate the ACM MM committee for the student travel grant, which made my attendance possible.
Nitish Nagesh (@nitish_nagesh) is a Ph.D. student in the Computer Science department, the University of California, Irvine, USA. He has been awarded as Best Social Media Reporter of ACM Multimedia 2022 conference. To celebrate this award, Nitish Nagesh reported on his wonderful experience at ACM Multimedia 2022 as follows.
I was excited when our paper “World Food Atlas for Food Navigation” was accepted to the Multimedia Assisted Dietary Management Workshop (MADiMA). Being held in conjunction with ACM Multimedia 2022, the premier multimedia conference was the icing on the cake. It being in Lisbon, Portugal was the cherry on top of the cake. It is said that a picture is worth a thousand words. It is fitting to describe a multimedia conference experience report through pictures.
Prof. Ramesh Jain organized an informal meetup at the Choupana Caffe based on the advice of Joao Magalhaes, general chair of ACMMM 2022. It was great to meet researchers working on food computing including Prof. Yoko Yamakata, Prof. Agnieszka, Maija Kale. It was great to also have the company of students and professors from Singapore Management University including Prof. Chong Wah along with Prof. Phoebe Chen. Since this was the first in-person conference for many folks, we had great conversations over waffles, pear salad and watermelon mint juice!
The MADiMA workshop and the Cooking and Eating Activities (CEA) workshop had stellar keynote speakers and presentations about topics ranging from adherence to a mediterranean diet to mental health estimation through food images.
The workshop was at the Lisbon Congress Center. It was a treat to watch the sun shine brightly on the congress center in the morning and the mellow sunset only a few minutes away near the Tagus Estuary rendering an orangish hue to the red bridge overlooking the train tracks below.
After a great set of presentations, the MADIMA and CEA workshop was drawn to a close with a group picture, of one large family of people who love food and want to help people enjoy food while maintaining their health goals. A huge shout out to the workshop chairs Prof. Stavroula Mougiakakou, Prof. Keiji Yanai, Prof. Dario Allegra and Prof. Yoko Yamakata. (I tried my best to include a photo where everyone looks good!)
All work and no play makes us dull people! And all research with no food makes us hungry people! We had a post-workshop dinner at an authentic Portuguese restaurant. The food was great and it was a delightful evening because of the surprise treat from the professors!
Prof. Jain’s Ph.D. talk was inspiring as he shared his personal journey that led him to focus on healthcare. He urged students in the multimedia community to pursue multimodal healthcare research as he shared his insights on building a personal health navigator.
I had signed up to be a mentee for the Ph.D. school Ask Me Anything (AMA) session. We asked Prof. Ming Dong questions about his time at graduate school, balancing teaching and research responsibilities, tips on maximizing research output and strategies to cope with rejections. He was candid in his responses and emphasized the need to focus on incremental progress while striving to do impactful research. I must thank Prof. Wei Tsang and other organizers for their leadership in organizing a first-of-its-kind session.
In between running around oral sessions, poster presentations, keynote talks, networking, grabbing lunch, and enjoying Portuguese Tart, we managed to have fun while volunteering. Huge credit to the students and staff (the Rafael’s, the Diogo’s, the David’s, the Gustavo’s, the Pedro’s) from Nova university for doing the heavy lifting to ensure a smooth online, hybrid and in-person experience!
It was a pleasure to watch Prof. Alan Smeaton deliver an inspiring speech about the journey of information retrieval and multimedia. The community congratulates you once again on the Technical Achievement Award – more power to you, Alan!
The highlight of the conference was the grand banquet at Centro Cultural de Belém. There could not have been a better climax to the gala event than the Fado music. One aspect of Fado music symbolizes longing where the spouse sings a melancholy when her partner sets sail on long voyages. It is accompanied by the unique 12 string guitar and is sung very close to the audience to heighten the intimacy. I could fully relate to the artists’ melody and rhythms since I had been longing to see my family and friends back home, whom I have not visited for the past three years due to the pandemic. Another tune described the beauty of Lisbon in superlatives including the sun shining the brightest compared to any other part of the world. There was a happy ending to the tune when the artists recreated the moment of joy after the war was over and everyone was merry again. It reinvigorated a fresh hope and breathed a new lease of life into our cluttered worlds. For once, I was truly present in the moment!